LinkedIn thought leader ad examples
49 thought leader ads are live on LinkedIn right now, from 94 companies. Browse real ones, filtered by industry.
- DataPeepsSince 19 Sept 2026
🏃➡️ Vi løber hurtigt, så du ikke behøver at gøre det! 🏃♀️ Vi har flest direkte telefonnumre af alle udbydere ☎️ 👉 OG vi har samlet al den information, du kunne få brug for til B2B og B2C. 👉 OG det hele opdateres uden du skal røre en finger. 👉 OG du får adgang til det via vores portal eller direkte i jeres systemer. 👉 OG så får du en direkte linje til Danmarks bedste dataspecialister! Med god data løber du altid i den rigtige retning – uden at snuble. datapeeps.dk
- CollibraSince 1 Oct 2026
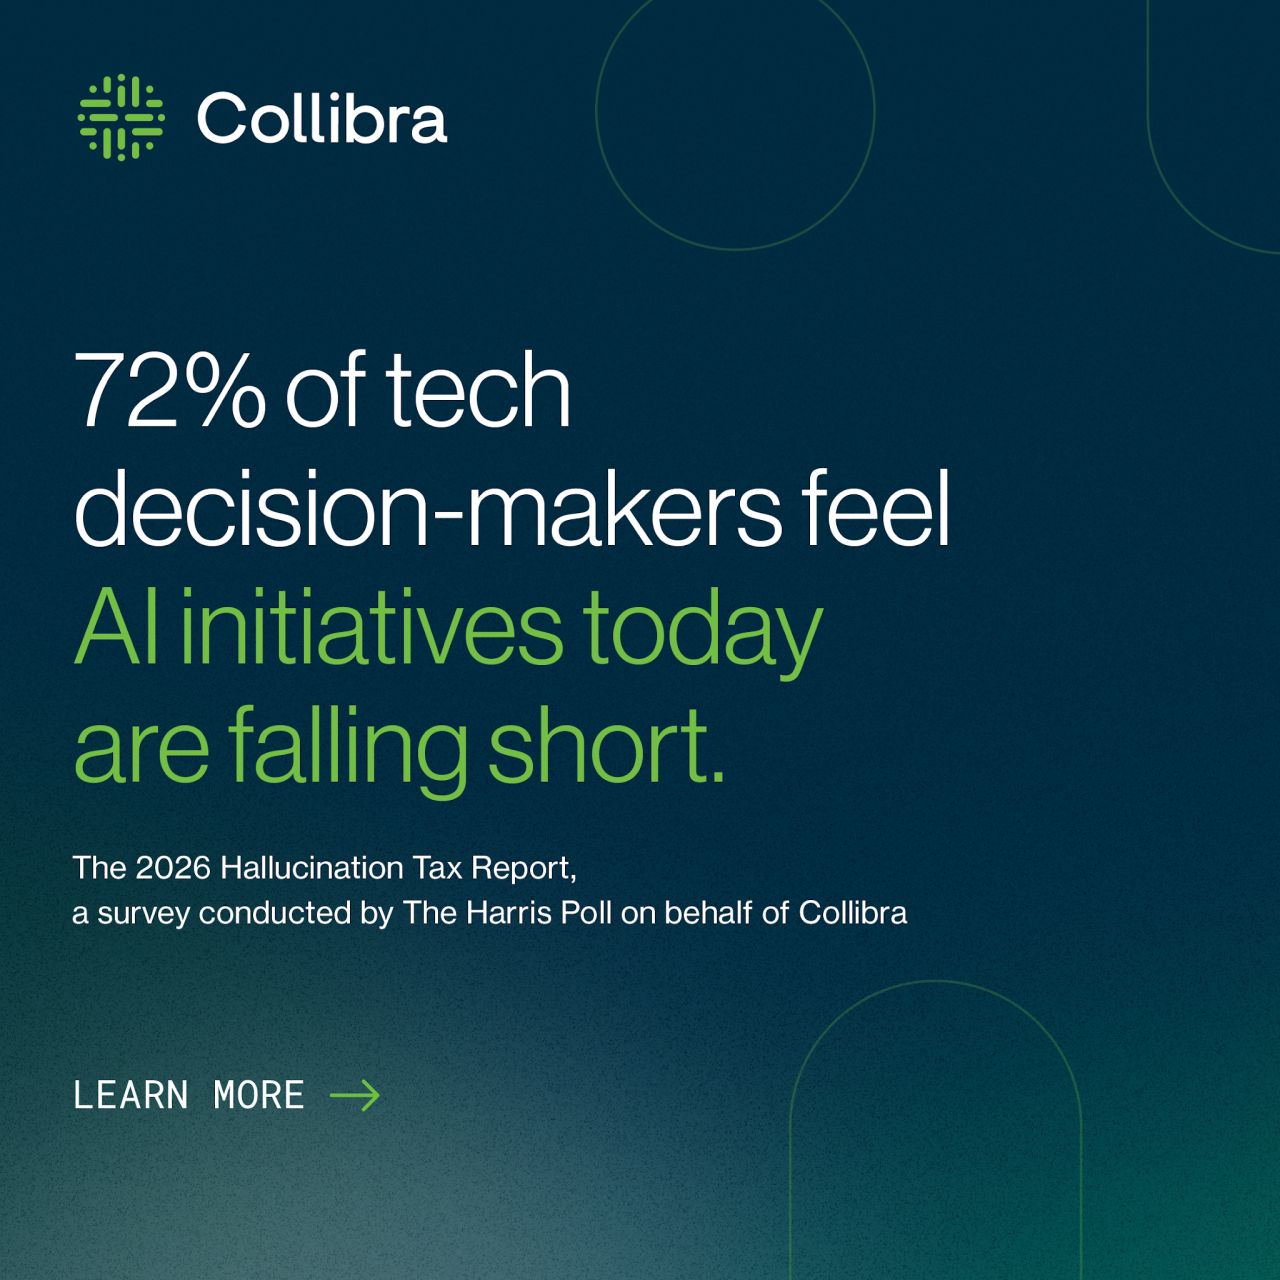
72% of tech decision-makers say their AI initiatives are falling short and the problem isn’t the models. It’s the foundation underneath them. We surveyed more than 300 data, privacy, and AI decision-makers with The Harris Poll for our 2026 Hallucination Tax Report. 76% have hit roadblocks moving AI from pilot to production. 87% say their teams are spending significant time re-verifying the context their agents are working from. That’s the hallucination tax: the hidden cost of manual oversight, rework, and risk that grows with every new agent put into production. It doesn’t show up as a line item. It shows up in teams checking and rechecking AI output. In pilots that struggle to reach production. And ultimately, in a ceiling on how far enterprises can scale AI. A smarter model won’t solve that. Enterprises need governed context and controls built into how agents work, so they can trust AI to act without having a human double-check every step. Read more in our new research with The Harris Poll: https://lnkd.in/et9U234M
- CollibraSince 1 Oct 2026
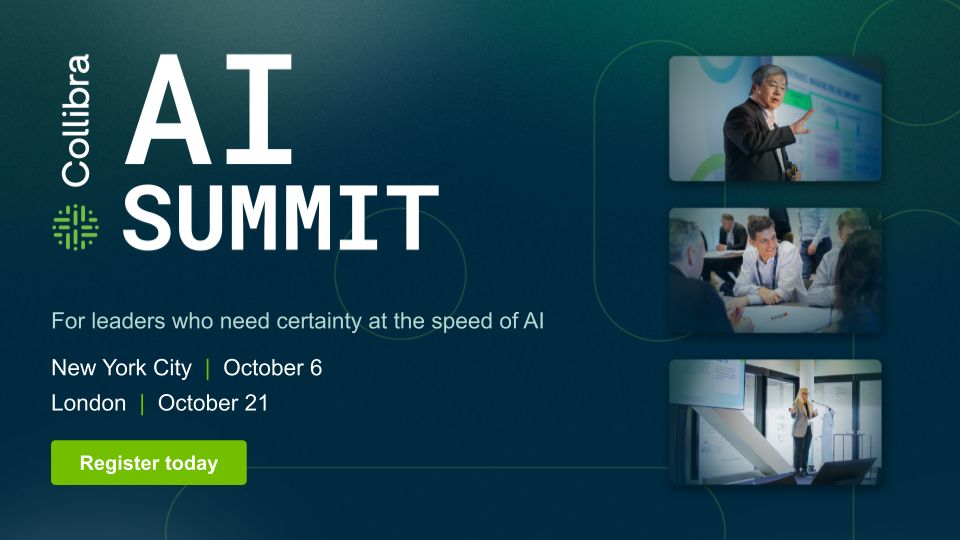
Enterprise AI is moving fast. Trust isn’t keeping up. On October 6, we’re bringing together AI, data and technology leaders in New York City for the Collibra AI Summit to talk about what it actually takes to close that gap. How do you give AI the business context it needs to make better decisions? How do you maintain control as agents become more autonomous? And how do you move from promising pilots to AI you can confidently put into production? We’ll hear directly from leaders working through these questions today and share what we’re learning along the way. If you’re responsible for making AI work in the enterprise, I hope you’ll join us. October 6 | New York City Register: https://lnkd.in/e5WsANn5 #EnterpriseAI #AIGovernance #Collibra
- Inphinity ∞Since 2 Oct 2026
What do Qlik users do after reading a dashboard? Our use-case analysis answers that ↓ We serve 400 customers, and we have mapped 105 use cases. 63.0% in operational data and reporting. 60.9% in planning and forecasting. 32.6% in data management and governance. 10.9% in workflows and approvals. Many customers use Inphinity in more than 1 domain. Here's the important distinction: Writeback describes the movement of data. It does not describe the form people use, the validation rules, the calculations, the permissions, the audit history or the actions that follow. Put those pieces together inside Qlik and you have a business application. A Qlik-native application layer built around governed data interaction. So the question has shifted from: “Do you need writeback?” To: “What business process still leaves Qlik for a spreadsheet, email, or disconnected legacy application?”
- EMARKSince 2 Oct 2026
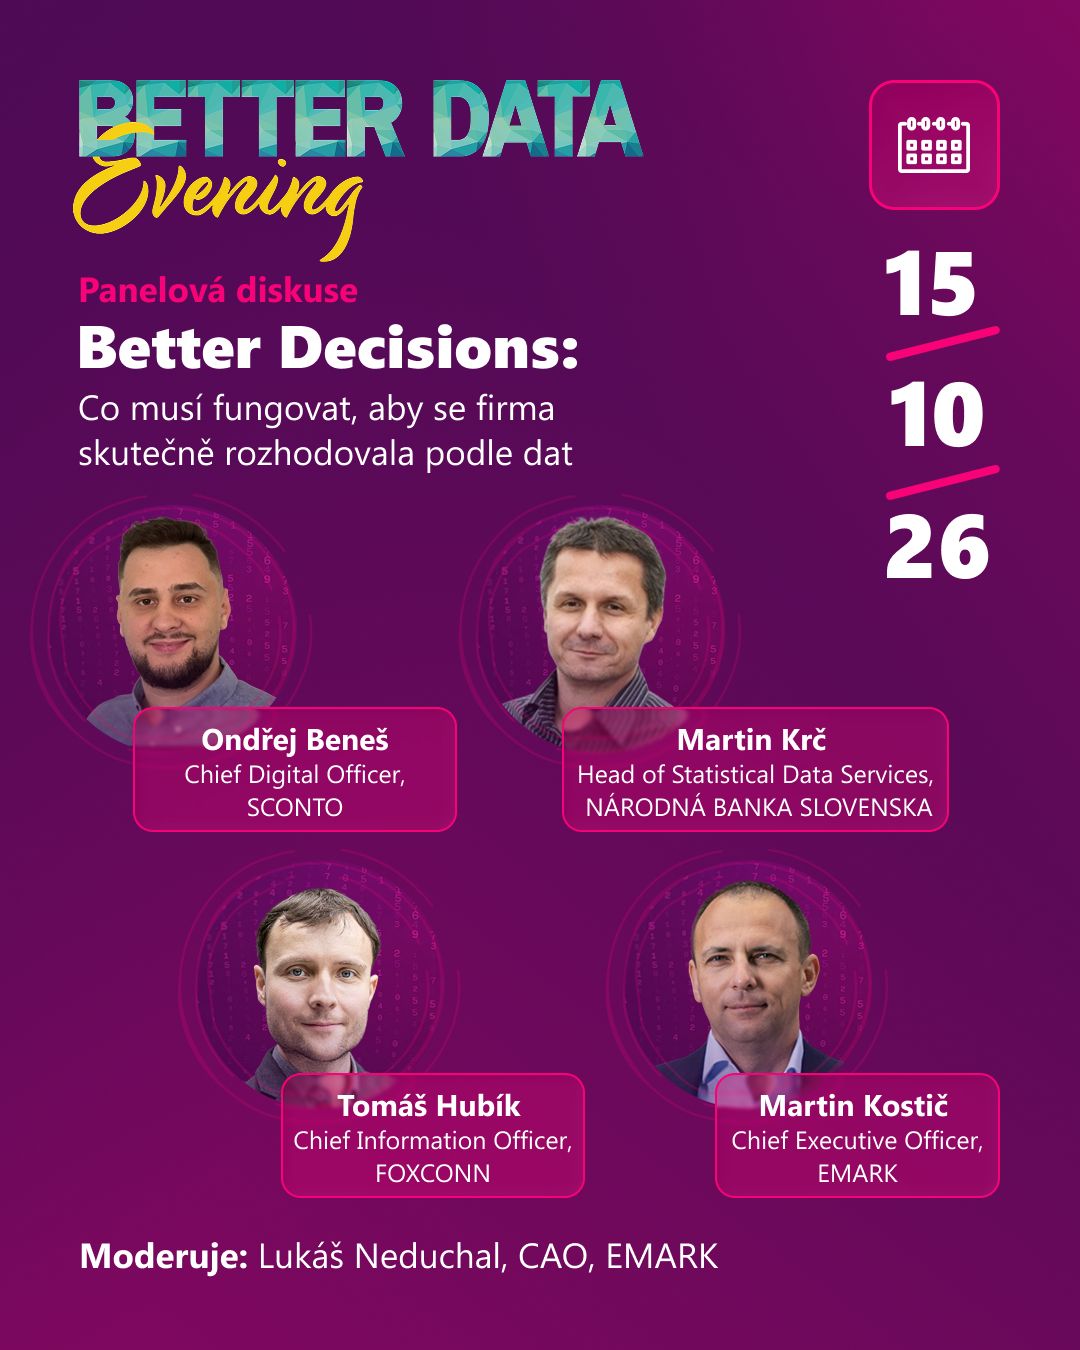
Co musí fungovat, aby se firma skutečně rozhodovala na základě dat? Na Better Data Evening budu moderovat panelovou diskusi, kde se na toto téma podíváme ze čtyř různých perspektiv. V panelu se potkají: Tomáš Hubík (Chief Information Officer, Foxconn Česká republika), Ondrej B. (Chief Digital Officer, SCONTO Nábytek Česká republika), Martin Krc (Head of Statistical Data Services, Národná banka Slovenska), Martin Kostic (Chief Executive Officer, EMARK). Budeme mluvit o důvěře v data, interní spolupráci, praktických zkušenostech z projektů i AI podpoře rozhodování. 𝟏𝟓. 𝟏𝟎. 𝟐𝟎𝟐𝟔 | 𝐁𝐞𝐭𝐭𝐞𝐫 𝐃𝐚𝐭𝐚 𝐄𝐯𝐞𝐧𝐢𝐧𝐠 | 𝐎𝐑𝐄𝐀 𝐇𝐨𝐭𝐞𝐥 𝐀𝐧𝐠𝐞𝐥𝐨, 𝐏𝐫𝐚𝐡𝐚 Registrujte se zdarma na 👉 https://lnkd.in/dNtUqdx5
- Dairy Data Warehouse (DDW)Since 3 Oct 2026
What's the role of onboarding in data as a service companies in the dairy industry? I recently fielded some questions on how onboarding drives value for our customers at Dairy Data Warehouse (DDW) from Feed & Additive Magazine. https://lnkd.in/eNPhcfh8
- Dairy Data Warehouse (DDW)Since 3 Oct 2026
I was pleased to be invited for an interview to discuss how Dairy Data Warehouse (DDW) is helping shape the future of dairy farming through data and AI. At DDW, we believe that better connected data can support smarter decisions, stronger farm performance, and more sustainable dairy operations. Thank you to Alberta Farmer Express and Farmtario for sharing the article. https://lnkd.in/gGCviiDV
- EXPLORESince 6 Oct 2026
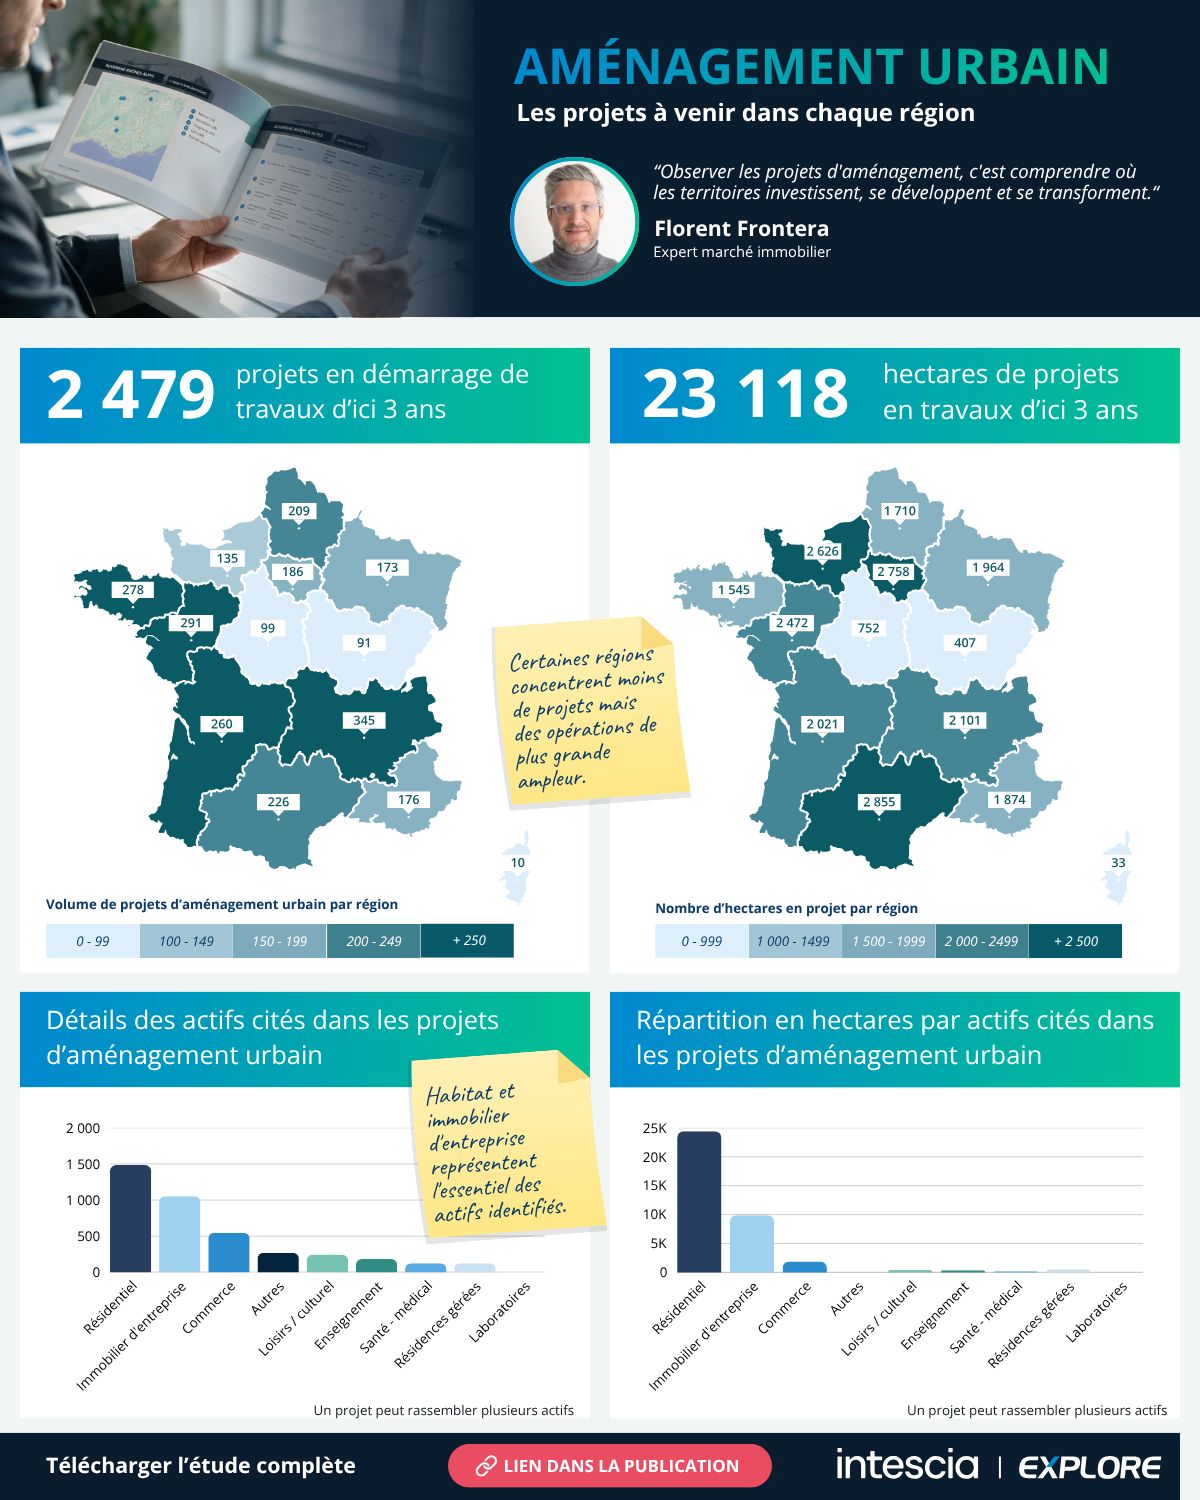
Professionnels de l'immobilier, quelle est la meilleure façon de prévoir les marchés de demain ? 💡 En Observant les projets que les collectivités préparent aujourd'hui : ✅ 2 479 projets d'aménagement urbain identifiés ✅ 23 118 hectares en projet ✅ Des opérations réparties sur l'ensemble du territoire 📥 L'étude complète est disponible en téléchargement ici 👉 https://hubs.ly/Q04z6_080 A consommer sans modération pour orienter votre stratégie de développement 😊 Bonne lecture !!
- C&FSince 25 Sept 2026
Resilience isn't just protecting the physical network. It's protecting the decision system behind it: the one that senses risk, escalates it, acts, and learns. Miss that, and the network alone won't save you.
- Coalesce.ioSince 6 Oct 2026
The new Coalesce local agentic data engineering experience is now GA! 🎉 About nine months ago, the team started a top-to-bottom rethink of Coalesce with a simple question: how do we build the best agentic SQL editing experience while keeping the core product values our customers love? Well… we've been busy! Today we're announcing new tools that feel familiar (and are fully compatible with your existing Coalesce Projects!), but are built for teams using Claude Code, Cursor, and Cortex Code (CoCo) to build SQL pipelines on Snowflake, Databricks, and BigQuery: - Local editing in the coa CLI—runs off your local files and gives the agent immediate feedback as it makes changes 🚀 - Coalesce Desktop (Mac, Windows, and Linux)—a visual review app that helps you see and understand the AI's changes in real time 🤩 - Native .sql file support—for teams who prefer a SQL-native approach 🔥 - Coalesce MCPs and platform skills 😎 Thank you to our customers for their early feedback, and huge shout out to everyone at Coalesce that made this happen! 🙌 https://lnkd.in/gSjiCPt9
- definitySince 21 Sept 2026
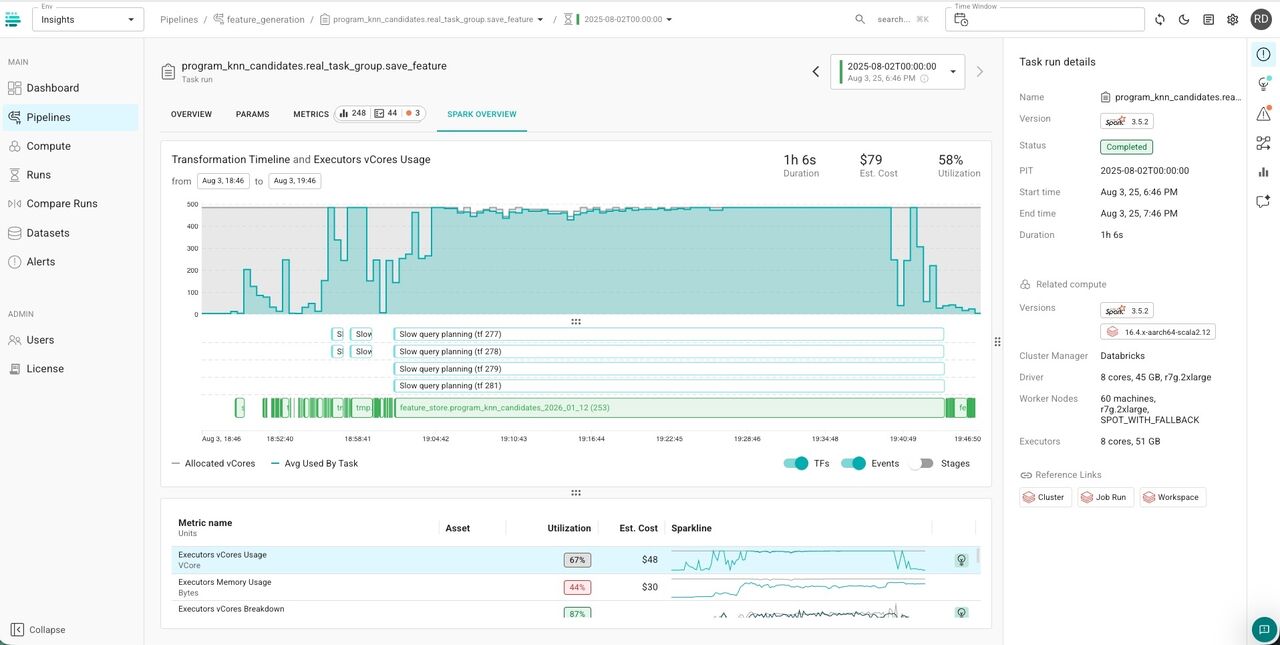
The layer where Spark waste shows up is often not the layer where you need to fix it. High compute utilization, long stages, spill, or expensive shuffles are useful signals. But they can easily lead you toward an obvious optimization – and the wrong one. In one case, I was investigating an expensive KNN workload with high compute utilization and a ~10K-line query plan. Runtime cardinality showed a long-running stage spending half its time sorting ~13B intermediate records – most of which were discarded later in the plan. The fix wasn’t compute tuning. It was changing the application logic to reduce the data earlier in the execution. 𝗦𝗼 𝗵𝗼𝘄 𝗱𝗼 𝘆𝗼𝘂 𝗴𝗲𝘁 𝗳𝗿𝗼𝗺 𝘁𝗵𝗲 𝘀𝘆𝗺𝗽𝘁𝗼𝗺 𝘁𝗼 𝘁𝗵𝗲 𝗮𝗰𝘁𝘂𝗮𝗹 𝗼𝗽𝘁𝗶𝗺𝗶𝘇𝗮𝘁𝗶𝗼𝗻? Trace the execution across infrastructure, Spark runtime, data access, and the physical query plan. Look at executor allocation, task distribution, I/O, shuffle and spill, and operator-level cardinality. The goal is to follow where the work is created, where it accumulates, and where it can actually be eliminated. Roy Daniel and I wrote about this framework and four real production cases in 𝗜𝗻𝘃𝗲𝘀𝘁𝗶𝗴𝗮𝘁𝗶𝗻𝗴 𝗦𝗽𝗮𝗿𝗸 𝗪𝗮𝘀𝘁𝗲 𝗔𝗰𝗿𝗼𝘀𝘀 𝘁𝗵𝗲 𝗦𝘁𝗮𝗰𝗸, now on the Data Engineer Things blog.
- Blueway SoftwareSince 18 Sept 2026
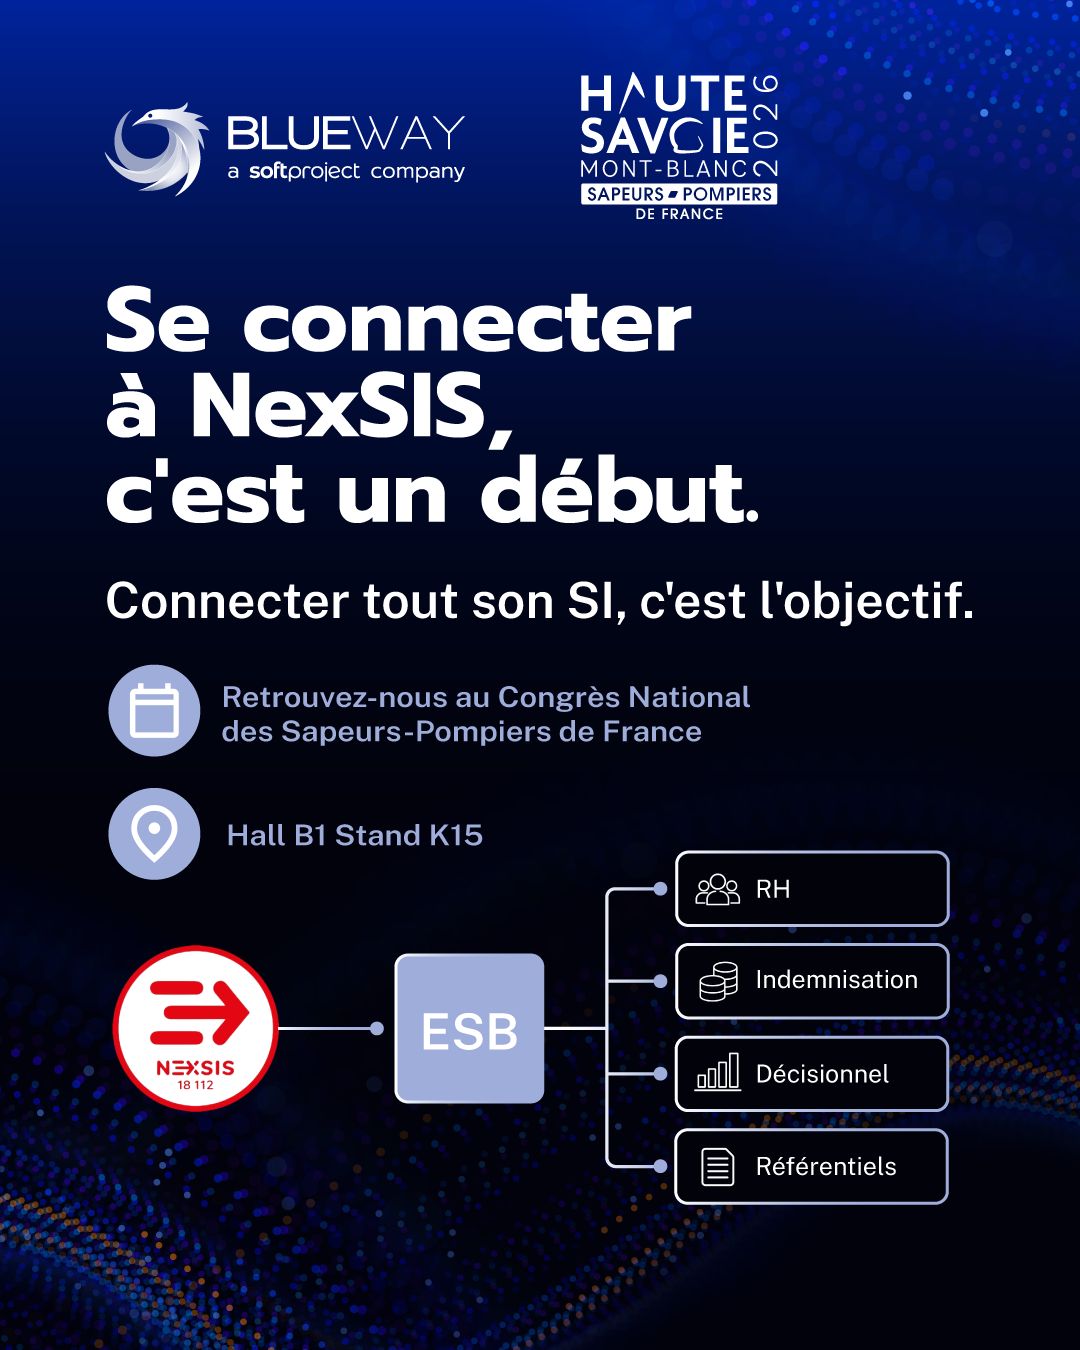
Se connecter à NexSIS, c'est un début. Connecter tout son SI, c'est l'objectif. Avec l'échéance NexSIS, beaucoup de SDIS modernisent leurs échanges avec la plateforme nationale. C'est essentiel — mais c'est une première marche. Car un SDIS, ce n'est pas un système isolé : c'est un écosystème d'applications métiers (RH, indemnisation, décisionnel, référentiels agents…) qui doivent, elles aussi, dialoguer. Standardiser les échanges inter-SDIS, c'est bien. Assurer les échanges avec l'ensemble des parties prenantes et briques internes, c'est aller au bout de la logique. C'est précisément le rôle d'un socle d'interopérabilité (ESB) : 🔹 Décloisonner les applications d'un SI souvent hétérogène 🔹 Fiabiliser et transformer les données entre systèmes 🔹 Industrialiser les échanges plutôt que multiplier les traitements manuels 🔹 Préparer une véritable urbanisation, souple et évolutive, pour les usages de demain Les organisations les plus avancées ne se contentent pas de « brancher » une nouvelle plateforme : elles posent les fondations d'un SI durable, où chaque donnée circule au bon endroit, au bon moment. Parce que l'interopérabilité n'est pas une contrainte réglementaire : c'est un investissement dans la résilience. 📍 Retrouvez l'équipe Blueway Software / SoftProject au Mondial Secours Protection 2026 Haute-Savoie Mont-Blanc Alexis de Saint JeanStyven BARRAQUANDRaphaël BARRAT Cyril Blain #RéponseAuxUrgences #SapeursPompiers #SécuritéCivile #Interopérabilité #Urbanisation #OpérationsConnectées
- DATPROF - Test Data SimplifiedSince 23 Sept 2026
Replacing customer names with "John Doe" and email addresses with "[email protected]" might feel like you’ve checked the compliance box. But it hasn't. It is what I call lazy masking. And it’s a direct threat to both your data security and your release velocity. When you apply basic, surface-level masking to complex enterprise databases: ❌ Integration tests break because cross-system referential integrity gets destroyed. ❌ QA teams lose days debugging phantom errors that turn out to be data issues. We recently ran a Proof of Concept with an enterprise client, and they uncovered a staggering statistic: 50% of all reported pipeline bugs were not software defects at all. They were caused entirely by bad, inconsistent test data. Under regulations like GDPR and DORA, real compliance isn't just about hiding a name. It requires deterministic masking logic and metadata-driven rules across your entire landscape. Real Test Data Management means achieving 100% compliance without breaking your integration pipelines or slowing down your developers. Curious what a modern, enterprise-ready data masking solution actually requires? I've outlined the 6 non-negotiable features in a blog article. Link in comment.
- FraymSince 24 Sept 2026
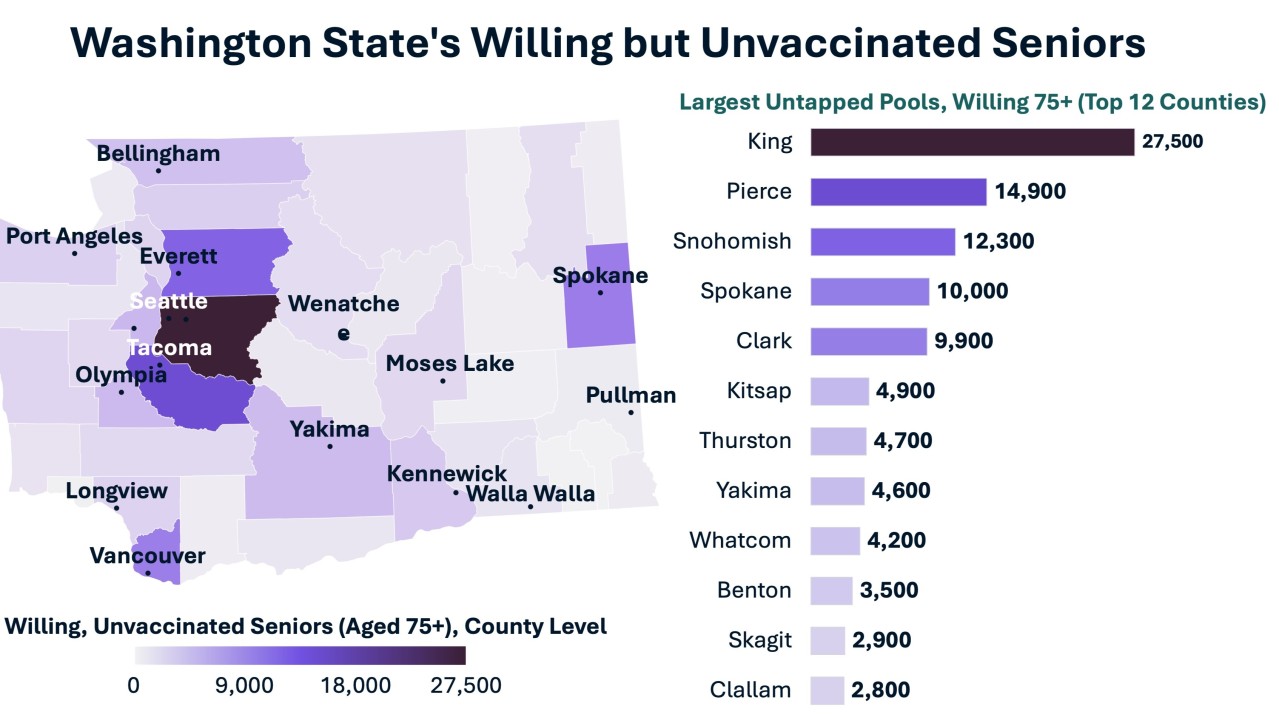
5.5M seniors want the RSV vaccine but haven't gotten it. Here is how we find them. #HealthcareMarketing #PublicHealth #HealthData #VaccineStrategy #RSV
- DATPROF - Test Data SimplifiedSince 29 Sept 2026
Most IT leaders believe their test data strategy is covered because their relational databases are masked. But here is a $400k+ blind spot: masking alone doesn't solve the release bottleneck. In enterprise environments, especially across banking, insurance, and logistics, testing relies on heavy, complex databases. Because resetting a full test database takes 4 to 6 hours, teams simply stop doing it. Instead, a web of expensive workarounds emerges: 1. Engineers spend hours searching through polluted data for "close enough" test scenarios. 2. Teams manually craft data screen-by-screen to bypass missing records. 3. Chain tests get skipped or production copies are used to "save time" (a direct GDPR & DORA violation). I quantified the exact cost of these daily workarounds. The result? For a mid-sized engineering team of 30, poor test data management costs over $421,800 annually in lost productivity, delayed releases, and late defects. True software delivery speed requires moving away from multi-hour refreshes toward automated subsetting and dynamic data generation, reducing reset times from hours to under 20 minutes. I've written this white paper about it and I'd love to hear what you think. Link in first comment.
- Dash0Since 30 Sept 2026
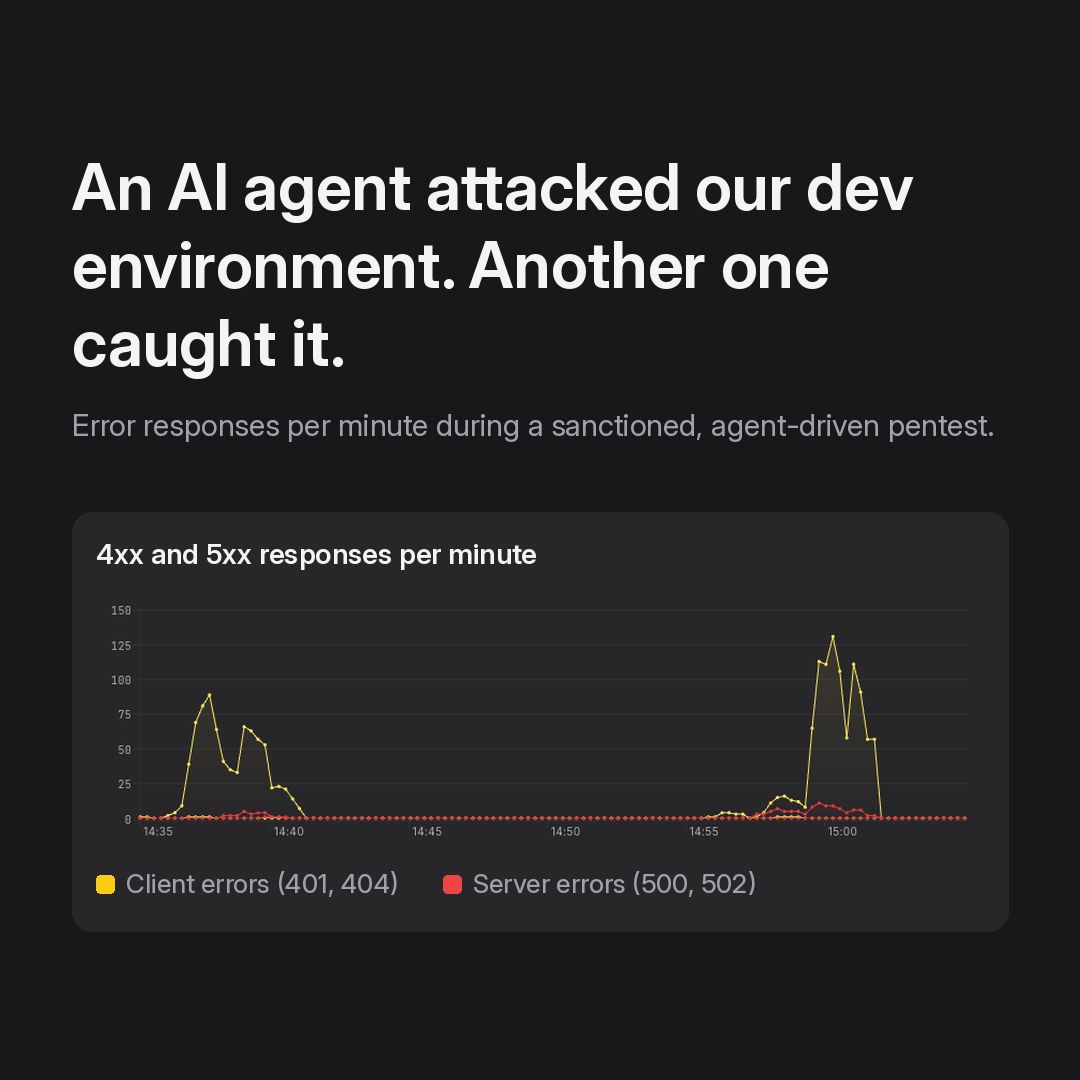
This week an AI agent attacked our dev environment, and another AI agent caught it. Morpheus, from our friends at Cenobe Cybersecurity, ran a fully agent-driven pentest against us from the outside. Agent0 alerted us the moment it started. From there we just asked it questions: what's being hit, from where, what's failing. The whole investigation happened in a chat. Agent0 was never meant to be a security tool. We built it as an SRE helper. But it already reads all our logs, so pointing it at security took almost no work. That's what excites me. It's never been cheaper to just try something.
- FraymSince 1 Oct 2026
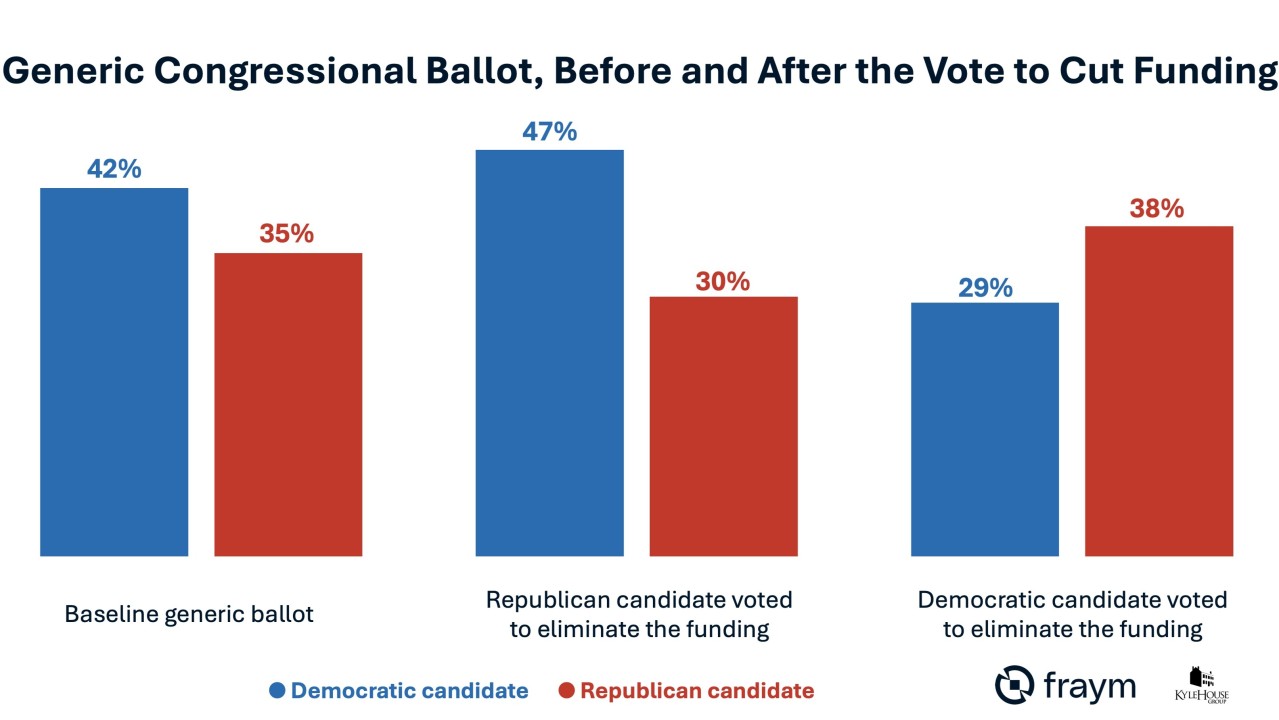
A new national poll of 16,000+ Americans from Fraym and Kyle House Group reveals that 78% of U.S. adults support funding global childhood immunization, including majorities in all 435 House districts. #PublicOpinion #PublicHealth #GlobalHealth #Immunization #ForeignAssistance #DataForImpact
- GreybeamRecorded 8 Oct 2026
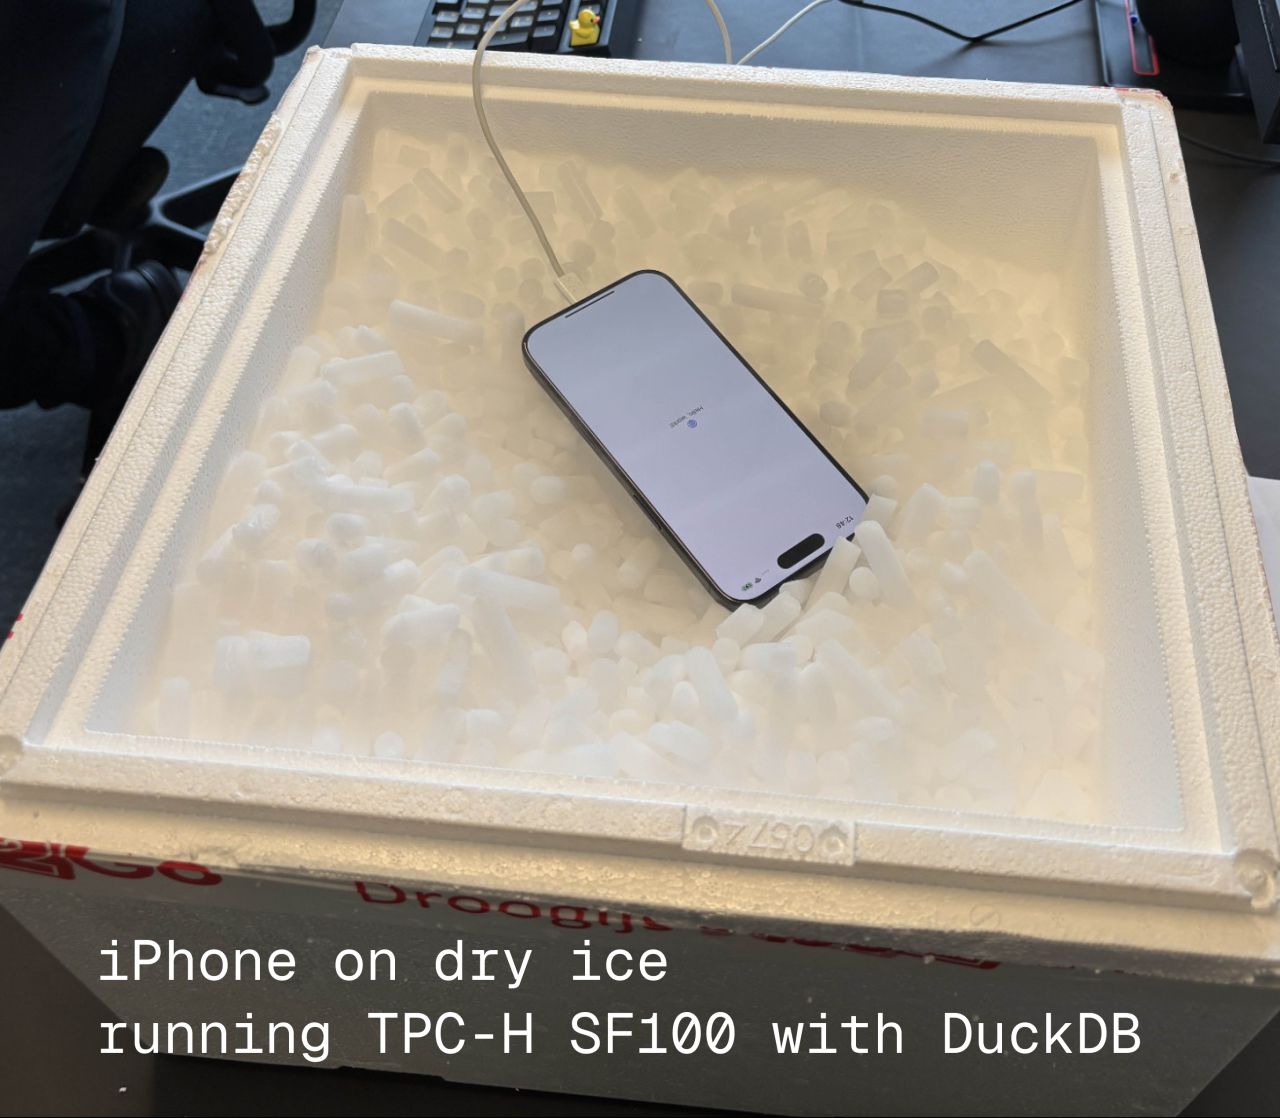
A laptop running DuckDB can regularly match the performance of warehouses costing seven figures a year. Why is it so damn fast? How is it possible that it can run the TPC-H SF100 benchmark in 478s on an iPhone 16 Pro, and 235s on a Galaxy S24 Ultra? Greybeam sends millions of queries to DuckDB, so I had to figure it out. Turns out it's not just its fancy vectorized execution or morsel driven parallelism or columnar storage. It's all of those things! And a set of deliberate design decisions based on decades of database research. In Part 1 of our DuckDB internals series, I walk through a high level of what happens between you submitting a SQL query and execution: → Why in-process execution is fast → The 33 query optimizers DuckDB ships with → Columnar storage, row groups, and zone maps → Why querying Parquet can be as fast as a DuckDB table Read Part 1 here 👇 https://lnkd.in/eGyb_Nn2 p.s. we need a rematch of iPhone vs Android 👀
- Anyshift.ioRecorded 7 Oct 2026
"At a business level nothing is precious. Everything is disposable.” AI Builder #9 💫: Eli Schleifer | CEO & Co-founder, Trunk What changes when you can test a product idea in a day instead of spending months building it? For Eli, AI changes more than how fast engineers write code. It changes how quickly they can learn, change direction, and throw away something that doesn't work. His most effective teams today? “Teams of like two or three.” Smaller groups, larger areas of ownership, with each engineer guiding their own agents. And maybe the hardest skill to learn: getting comfortable deleting what you just built. As Eli puts it, “We should be very happy to throw away our most precious things if they're getting in the way.” Thanks Eli for joining us!
- Anyshift.ioRecorded 7 Oct 2026
AI Builder #10 💫: Jeffrey Snover | PowerShell inventor, Google Distinguished Engineer For Jeffrey, the most underrated shift in AI is the dramatic reduction in cost. “Engineering’s all about trade-offs.” And the cost assumptions behind those trade-offs keep changing. His point: don’t just make the same system cheaper. Ask what you would build if you had 1,000 times more capacity. But cheaper doesn’t mean more reliable. At Harvard, he’s building a neurosymbolic system that combines LLMs with explicit rules and checks. Why? “There are things where the errors matter.” Being able to explain a decision matters too. And where would he put $10M? “I would short frontier models.” He thinks the efficiency gains ahead could undermine the economics of today’s most expensive models. Thanks Jeffrey for joining us!
- Aggregate IntelligenceSince 18 Mar 2026
Sharing some feedback from latest TravelTech part of ITB Berlin2026! #ITBBerlin2026 #TravelTech #DataIntelligence #RevenueManagement #NDC #AgentReadyData #CompetitiveIntelligence #AIReadiness
- Aggregate IntelligenceSince 27 Mar 2026
BLUF: Enterprise AI initiatives will fail if they are fueled by legacy, unstructured data dumps. Because modern AI is designed to confidently predict rather than verify, feeding it static data causes highly convincing but dangerous "hallucinations" that can severely damage revenue margins. To safely automate pricing and revenue decision-making, organizations must transition to "Agent-Ready Data"—semantically structured, on-demand intelligence explicitly tagged with machine-readable metadata and agent instructions that grounds AI in true market reality and entirely eliminates guesswork.
- QlikSince 19 Sept 2026
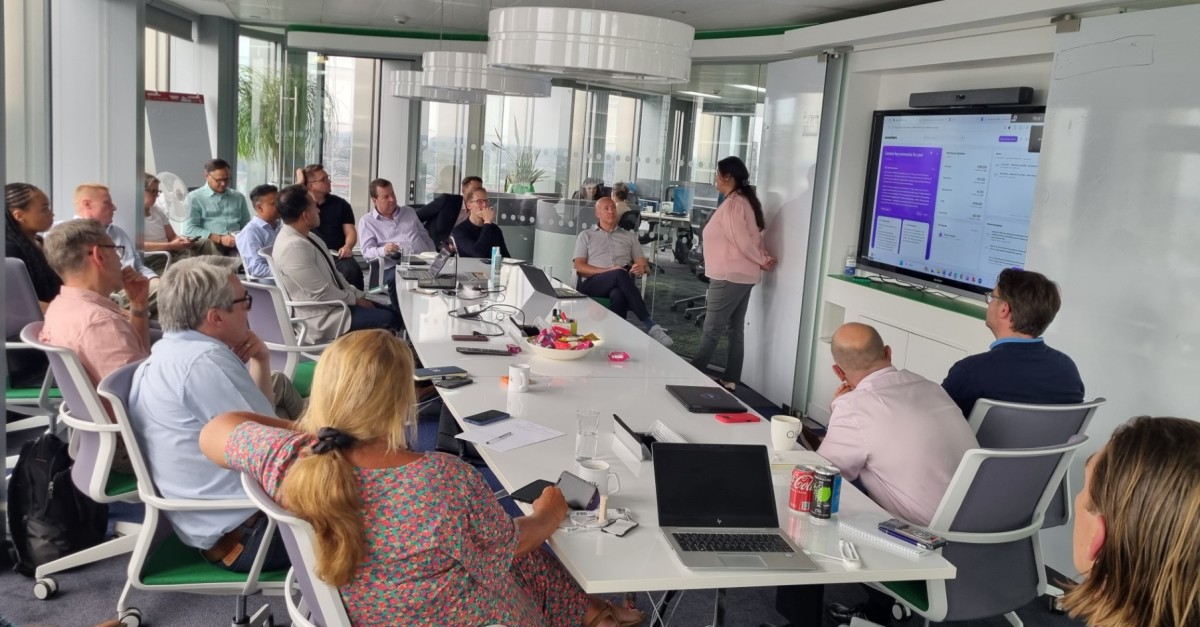
The future of analytics will be defined by the trust it has in AI-driven decisions. As data environments become increasingly complex, many organizations face a growing trust gap: fragmented information, inconsistent governance, and difficulty turning insights into action at scale. Qlik and Accenture are collaborating to help organizations address this challenge through trusted agentic analytics and have launched a new AI4BI accelerator. By combining Qlik's governed and connected data foundation with Accenture's expertise in AI agents, knowledge orchestration, and industry-specific playbooks, organizations can equip both people and AI with the context needed to make faster, more informed decisions. The result is more than better analytics. It's a trusted intelligence foundation that enables scalable AI adoption, accelerates time to value, and helps organizations move confidently from insight to action. Thank you to Monica Gupta for joining us in London to demonstrate our new joint asset to our leadership team that is now available and will help clients unlock the full potential of trusted, AI-powered decision-making. I'm excited by the opportunities this collaboration creates for our customers.
- QlikSince 18 Sept 2026
Cost. Effort. Time. Those are the three things I hear holding back even the most willing customers from modernizing. We’ve just removed one of them. We’ve launched a new offer for our smaller Qlik Sense and QlikView client-managed customers: a path to Qlik Cloud at roughly what they already pay today. No cost surprises. No compromise on the AI, automation, and analytics capabilities they've been waiting to access. This isn't only an SMB story. I've always believed every Qlik customer, of every size, deserves a real path to modernization. This is one more program built to get them there. Of course, none of this works without partners. Here’s how we support you: • Migration tooling: the fully supported Qlik Analytics Migration Tool is live now, including a new QlikView and Qlik Sense to Qlik Cloud converter at no extra cost. Details in the Qlik Migration Center: https://bit.ly/4cBuKlW • Partner Portal Move to Cloud page: https://bit.ly/4xymvze • Standard partner discounts stay fully in place. Every migration is a chance to deepen the relationship. More users, more use cases, more services. We've already helped hundreds of customers and partners move tens of thousands of users and applications to Qlik Cloud. This offer opens that door to thousands more. To every partner with a customer who's wanted to modernize but couldn't justify it until now: let's talk. I'm excited about how many more of these stories we get to write together.
Other LinkedIn formats
Watch the companies you care about.
Filter every ad by industry, country, format and network, and get alerts when a company you watch starts running new ads.