On air · 2 of 3 networks
DATPROF - Test Data Simplified
- datprof.com
- Data
- NL
- 19 employees
DATPROF - Test Data Simplified’s ads on LinkedIn, Meta and Google, recorded by adsrunning. Browse the latest here for free. Sign up free to see all 24. Watch DATPROF - Test Data Simplified with Starter to get each new one in your feed.
Watchlist with Starter · $49/mo
| Network | Status | Live ads | Nov 2025LinkedIn activity · 52 weeksOct 2026 | Checked | Next step |
|---|---|---|---|---|---|
| Running | 8 | Checked 28 Oct 2026 | See all 24 ads → | ||
| Meta | Not checked | — | |||
| Running | 21 | Ads on the Google Ads Transparency Center | Checked 26 Oct 2026 | Collect them with the API → |
DATPROF - Test Data Simplified has 8 live LinkedIn ads. We recorded 21 Google ads on 26 Oct 2026.
Latest ads
- LINKEDIN · IMAGESince 20 Oct 2026
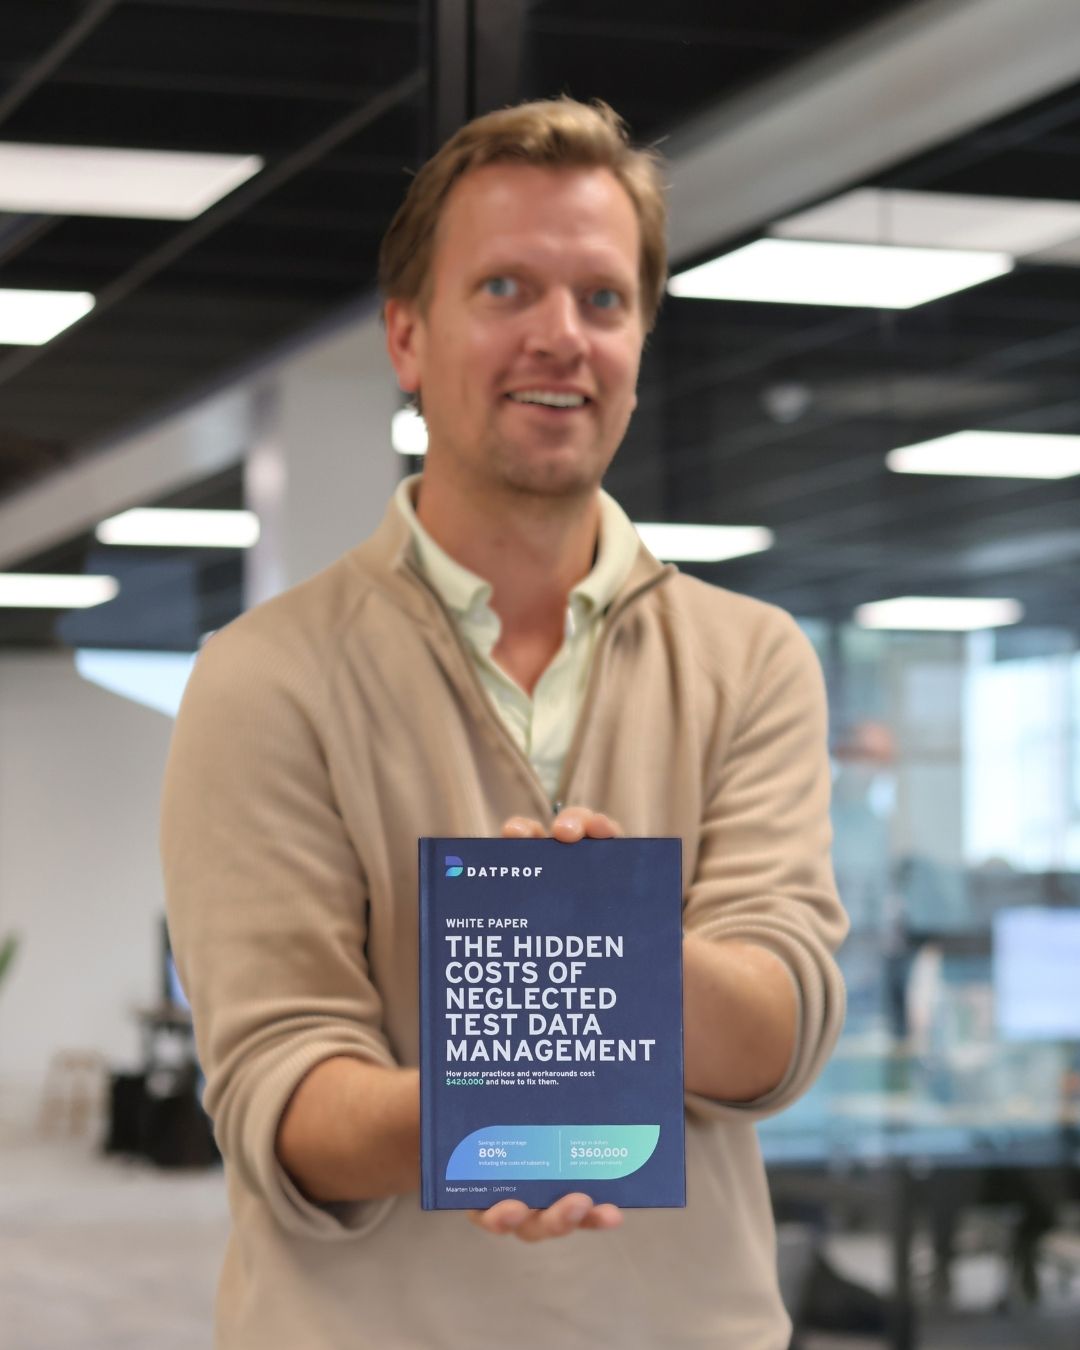
When a database refresh takes 4 to 6 hours, something deeply human happens: teams simply stop doing it. And right at that point, an invisible drain opens in your IT budget. In our latest research, we calculated the true cost of neglected Test Data Management for a 30-person engineering team. Even with extremely conservative assumptions, we uncovered a shocking outcome: $421,800 per year in hidden waste. Where is that money going? • 45 minutes per test case lost searching for usable data in a polluted database. • 40 minutes per test case wasted manually creating test scenarios. • Rework and recovery effort caused by incomplete testing leading to bugs that leak into production. When refreshes take hours, teams improvise. They test on outdated garbage or skip chain testing entirely. The solution isn't more manual labor; it's reducing the data load. By switching from massive production copies to lean, representative subsets, you bring refresh times down from hours to 20 minutes. That single shift immediately removes $350,000+ in annual waste from your operation. I wrote this white paper about it and I'd love to hear what you think. Link in first comment.
- LINKEDIN · IMAGESince 20 Oct 2026
Most QA teams don’t actually have a testing problem. They have a test data problem that cuts their sprint velocity in half. Ask an average QA Lead where most of their sprint time goes, and the answer is rarely "writing automated test scripts." It’s almost always: · Waiting on the DBA for a fresh database refresh. · Searching for hours to find that one specific customer edge case in a massive, polluted database. · Manually faking data in Excel or Notepad because crucial test scenarios are missing. Industry research shows that testers spend 30% to 50% of their time just preparing test data. That isn’t quality assurance. That’s operational overhead. As long as your testing department relies on 'DBA goodwill' for a refresh, true Continuous Delivery is an illusion. Real agility only happens when QA engineers get self-service access to fresh, masked, and subsetted test data via a simple portal or CI/CD pipeline integration. How many hours is your team losing this week searching for usable data?
- LINKEDIN · VIDEOSince 9 Oct 2026
How do you decide between synthetic data and masked production data? During the Q&A of our DATPROF Customer Webinar yesterday, I discussed this question with Bert Nienhuis. It’s one of the most persistent debates in Test Data Management (TDM), but in reality, you don't have to choose. Use synthetic data early in your SDLC for fast unit testing and new features where production data doesn't exist yet. Switch to masked, subsetted production data further down the pipeline for integration and regression testing, where real-world business logic and historical edge cases are essential to catch critical bugs. Stop looking for a single magic solution. True TDM maturity is about placing the right tool at the right stage of your delivery pipeline. 👇 Want to watch the full Customer Webinar? Link in comments.
- LINKEDIN · VIDEOSince 6 Oct 2026
Sharing a single test database across multiple teams isn’t collaboration. It’s an accident waiting to happen. Here is a scenario I see at enterprise organizations all the time: 1. Team A executes a test run that alters or corrupts state data. 2. Team B’s automated pipeline fails 10 minutes later because the data was altered. 3. Developers waste 3 hours debugging "ghost bugs" caused by dirty data instead of broken code. 4. Everyone lodges a ticket with the DBA team for a refresh and waits... again. When test environments are centralized and shared, speed dies. To scale software delivery without blowing up your infrastructure costs or triggering GDPR privacy risks, you need to decouple your teams. How? 🔹 Ditch full terabyte production copies. Reduce databases to 10% representative subsets. 🔹 Give every team their own isolated, virtual copy of that subset that resets in seconds, not hours. 🔹 Let QA engineers refresh their own clean state via CI/CD pipelines without waiting on DBAs. When teams own their test data in isolation, workarounds disappear, release delays drop, and test coverage actually hits 100%. Read the full breakdown on organizing test data across enterprise teams. Link in comments.
- LINKEDIN · IMAGESince 29 Sept 2026
Most IT leaders believe their test data strategy is covered because their relational databases are masked. But here is a $400k+ blind spot: masking alone doesn't solve the release bottleneck. In enterprise environments, especially across banking, insurance, and logistics, testing relies on heavy, complex databases. Because resetting a full test database takes 4 to 6 hours, teams simply stop doing it. Instead, a web of expensive workarounds emerges: 1. Engineers spend hours searching through polluted data for "close enough" test scenarios. 2. Teams manually craft data screen-by-screen to bypass missing records. 3. Chain tests get skipped or production copies are used to "save time" (a direct GDPR & DORA violation). I quantified the exact cost of these daily workarounds. The result? For a mid-sized engineering team of 30, poor test data management costs over $421,800 annually in lost productivity, delayed releases, and late defects. True software delivery speed requires moving away from multi-hour refreshes toward automated subsetting and dynamic data generation, reducing reset times from hours to under 20 minutes. I've written this white paper about it and I'd love to hear what you think. Link in first comment.
- LINKEDIN · VIDEOSince 23 Sept 2026
Replacing customer names with "John Doe" and email addresses with "[email protected]" might feel like you’ve checked the compliance box. But it hasn't. It is what I call lazy masking. And it’s a direct threat to both your data security and your release velocity. When you apply basic, surface-level masking to complex enterprise databases: ❌ Integration tests break because cross-system referential integrity gets destroyed. ❌ QA teams lose days debugging phantom errors that turn out to be data issues. We recently ran a Proof of Concept with an enterprise client, and they uncovered a staggering statistic: 50% of all reported pipeline bugs were not software defects at all. They were caused entirely by bad, inconsistent test data. Under regulations like GDPR and DORA, real compliance isn't just about hiding a name. It requires deterministic masking logic and metadata-driven rules across your entire landscape. Real Test Data Management means achieving 100% compliance without breaking your integration pipelines or slowing down your developers. Curious what a modern, enterprise-ready data masking solution actually requires? I've outlined the 6 non-negotiable features in a blog article. Link in comment.
6 of 24 adsSign up to see every DATPROF - Test Data Simplified ad, filter by format and date, and get alerts on new ones.
See all 24 adsWatch the companies you care about.
Filter every ad by industry, country, format and network, and get alerts when a company you watch starts running new ads.