On air · 1 of 3 networks
Greybeam
- greybeam.ai
- Data
- US
- 9 employees
Greybeam’s ads on LinkedIn, Meta and Google, recorded by adsrunning. Browse the latest here for free. Sign up free to see all 39. Watch Greybeam with Starter to get each new one in your feed.
Watchlist with Starter · $49/mo
| Network | Status | Live ads | Nov 2025LinkedIn activity · 52 weeksOct 2026 | Checked | Next step |
|---|---|---|---|---|---|
| Running | 39 | Checked 29 Oct 2026 | See all 39 ads → | ||
| Meta | Not checked | — | |||
| None recorded | 0 | No ads found on the Google Ads Transparency Center | Checked 30 Oct 2026 | Collect them with the API → |
Greybeam has 39 live LinkedIn ads. We recorded no Google ads on 30 Oct 2026.
Latest ads
- LINKEDIN · IMAGERecorded 21 Sept 2026
If you’re still serving analytics directly from Snowflake, you’re burning money. We just released a playbook with Scott Vickers, CTO at Headset, who serves embedded analytics to 2500+ users. Here are 3 things he did to drastically reduce Snowflake costs while keeping performance fast and reliable: 1. Switched from Airbyte to Estuary. 2. Custom dbt macro for warehouse sizing. 3. Used Greybeam to serve analytics via DuckDB (saving 83%). Normally, moving workloads to a different engine means rewrites, migrations, and months of pain. Scott avoided all of it. Greybeam handles routing and translation automatically, he got the efficiency of DuckDB without having to rewrite SQL, rebuild his semantic layer, or move data. We documented the full blueprint below. 👇
- LINKEDIN · IMAGERecorded 21 Sept 2026
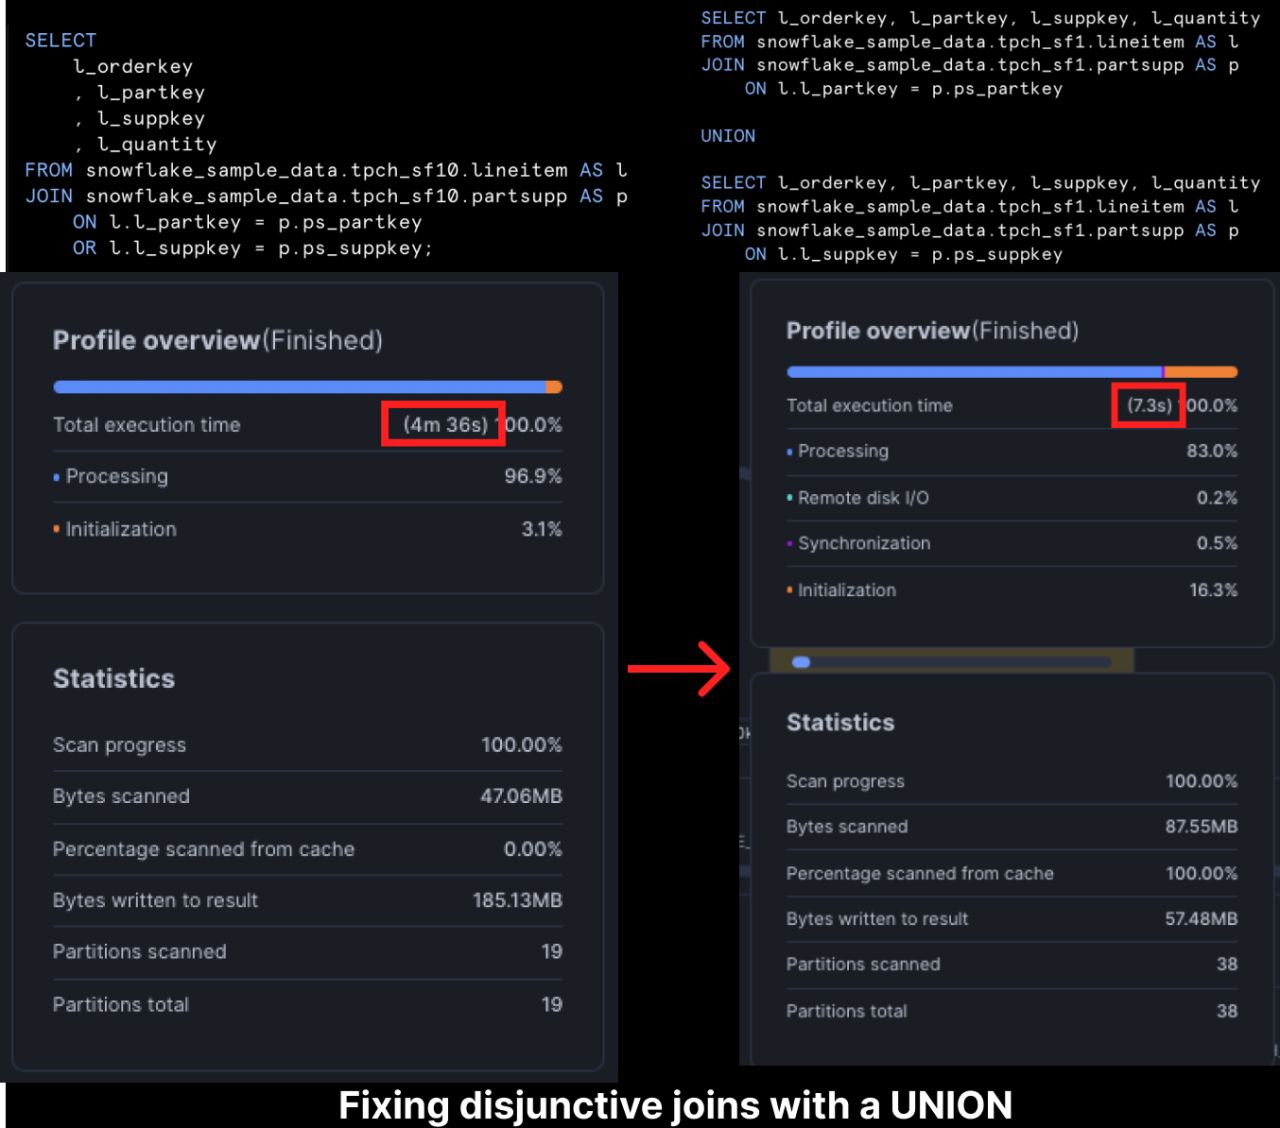
The cleaner your SQL looks, the worse it might perform. Take this perfectly readable join: FROM orders JOIN customers ON orders.customer_id = customers.id OR orders.legacy_customer_id = customers.id Looks elegant. Runs terribly. Why? Snowflake can't use hash joins with OR conditions! There is no longer one clear key to partition on and the query optimizer has to account for matches on either column. The ugly fix that actually works: SELECT * FROM orders JOIN customers ON orders.customer_id = customers.id UNION SELECT * FROM orders JOIN customers ON orders.legacy_customer_id = customers.id Less readable but nearly 40x faster. This OR join pattern shows up everywhere and it's just one of many innocent looking query patterns that destroy performance. I just wrote a blog that deep dives into 7 ways to make your queries run faster. The others include: - Join optimization - Query pruning - Proper use of warehouse cache - Choosing the right query engine If your queries are slow and expensive, these patterns might be why. 👇 https://lnkd.in/g_v7PjPM edit: the SF10 on the left is a screenshot error. If we run the same query on SF10 it would've taken 2h 57m!
- LINKEDIN · IMAGERecorded 21 Sept 2026
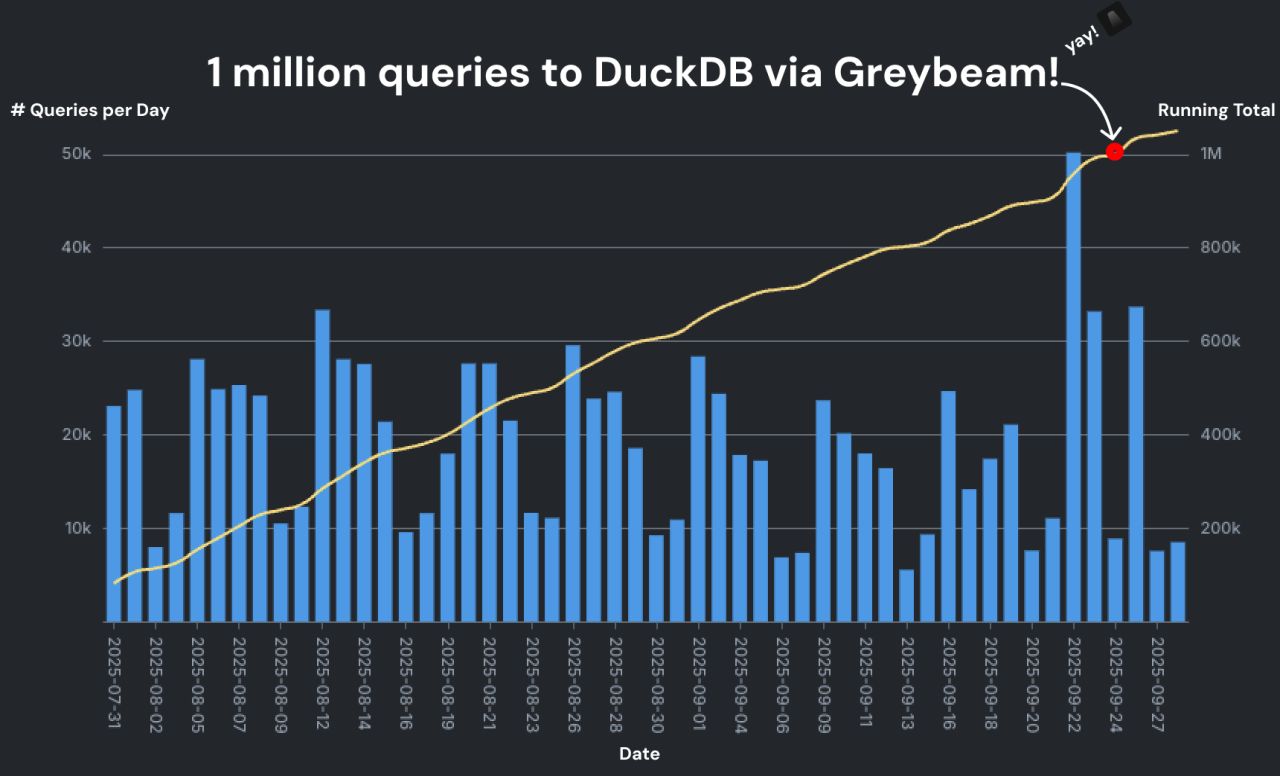
1 million queries routed to DuckDB. 82% cost savings. 10x faster queries on average. One of our earliest Greybeam customers just crossed this milestone 🎉 At the beginning of this year when Arsham and I started buildig Greybeam, we hypothesized that executing Snowflake queries on DuckDB would save customers up to 70% on their workloads. Now that we've been in production for some months with a small handful of customers, we will need to revise this number. For some workloads, we've seen this number reach a staggering 95% while making queries faster on average. It's amazing to see how far we've come, and even more amazing to deliver on our original promise. See you at 10 million!
- LINKEDIN · IMAGERecorded 16 Oct 2026
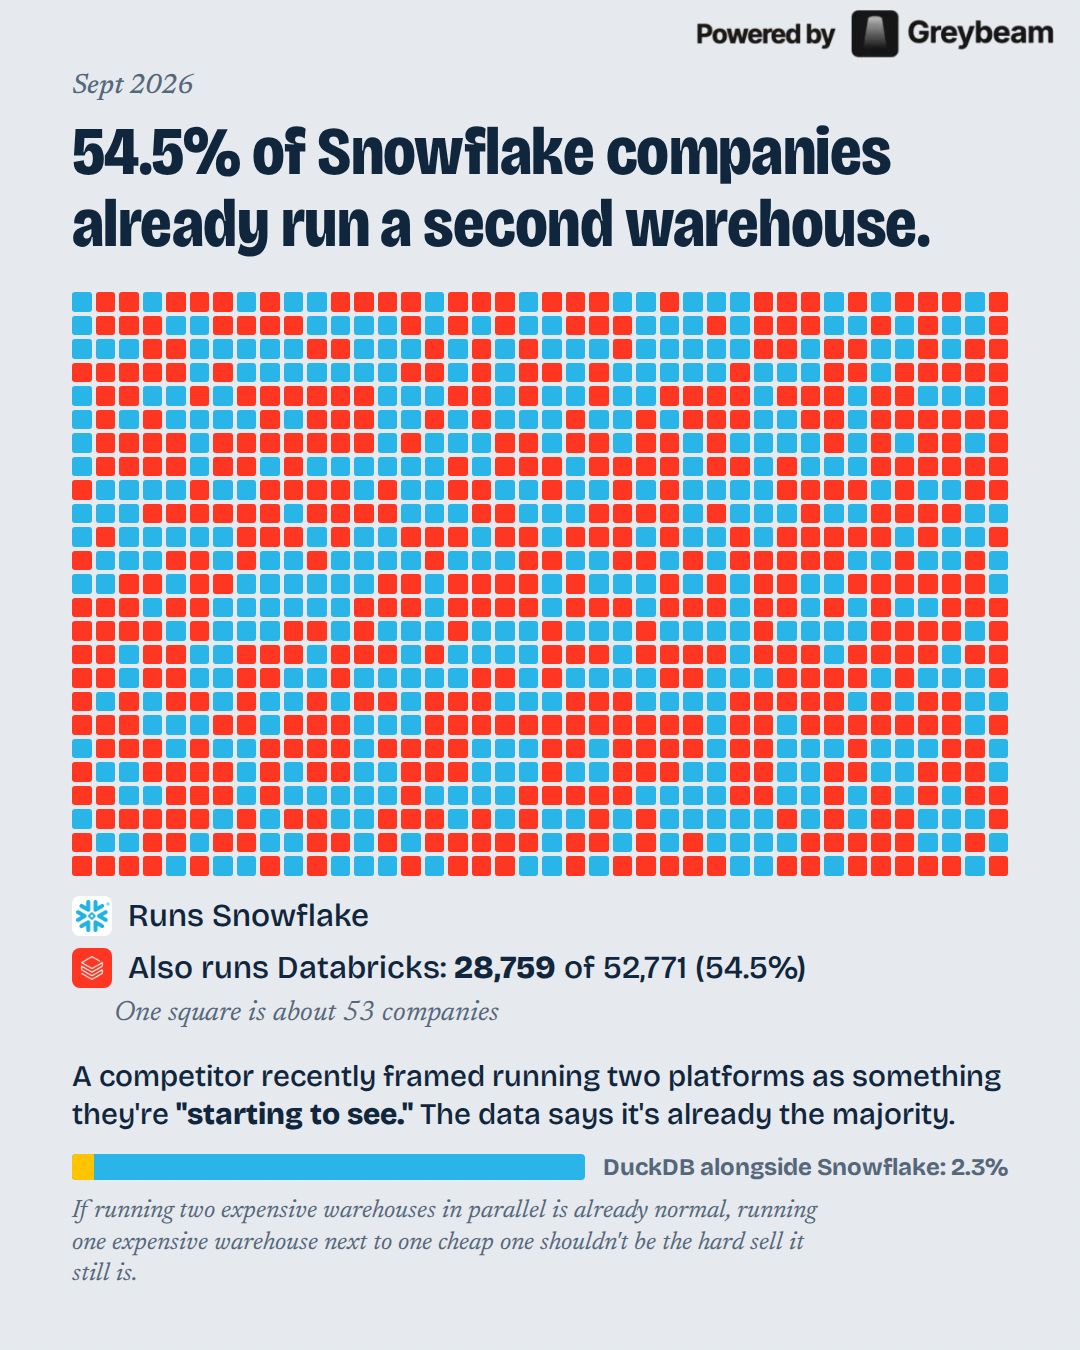
We've normalized running two expensive warehouses before we've normalized running one expensive warehouse and one cheap one. 54.5% of Snowflake companies also use Databricks. Just 2.3% use DuckDB alongside Snowflake. So the barrier clearly isn’t “we don’t want another execution engine.” The interesting question is why it’s still unusual to route the right workloads somewhere dramatically cheaper. Source: Crustdata (YC F24)
- LINKEDIN · IMAGERecorded 16 Oct 2026
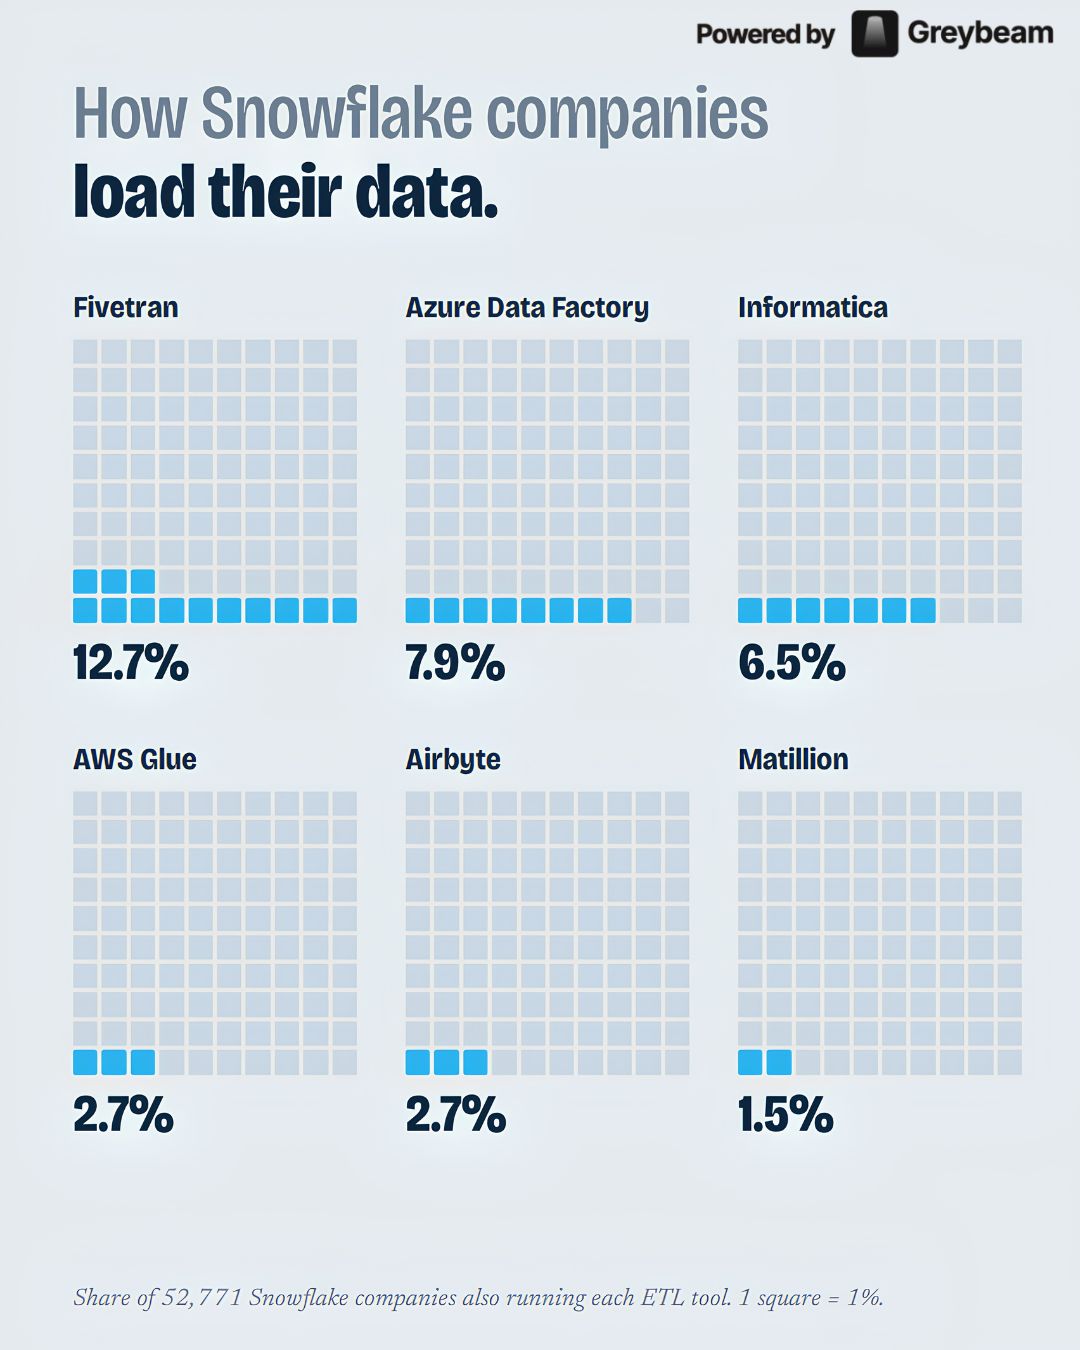
We looked at how 52,771 Snowflake companies get data into Snowflake. → 12.7% run Fivetran → 7.9% run Azure Data Factory → 6.5% run Informatica → 2.7% run AWS Glue → 2.7% run Airbyte → 1.5% run Matillion Very surprised to not see folks like Estuary or Streamkap up there! Source: Crustdata (YC F24)
- LINKEDIN · IMAGERecorded 8 Oct 2026
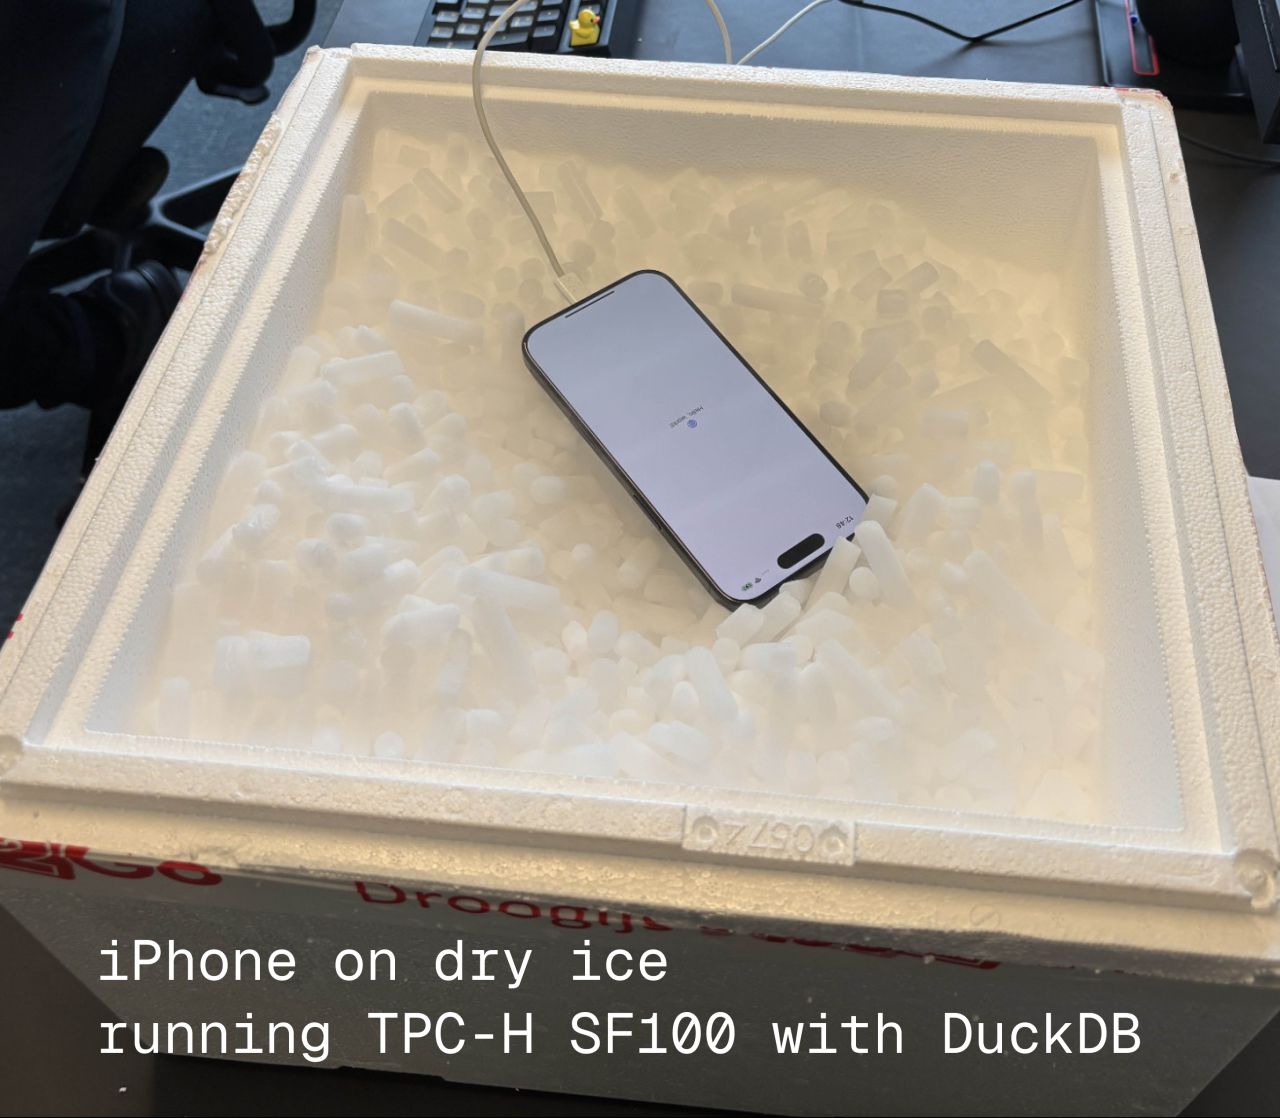
A laptop running DuckDB can regularly match the performance of warehouses costing seven figures a year. Why is it so damn fast? How is it possible that it can run the TPC-H SF100 benchmark in 478s on an iPhone 16 Pro, and 235s on a Galaxy S24 Ultra? Greybeam sends millions of queries to DuckDB, so I had to figure it out. Turns out it's not just its fancy vectorized execution or morsel driven parallelism or columnar storage. It's all of those things! And a set of deliberate design decisions based on decades of database research. In Part 1 of our DuckDB internals series, I walk through a high level of what happens between you submitting a SQL query and execution: → Why in-process execution is fast → The 33 query optimizers DuckDB ships with → Columnar storage, row groups, and zone maps → Why querying Parquet can be as fast as a DuckDB table Read Part 1 here 👇 https://lnkd.in/eGyb_Nn2 p.s. we need a rematch of iPhone vs Android 👀
6 of 39 adsSign up to see every Greybeam ad, filter by format and date, and get alerts on new ones.
See all 39 adsWatch the companies you care about.
Filter every ad by industry, country, format and network, and get alerts when a company you watch starts running new ads.