B2B ad examples
473 B2B ads are live on LinkedIn right now, from 210 companies. Browse real ones, filtered by industry.
- NebiusSince 27 Oct 2026
JUST IN: Nebius just launched Physical AI Workbench, an open-source framework built in collaboration with NVIDIA that gives robotics teams one place to run the entire physical AI development cycle. Data generation. Simulation. Training. Evaluation. All connected. All agent-operable. The problem it solves is real. Building physical AI means stitching together tools that each have their own dependencies, data formats and infrastructure requirements. Moving outputs between stages takes custom scripts. Repeating an experiment requires careful tracking of every scene, dataset and checkpoint. When one tool changes, the whole pipeline breaks. Workbench replaces all of that with a single CLI — npa — that a coding agent can operate directly. The results customers are already reporting: → Up to 40% reduction in engineering time → Iteration cycles cut from weeks to days → 14-stage sim-to-real reference workflow, from task definition to a checkpoint ready for hardware testing The NVIDIA integration is deep. Workbench now includes NVIDIA Cosmos Data Factory built on Cosmos 3, runs on Isaac Sim and Isaac Lab for simulation, Isaac GR00T for robot policy models, and NVIDIA SONIC for humanoid behavior. The first real-world proof point is with Sereact, the German AI robotics company already deployed with Zalando, IKEA, BMW, DHL and Mercedes-Benz. Together they built a sim-to-real pipeline for returns handling at Zalando, one of the hardest warehouse processes to automate given the variability of returned items. Available now on GitHub under Apache 2.0. The infrastructure layer of physical AI is being built in Europe. 🇪🇺📊 Learn more here: https://lnkd.in/d4XgSjFN ~~ ♻️ Join the weekly robotics newsletter, and never miss any news → ziegler.substack.com
- NebiusSince 27 Oct 2026
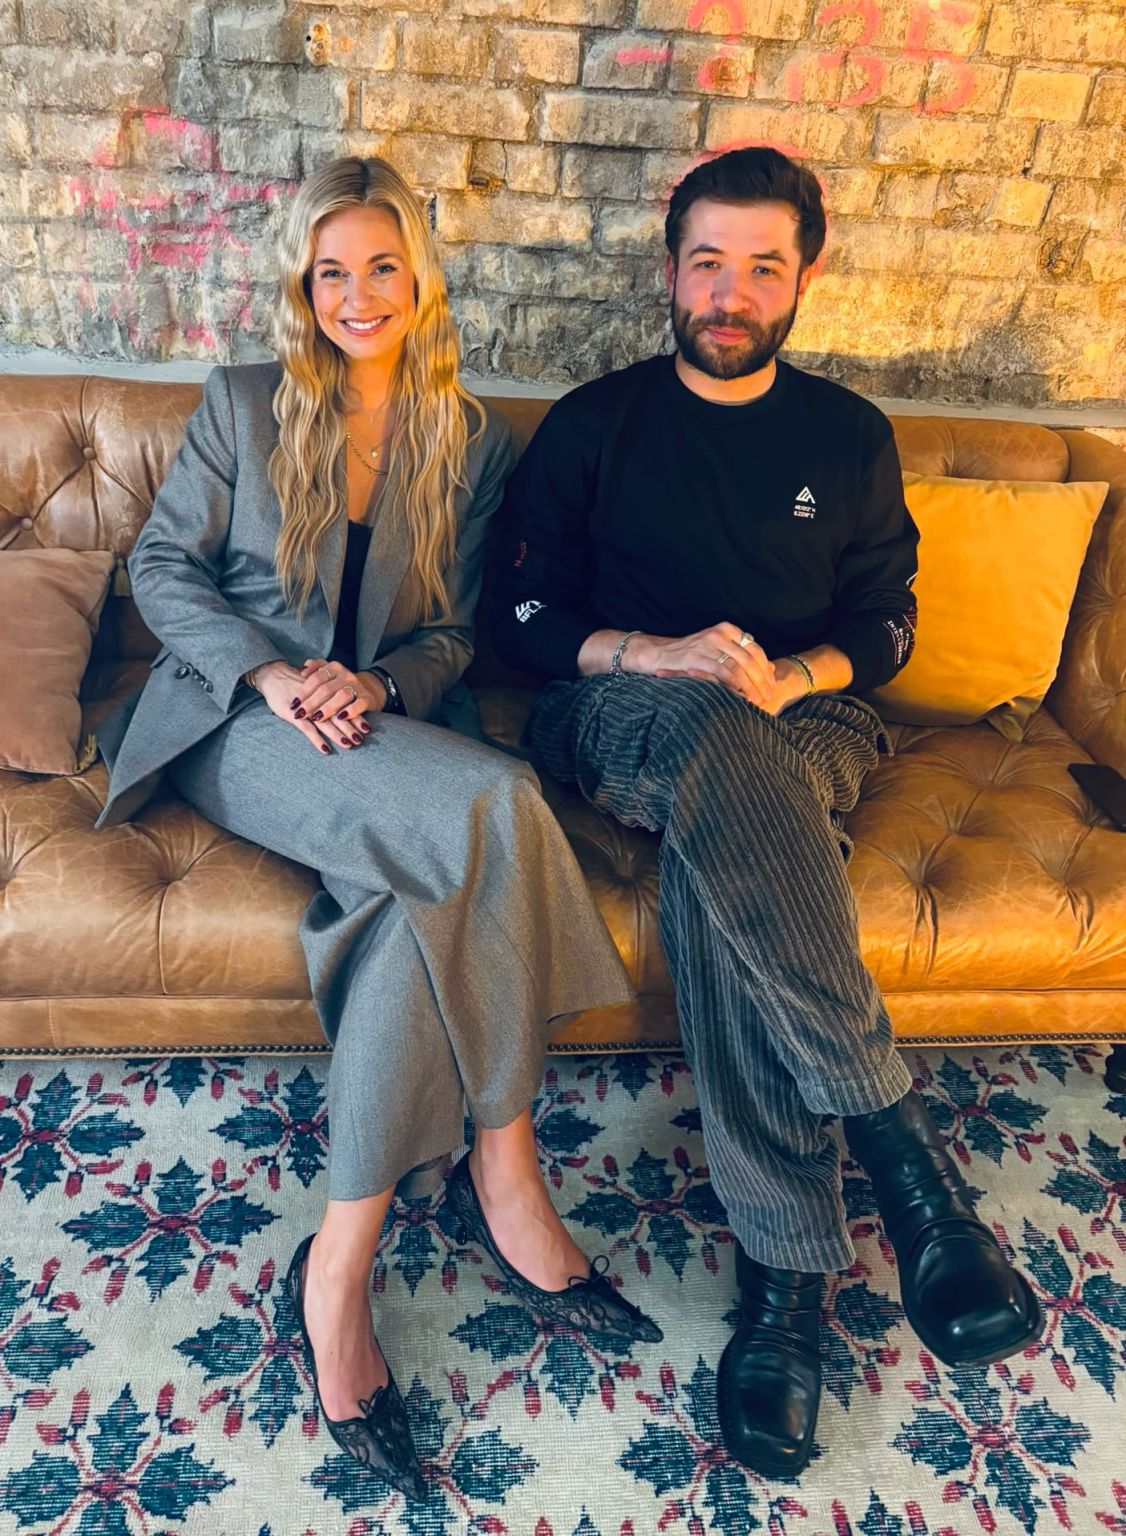
Black Forrest Labs x NEBIUS: The European Computing & AI Powerhouse!! 🌲🖤 [Anzeige] Meet Black Forest Labs × Nebius! At NVIDIA GTC Berlin, I met Stephen, Developer Advocate at Black Forest Labs, one of Germany’s most exciting AI startups! And there’s a pretty interesting collaboration behind this picture! Black Forest Labs develops cutting-edge generative AI models, including the FLUX family for visual and Physical AI. But building these models requires ENORMOUS computing power! That’s where Nebius comes in! ☑️ GERMAN AI MODELS: Black Forest Labs develops frontier visual intelligence models. ☑️ NVIDIA BLACKWELL GPUs: Black Forest Labs used Nebius’s NVIDIA B200 infrastructure for research behind Self-Flow, a training method foundational to FLUX 3. ☑️ EUROPEAN AI INFRASTRUCTURE: Nebius provides the computing infrastructure needed to develop and scale AI models! Besides all the AI applications we build, Europe needs more companies building the models & infrastructure behind it. And I LOVE seeing these companies doing this by working together!! 🖤 P.S. Stephen, it was great meeting you! Maybe I’ll take you all on a little trip to the German BLACK FOREST soon to explore Black Forest Labs behind the scenes! 🌲 #Nebius #BlackForestLabs #NVIDIA #AI
- WRITERSince 26 Oct 2026
AI labs chase benchmarks. Your board chases revenue. WRITER delivers agents built for marketing and revenue teams. The only AI metric that counts has a dollar sign.
- WRITERSince 26 Oct 2026
Now your AI does, too. WRITER captures every signal and every insight your team generates, so agents act on your latest intelligence — not last quarter's.
- Brainyware SrlSince 26 Oct 2026
Quante ore passa il tuo studio a cercare nei faldoni un contratto, una delibera o una circolare? Fai il conto in 30 secondi: scegli il tuo ruolo, inserisci persone e ore, e scarica gratis il calcolo dettagliato in PDF, con il confronto oggi / con l’Assistente Studio di Brainyware. Risposte con documento e pagina citati, anche dalle scansioni di vent’anni fa. I documenti dei clienti restano sul server dello studio.
- Brainyware SrlSince 26 Oct 2026
Quante serate passa il tuo studio a ribattere fatture, F24 e cedolini? Fai il conto in 30 secondi: scegli il tuo ruolo, inserisci persone e ore, e scarica gratis il calcolo dettagliato in PDF, con il confronto oggi / con l’Assistente Studio di Brainyware. Estrae i dati da tutta la cartella e verifica ogni valore alla lettera. I documenti dei clienti restano sul server dello studio.
- CometSince 26 Oct 2026
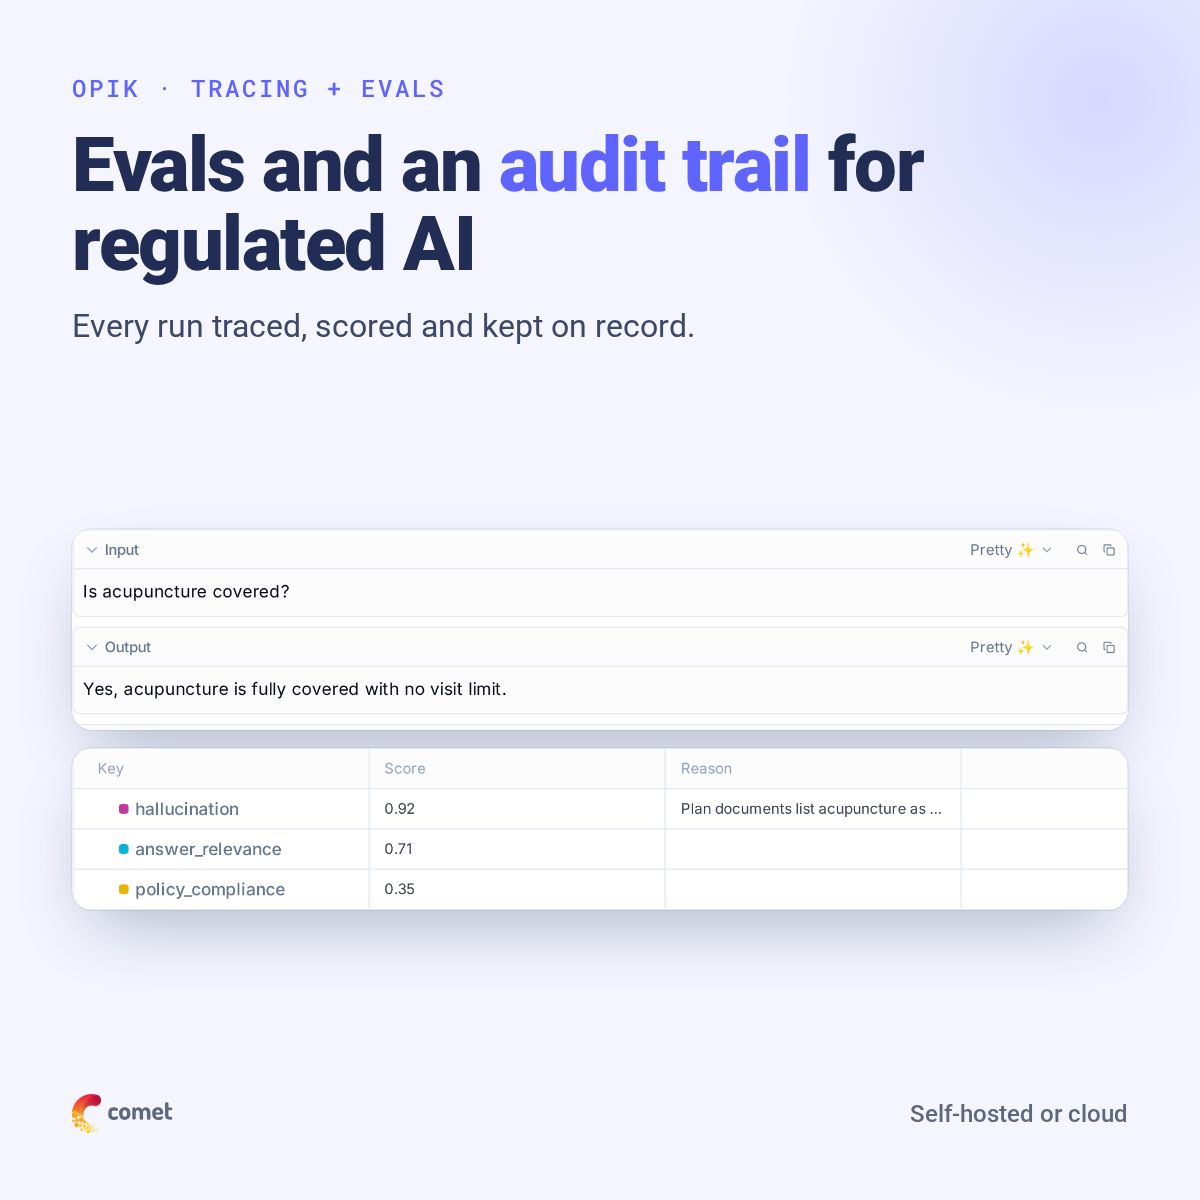
Preparing for the EU AI Act? Keep a trace of every agent run and score it against your own tests before release.
- CometSince 26 Oct 2026
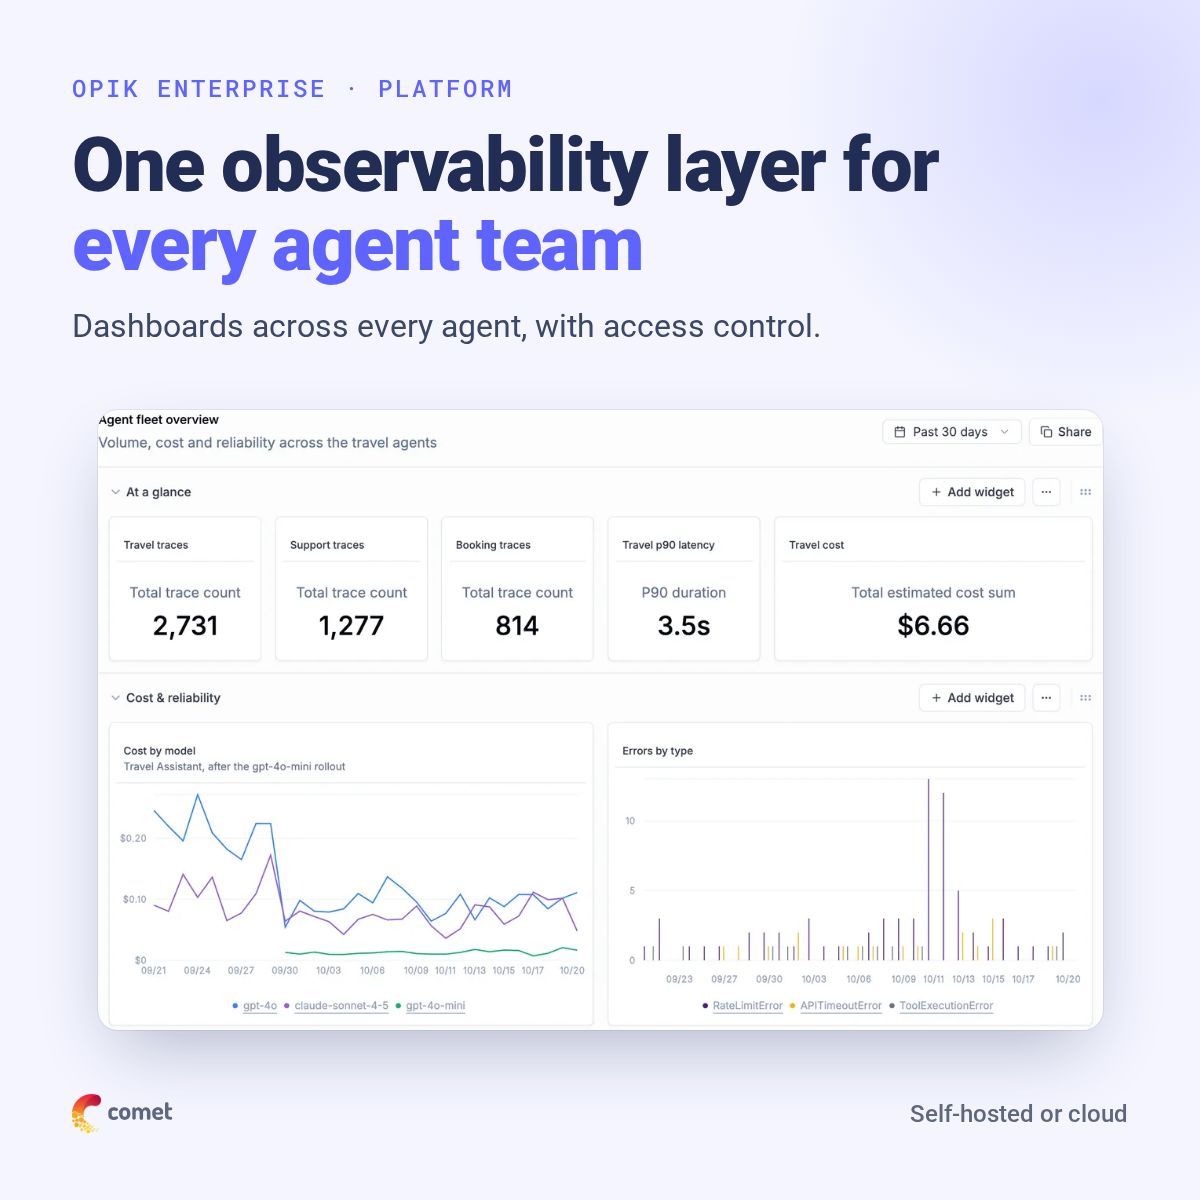
Give every AI team the same tracing, evals and guardrails, with SSO, RBAC and self-hosting for the platform team.
- AnamSince 26 Oct 2026
We just shipped a small update that carries a lot of weight in making conversations with Anam avatars feel more natural. When we think about conversations that just 𝘤𝘭𝘪𝘤𝘬, it’s not one big thing. It’s a collection of small behaviors that you barely notice until they’re missing. One of those happens when someone needs a moment to think. Ask someone something they don’t know off the top of their head, and they won’t just go silent, they'll ask you to give them a second or will follow with “let me check that” while they figure it out. Those tiny responses keep you in the conversation. Now Anam avatars can do the same while they’re waiting on a tool call, knowledge base, or API - responding naturally in the moment rather than leaving a gap of silence, staring into the abyss. And you can decide what those responses sound like for your avatar. Check out the demo video, and find a link to all our latest product updates in the comments.
- AnamSince 26 Oct 2026
I added two of our avatars to a video call today. They joined as teammates, listened to the conversation, responded in real time, and had access to everything about Anam through Claude Code. Why does this matter? Think about every business that runs on live conversation - sales calls, customer onboarding, language tutoring, coaching, employee training. Right now those all need a human on the other end. That is expensive, hard to scale, and restricted by time zones. Not to mention limited by what one person can know versus an agent. An AI avatar that can join a video call changes the math. - Coaching at 3am without burning out staff - A technical expert in every sales demo - 1-on-1 onboarding for every customer And the user on the other end isn't staring at a chatbot window. They're in a video call with a face that looks at them, reacts to what they say, and speaks back naturally. A face that represents your brand. Localised to each user. True personalisation at machine scale. That's a very different experience from a chatbot or a voice agent. Our customers report that adding a face to their agents has increased engagement by 44%. We're building this at Anam. The avatar engine handles speech recognition, reasoning, voice synthesis, and face generation in real time. Recall.ai handles getting the avatar into the call. It works with Google Workspace Meet, Zoom, and Teams today. Once Claude Code had access to the Anam MCP server, it took one line and 10 seconds to have both avatars join the call.
- deepset, makers of HaystackSince 26 Oct 2026
Turn decades of engineering documentation, maintenance records, and operational knowledge into reliable AI applications. Build and deploy with Haystack Enterprise Platform, keeping control over your data, models, and infrastructure.
- EliceRecorded 28 Oct 2026
Answer a few quick questions to check NVIDIA B300 availability and get a USD quote Our team replies within 1 business day NVIDIA B300 VMs match bare metal on the same 8-GPU node: 834.21 GB/s on VMs and 833.70 GB/s on bare metal (NCCL all_reduce busbw, 8 GiB messages, median of 3 runs) VM overhead is up to 0.5% at message sizes of 8 MiB and above, and up to 1.4% on GPU-to-host copies On-demand list price is $7.79* per GPU-hour Prepaid reserved terms of 3 to 5 years are priced lower *List price as of October 2026, billed per second, excluding taxes
- deepset, makers of HaystackSince 26 Oct 2026
Faster fault resolution. More productive maintenance teams. Across every site, not just one. Build and scale AI assistants with Haystack Enterprise Platform, with consistent evaluation, monitoring and governance to maintain performance as adoption scales.
- AssemblyAISince 26 Oct 2026
Picking the right LLM for a Voice AI pipeline is hard. Today we're launching Voice Standard Bench to rank 50+ of the best LLMs on real voice tasks, and making all of them available in AssemblyAI's LLM Gateway. Most Voice AI products run an LLM on messy, multi-speaker transcripts: - Voice Agents responding to human speech - Summarizing a meeting, sales call, or support call - Pulling names, dates and numbers out of a multi-speaker conversation - Fixing transcription errors - Cleaning up dictation Voice Standard Bench tests every model on the input these products actually send an LLM: lengthy conversational transcripts with multiple speakers, raw speech-to-text output with filler words, false starts and the occasional misheard word. Each model is scored on transcripts from a 30-second voicemail to a 60-minute meeting. Here's a glimpse of what we found: - The top-scoring model costs 55-65x more per hour of audio than a model within two quality points of it. - That gap narrows to about 5x on hour-long transcripts, where bigger models start to pull ahead on quality. - Open models we host on our own infrastructure are the fastest on short audio. On a 30-second transcript, gemma-4-31b answers in under a second at a quality score of 93. Learn more here: https://lnkd.in/gS_FsV3W Try 50+ models in our Playground: https://lnkd.in/g-kG2diJ
- AssemblyAISince 26 Oct 2026
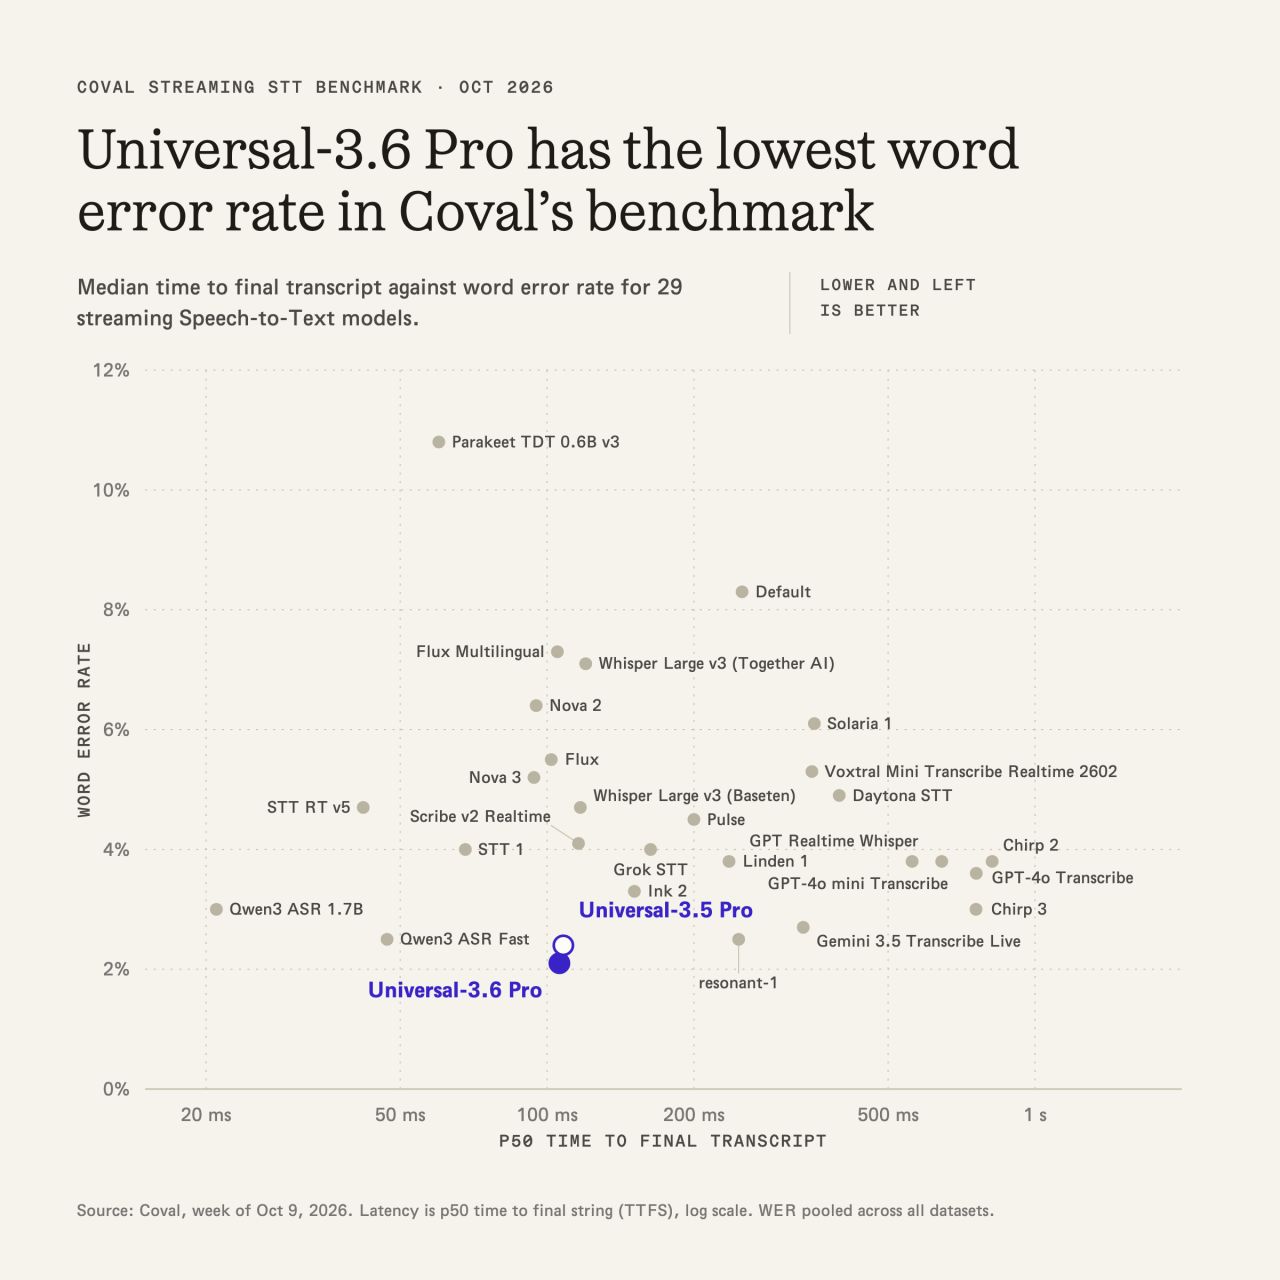
Coval 's weekly benchmark update is out, and Universal-3.6 Pro has the lowest word error rate of every streaming Speech-to-Text model they track. This week also showed a big drop in latency. Coval measured median time to final transcript falling by about a third on both of our streaming models: • Universal-3.6 Pro: ~153 ms → ~106 ms • Universal-3.5 Pro: ~156 ms → ~108 ms For a voice agent, those two numbers decide what the caller hears. A lower error rate means the agent gets names, numbers and order IDs right the first time. A faster final transcript means it can start responding sooner. Thanks to the Coval team for running these benchmarks in public every week.
- DATA POEMRecorded 28 Oct 2026
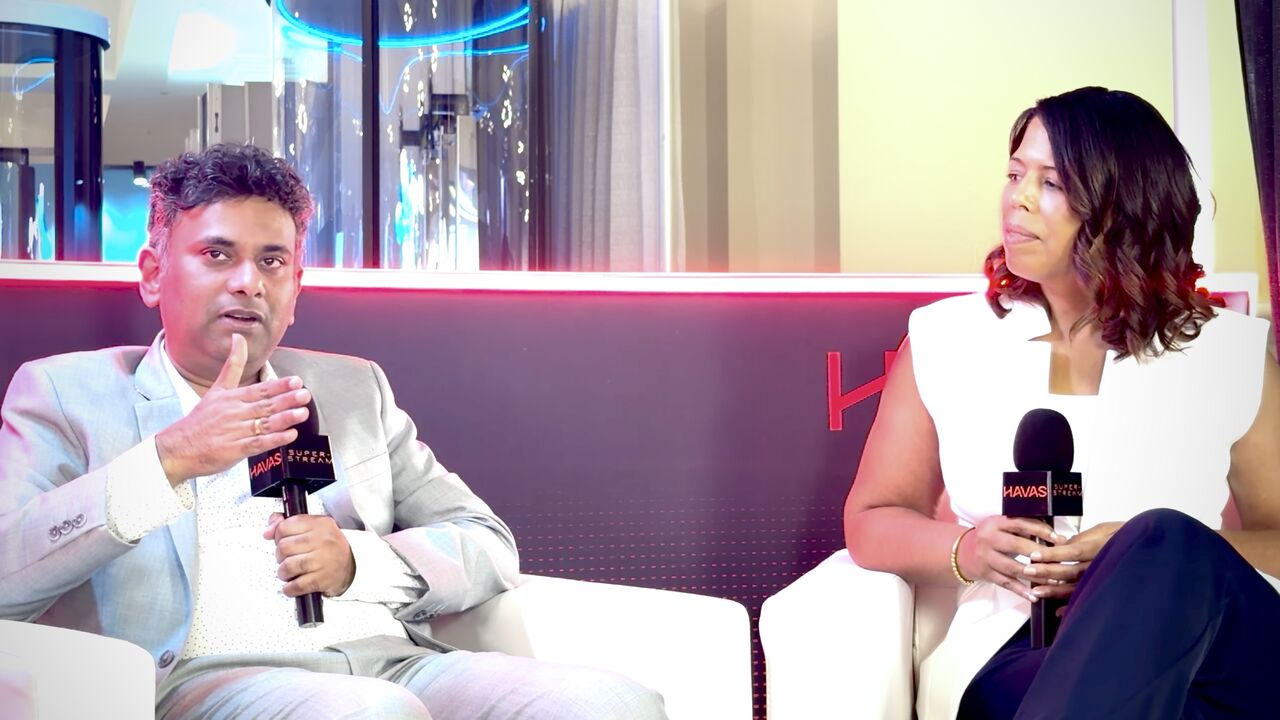
For 20 years I watched growth budgets go to whoever had the most conviction in the room. Last week at Masters of Marketing in Orlando, run by the Association of National Advertisers, Havas Media Network and DATA POEM hosted a private breakfast on a question every CFO and CEO keeps asking: what actually drives growth? I loved having this open conversation with Sharona Sankar-King, Chief Data & Product Officer at Havas Media Network North America, and a small group of senior marketers before the morning keynotes. While the entire industry is focused on LLMs, we spent the morning talking about something different: Large Causal Models, and why they’re what decision-making actually needs. Here’s why. Marketing has never had more data, yet most measurement still tells us what happened alongside growth, not what made it happen. That isn’t a data problem. It’s a math problem and an architecture problem. Most companies explain growth with dozens of separate models, one per team or channel. Their answers never add up. The fix is one Enterprise Growth Model, built on Large Causal Models trained on time-series business data, not text. It traces causation instead of correlation, learns how every growth driver moves the others, and shows what a different decision would do while there’s still time to act. The questions around that table were the right ones: where causal AI earns trust with finance, what’s still hard, and how enterprise marketers can put it to work in 2027. Thank you, Sharona and the Havas team, for co-hosting, and to everyone who joined us. Together with Havas, we’re bringing that model to the brands who need it most. If your growth plan still runs on models that disagree, watch the full conversation here: https://lnkd.in/gJqbxs_C
- DATA POEMRecorded 28 Oct 2026
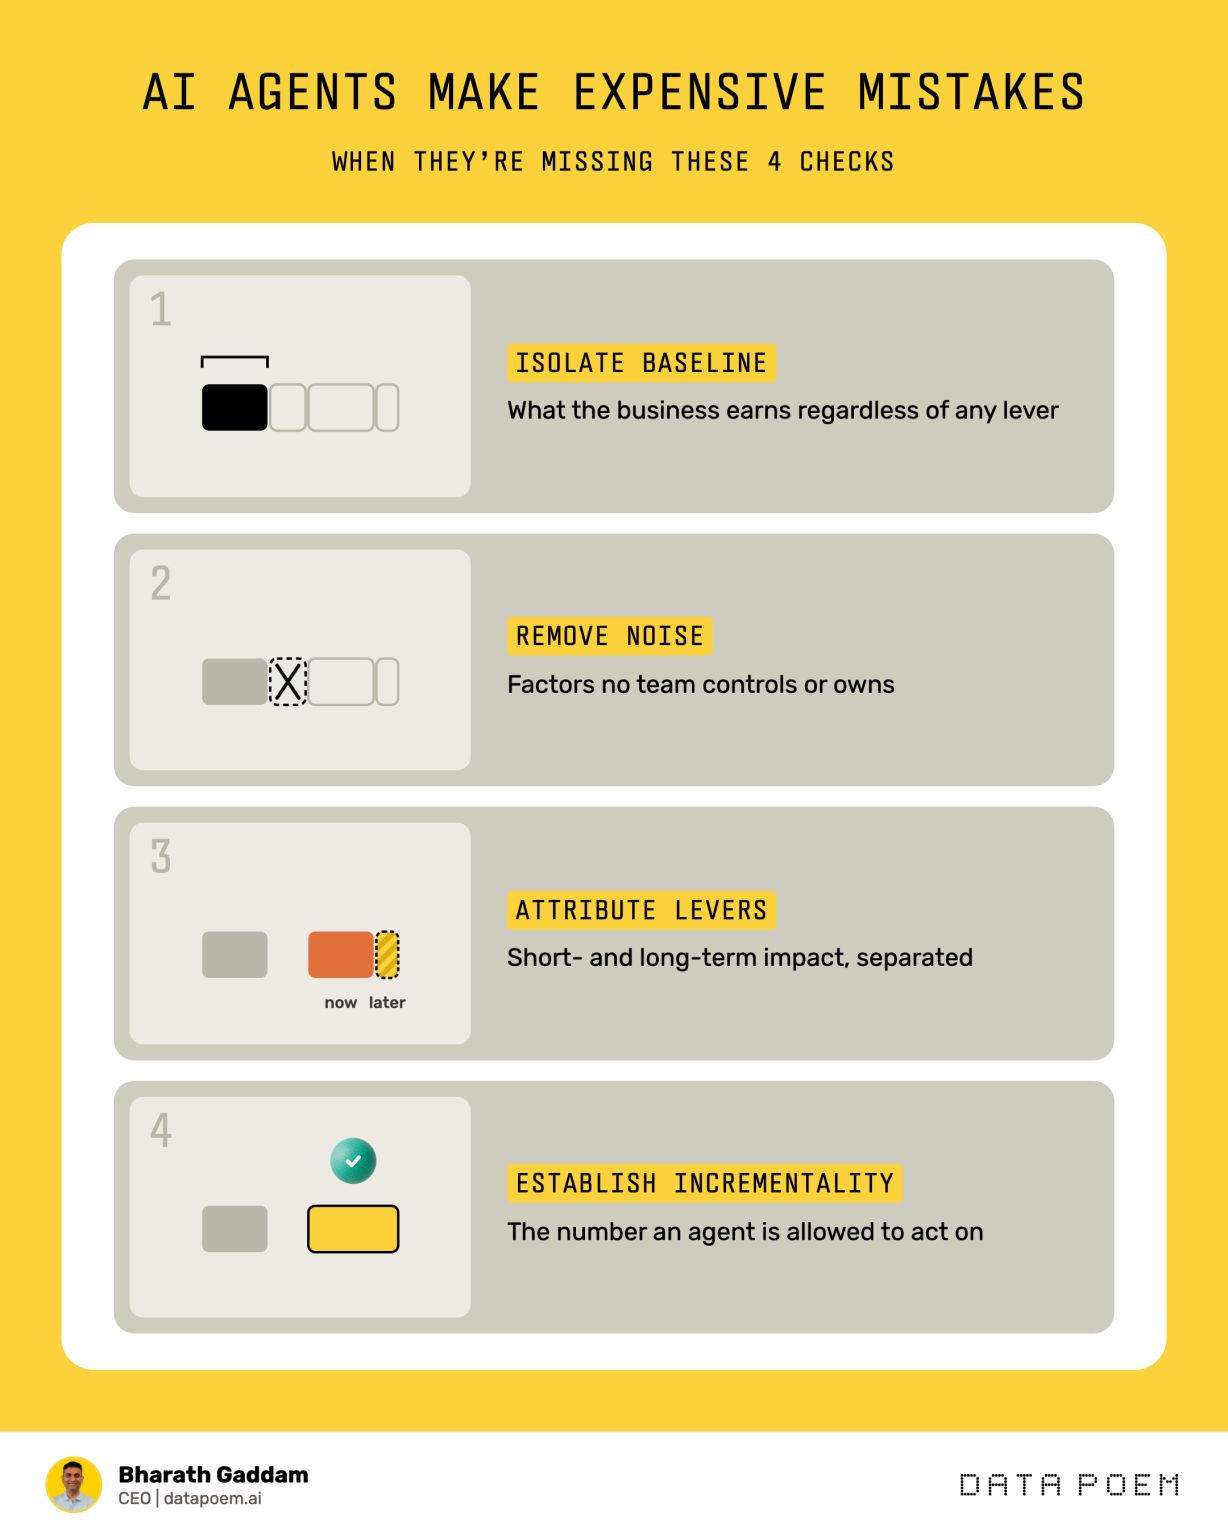
Your AI agent will give you a confident reason for every dollar it moves. The reason is fiction. Ask it why it shifted spend out of brand media and into promotions, and it answers with total conviction. It just can't tell a good-sounding answer from a true one. That's the gap Tapati Bandopadhyay, PhD of Third Eye Advisory names in her new paper, "Beyond the Trust Wall: How Causal Reasoning Embeds AI TRiSM Into Autonomous Enterprise Action." She calls it fast to act, slow to explain. An agent reallocates a marketing budget at 2 a.m., and no one sits with it while it decides. The systems that take action are maturing faster than the systems that can explain the action. Her case makes the cost visible. Promotions looked like the biggest lever at 14.5% of new customers, with brand media at 10.6%. An agent running on standard prediction would have moved the budget into promotions. FOUNT found the other 7.1% of brand media was quietly generating months later, money last-click measurement simply could not see. She turns that into a test every agent should pass: explain the outcome "the way a controller explains a variance." Isolate the baseline. Remove the noise. Attribute each lever, now and later. What's left is the only number an agent is allowed to act on. A causal chain gives a guardian agent a checkable claim to test, so you can ask whether an agent "has earned the right to act on it" before the money moves. Tapati, thank you. The idea that every decision should come with its cause attached is the one DATA POEM was built on, and you've given it a sharp frame. Read the full paper here: https://lnkd.in/gA_ZqF4R #DecisionAI #CausalAI #EnterpriseAI #AIROI
- ExaRecorded 28 Oct 2026
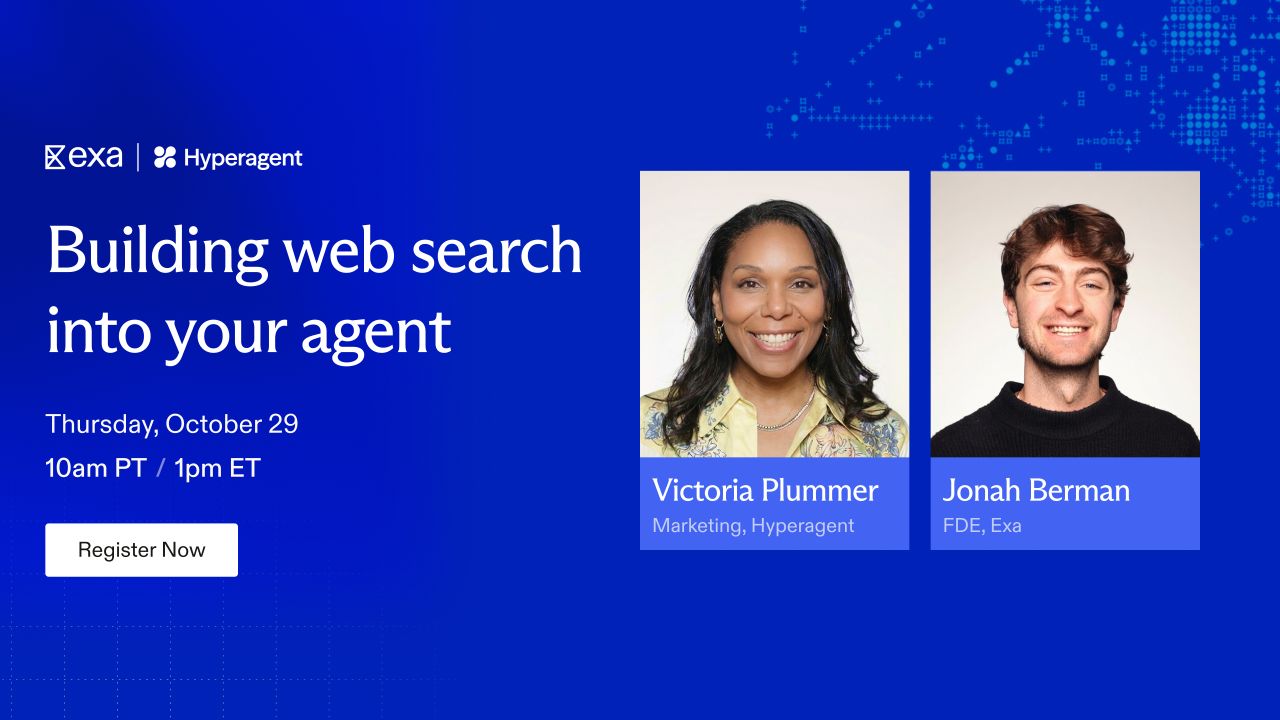
What does building web search into agents look like in production? This Thursday at 10am PST, we chat with Victoria Plummer from the Hyperagent team about their learnings from shipping web-search-enabled agents into production. You’ll learn: - Which jobs depend on search: what Hyperagent's production usage shows - When your agent should search fast and cheap vs. deep research - New product capabilities that web search can bring to your agent Link to register in the comments!
- InteractiveAISince 22 Oct 2026
A regulated iGaming operator now resolves +75% of its support tickets autonomously. It's Betsson, in one of its key regulated markets. Before a ticket even exists, 30%+ are solved proactively: the AI fixes failed identity checks before the player has to ask. Of the remaining incoming tickets, +75% are resolved end to end. The case study walks through the setup step by step: governance, ownership, and the limits built in by design. Free download for licensed iGaming operators.
- InteractiveAISince 22 Oct 2026
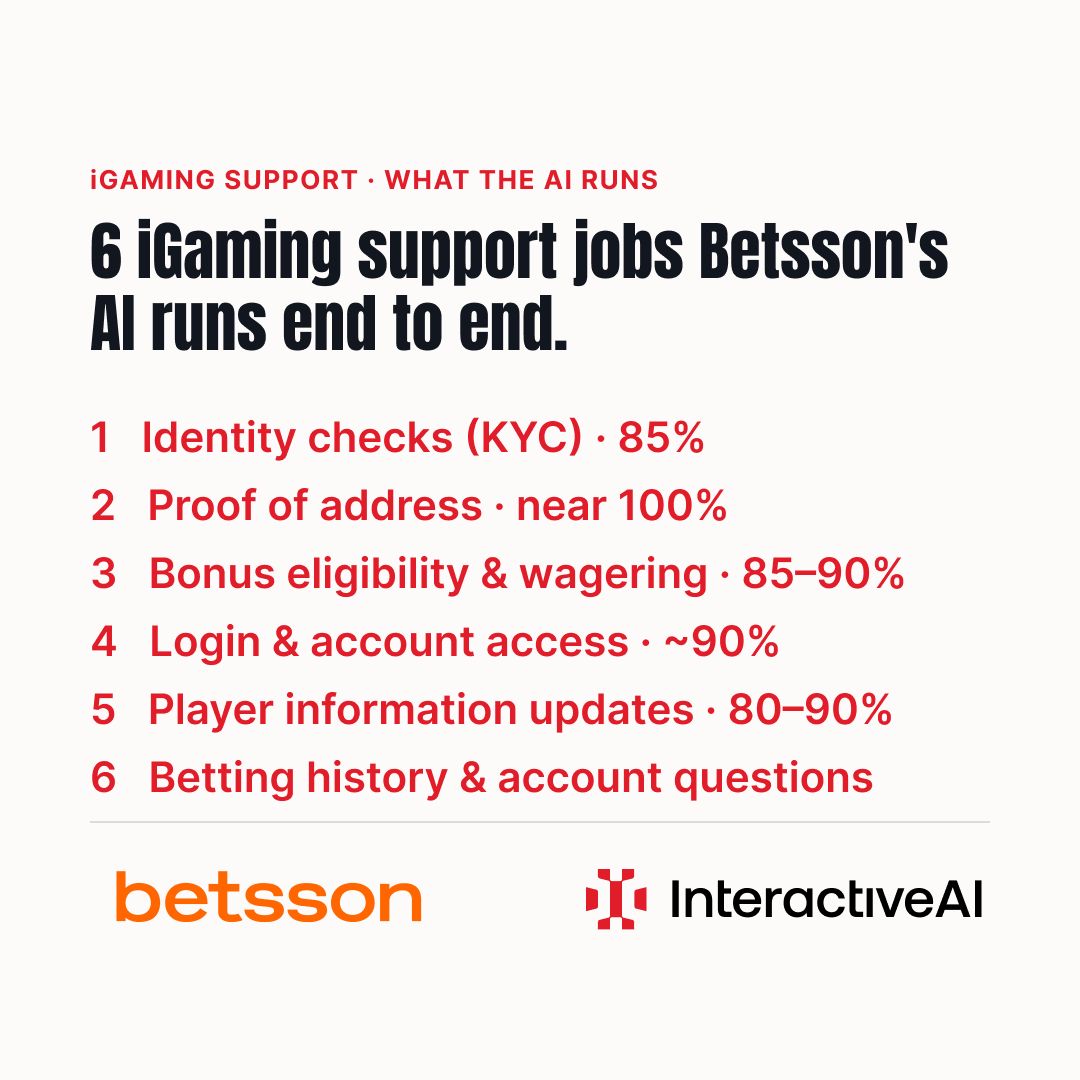
6 iGaming support jobs Betsson's AI now runs end to end, from KYC to bonuses. Identity checks (KYC). Proof of address. Bonus eligibility and wagering. Login and account access. Player information updates. Betting history and account questions. Each one runs on rules the support team writes and owns. Bank-account changes, and anything the rules can't settle, go to a person. The case study shows the resolution rate for each job. Free download.
- HumanSignalSince 23 Oct 2026
The model people liked most for a science publication finished last when we asked it for an Italian soda pitch deck. Same model, same evaluators, same rubric. Only the brief changed, and a single benchmark score would never show it. See all 100 designs and how every model ranked.
- HumanSignalSince 23 Oct 2026
We gave ten AI models the same website brief and asked people to pick the better design. Then we changed the brief. The model that won the boutique hotel brief finished dead last on a science publication. One leaderboard score would have hidden that, which is why we run evals with people. All 100 designs and the full rankings are on the page.
- LumaSince 25 Oct 2026
Art direction usually starts with references. The harder part is seeing what that style actually does to the product. Style Match lets you start with the product image, add 1–4 art references, and restyle it while keeping the product, framing and composition in place. Useful for testing a direction before final illustration or production, or taking the result straight into social. Try Art Style Match in Luma.
- Humyn LabsRecorded 27 Oct 2026
We asked Imran Nawaz what he’s working on. This is what his tabs said. Keeping Tabs EP 1. Today’s tabs: - What goes behind our validation pipeline? - Why egocentric footage gets rejected? - Why quality comes first in model-ready data and how do we protect it?
Other LinkedIn formats
Watch the companies you care about.
Filter every ad by industry, country, format and network, and get alerts when a company you watch starts running new ads.