On air · 1 of 3 networks
AssemblyAI
- assemblyai.com
- AI
- US
- 116 employees
AssemblyAI’s ads on LinkedIn, Meta and Google, recorded by adsrunning. Browse the latest here for free. Sign up free to see all 305. Watch AssemblyAI with Starter to get each new one in your feed.
Watchlist with Starter · $49/mo
| Network | Status | Live ads | Nov 2025LinkedIn activity · 52 weeksOct 2026 | Checked | Next step |
|---|---|---|---|---|---|
| Running | 52 | Checked 30 Oct 2026 | See all 305 ads → | ||
| Meta | Not checked | — | |||
| Recently | 100+ | Ads on the Google Ads Transparency Center | Checked 6 Oct 2026 | Collect them with the API → |
AssemblyAI has 52 live LinkedIn ads. We recorded 100+ Google ads on 6 Oct 2026.
Latest ads
- LINKEDIN · VIDEOSince 28 Oct 2026
Introducing AssemblyAI-TTS-1, our first text-to-speech model. Natural speech for voice agents, streaming in 90 ms, at $15 per million characters. On accuracy, naturalness, and cost together, it’s the best TTS model you can run at scale. It’s served on the infrastructure that already moves 3M+ hours of audio a day for 1M+ speech-to-text developers, so concurrency is unlimited on pay as you go. Ten calls or ten thousand, no commitments required. Live today: - Leading accuracy on independent benchmarks - 90 ms time to first audio - Trained on millions of hours of audio - Instant voice cloning - 4,000+ voices, with new ones added daily Every voice, language, and region included at $15 per 1M characters Available today. Watch a kid use it to order a pizza. Full announcement: https://lnkd.in/eE_H7xj9
- LINKEDIN · VIDEOSince 28 Oct 2026
Productivity at AssemblyAI has taken a hit recently... We've been having WAY too much fun testing our new Text-to-Speech model 👀 Experimenting with different voices, cloning each other, and making the model say increasingly ridiculous things. Good news: today we're launching AssemblyAI-TTS-1, so now everyone else can get distracted too 🚀 And while we've been having fun, the team has built something pretty incredible: 🎙️ Natural, expressive, human-like speech 🎯 Leading accuracy on independent benchmarks ⚡ <100ms time to first audio 🗣️ Instant voice cloning and 4,000+ voices ♾️ Unlimited concurrency, no minimum commitments 💰 Just $15 per million characters We've spent years helping developers build agents that can hear and understand their users. Now we're helping those agents speak back. Go have some fun with it. Promise it'll be worth it 👇 https://lnkd.in/ghNAX93i
- LINKEDIN · IMAGESince 28 Oct 2026
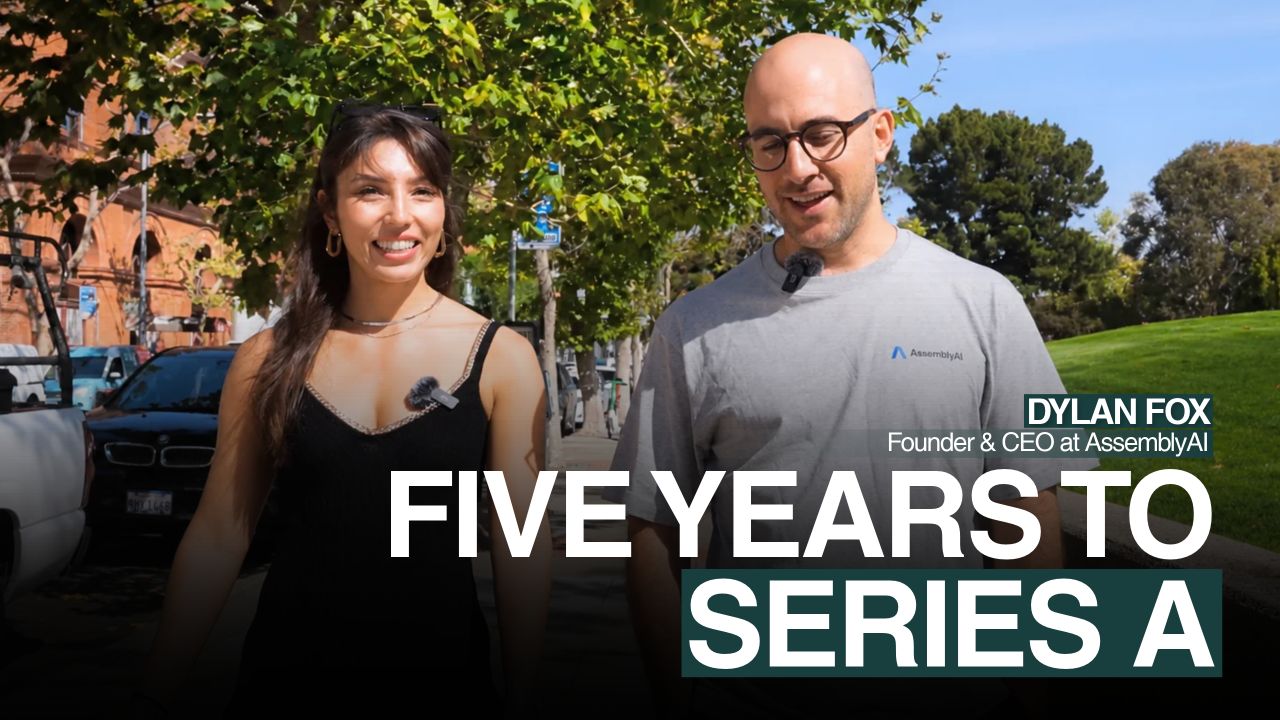
Every founder is told to find product-market fit in 18 months. Dylan Fox waited five years for the voice AI market to exist. Now his company runs the voice AI behind Granola - 100M API calls a day! When we met at their office, I wanted to know how you tell conviction apart from stubbornness when the market says no for half a decade. Between 2017 and AssemblyAI's Series A in 2022, he had two choices: take early voice models and sell them to court reporting agencies, or keep refining the core speech models until developers finally needed them. He chose to wait. He kept the team capped at four people, kept personal expenses near zero, and treated those five years as an apprenticeship in deep learning. When I was building Paloma, I lived on the opposite side of that equation. I knew that AI matchmaking was bound to be a thing, but chased immediate market signals, and eventually ran out of steam. Watching Dylan build proved that surviving the quiet years requires obsessive faith in the future itself. We also get into: -> Why the last 10% of an AI product is the whole product -> “Everyone’s still just figuring it out” -> 180% net dollar retention with zero contracts -> Married to a founder whose company took off while his didn’t -> Why he deleted X in 2023 (I think he’s back tho) -> “I’m just a builder” Full episode link in the comments.
- LINKEDIN · VIDEOSince 28 Oct 2026
Today we're launching AssemblyAI-TTS-1, our first text-to-speech model: frontier naturalness, super fast, instant cloning, and just $15 per 1M characters. On the combination of accuracy, naturalness, and cost... no other TTS model is better. It's perfect for conversational voice agents running at scale. We trained AssemblyAI-TTS-1 from scratch on our own proprietary data, and we serve it on our proprietary voice inference stack. The same inference stack that already handles 3M+ hours of voice/day for the 1M+ developers building with our transcription models. This means AssemblyAI-TTS-1 is frontier quality + super fast (80ms TTFB), and supports unlimited scale with no rate limits or capacity to reserve up front - just like our leading transcription models. AssemblyAI-TTS-1 is live TODAY with: - Frontier naturalness - #1 in accuracy on independent benchmarks - $15 per 1M chars - 90ms latency (TTFA) - Unlimited concurrency/rate-limits - Instant voice cloning - A library of 4,000+ voices to pick from Available today in our API. Watch Johnny order a pizza with our new TTS model in the video below 👀 And stay tuned... we have a ton of improvements and updates on the way.
- LINKEDIN · IMAGESince 26 Oct 2026
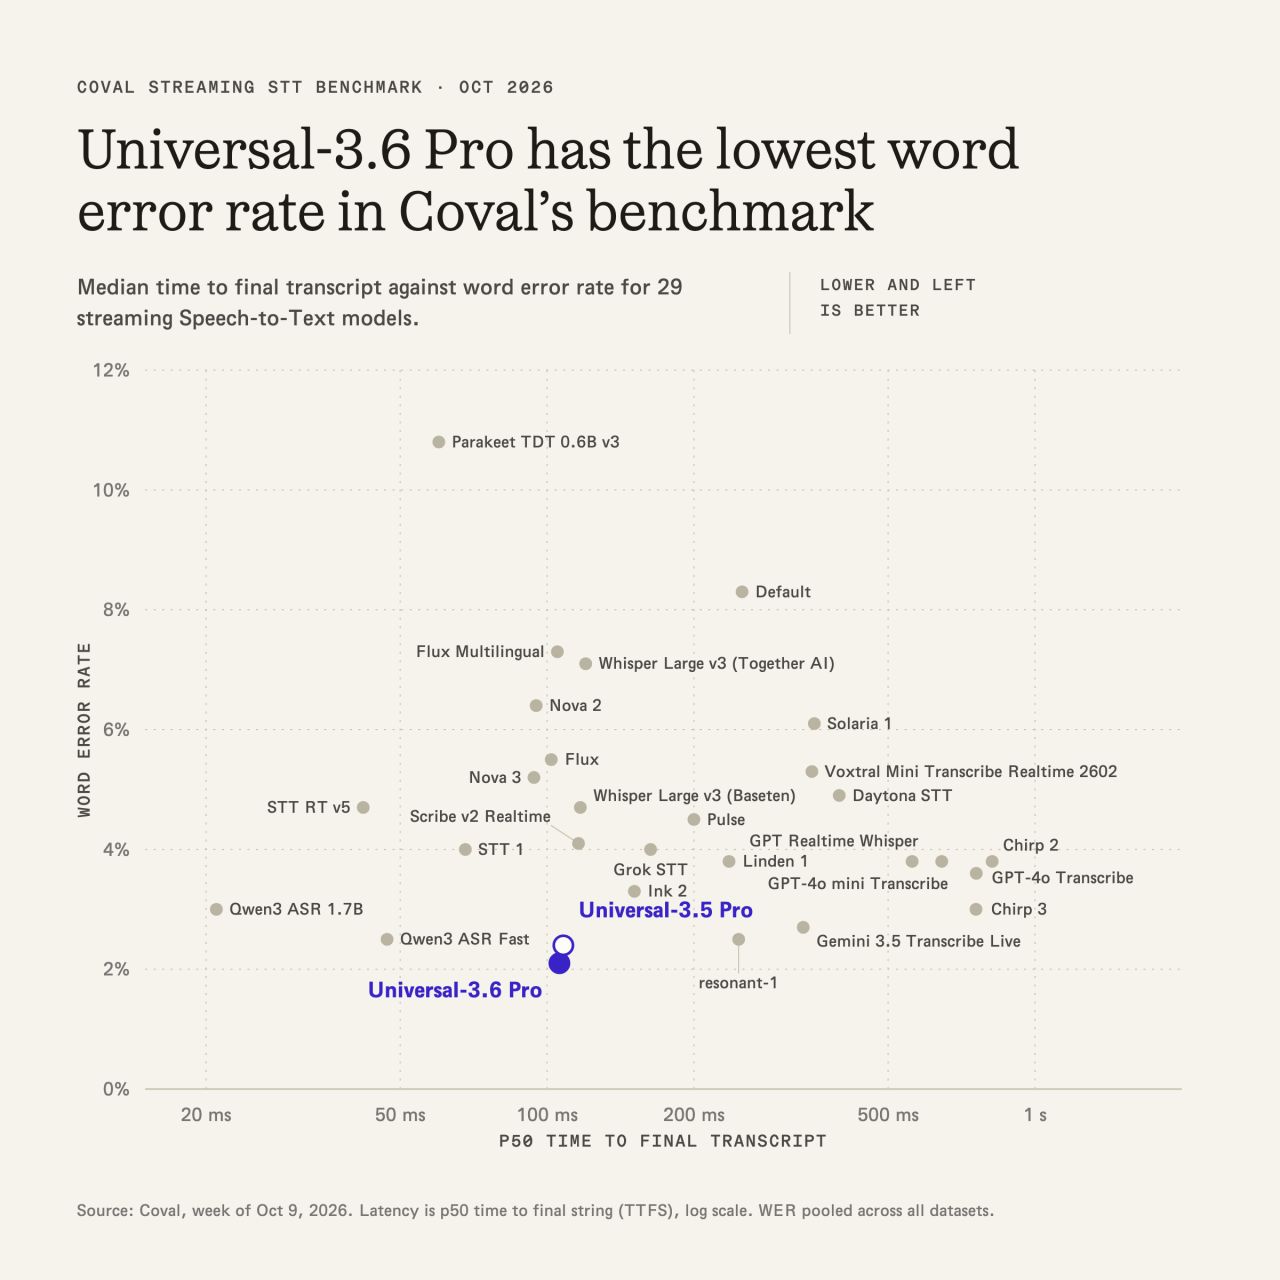
Coval 's weekly benchmark update is out, and Universal-3.6 Pro has the lowest word error rate of every streaming Speech-to-Text model they track. This week also showed a big drop in latency. Coval measured median time to final transcript falling by about a third on both of our streaming models: • Universal-3.6 Pro: ~153 ms → ~106 ms • Universal-3.5 Pro: ~156 ms → ~108 ms For a voice agent, those two numbers decide what the caller hears. A lower error rate means the agent gets names, numbers and order IDs right the first time. A faster final transcript means it can start responding sooner. Thanks to the Coval team for running these benchmarks in public every week.
- LINKEDIN · VIDEOSince 26 Oct 2026
Picking the right LLM for a Voice AI pipeline is hard. Today we're launching Voice Standard Bench to rank 50+ of the best LLMs on real voice tasks, and making all of them available in AssemblyAI's LLM Gateway. Most Voice AI products run an LLM on messy, multi-speaker transcripts: - Voice Agents responding to human speech - Summarizing a meeting, sales call, or support call - Pulling names, dates and numbers out of a multi-speaker conversation - Fixing transcription errors - Cleaning up dictation Voice Standard Bench tests every model on the input these products actually send an LLM: lengthy conversational transcripts with multiple speakers, raw speech-to-text output with filler words, false starts and the occasional misheard word. Each model is scored on transcripts from a 30-second voicemail to a 60-minute meeting. Here's a glimpse of what we found: - The top-scoring model costs 55-65x more per hour of audio than a model within two quality points of it. - That gap narrows to about 5x on hour-long transcripts, where bigger models start to pull ahead on quality. - Open models we host on our own infrastructure are the fastest on short audio. On a 30-second transcript, gemma-4-31b answers in under a second at a quality score of 93. Learn more here: https://lnkd.in/gS_FsV3W Try 50+ models in our Playground: https://lnkd.in/g-kG2diJ
6 of 305 adsSign up to see every AssemblyAI ad, filter by format and date, and get alerts on new ones.
See all 305 adsWatch the companies you care about.
Filter every ad by industry, country, format and network, and get alerts when a company you watch starts running new ads.