B2B ad examples
478 B2B ads are live on LinkedIn right now, from 210 companies. Browse real ones, filtered by industry.
- Empromptu.aiRecorded 17 Sept 2026
In month 12, a market condition occurs that wasn't in the training data. The AI doesn't error. By the time a human notices, it's been 45 seconds. 180,000 transactions. The scariest AI failure isn't the one that crashes. It's the one that keeps running.
- ELYZA, Inc.Recorded 17 Sept 2026
【ELYZA Works with KDDI】フォーム形式で統一されるから使いやすい!現場主導で自社専用のAIアプリを作れるから日々の業務を効率化できる。企業のAI導入課題も解決。
- EndeavorRecorded 17 Sept 2026
"Four months ago, our CSR team was manually typing customer orders into the system. Here's the twist. What once took 45 minutes now takes just 2 minutes with AI."
- EndeavorRecorded 17 Sept 2026
"I don't see AI or technology replacing people, I see people being able to eat dinner with their families and get people home earlier"
- Empromptu.aiRecorded 17 Sept 2026
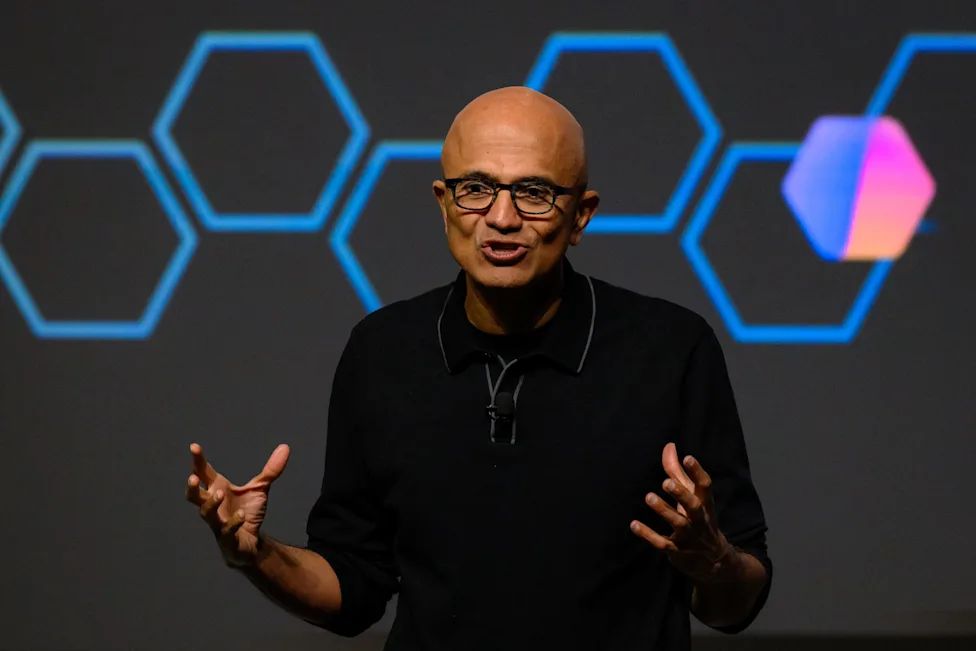
Satya Nadella just made the case for everything we've built at Empromptu: "There should be as many models in the world as firms in the world. Because after all, what is a firm? A firm is a learning system." The whole article reads like a blueprint for what we ship. Line by line, we check all the boxes: "I don't want to be locked into any one model" ✅ "I want to use my own context, my own data" ✅ "...cost-efficient model" ✅ "...fine-tuned model" ✅ And the line that puts it into a sharper perspective: "If you outsource your learning, then why exist?" Exactly. So we turn every correction, edge case, and real-world use into training data that builds custom AI your company owns, not rents. Our Self-Managing Context tech holds up to 98% accuracy in production. In the wild, that's 50,000+ AI requests a day across 1,600+ store locations, and 20,000+ creators managed with zero AI engineers on the client side. You own your context. You own your learnings. Take it from Satya. This is the future. Source in the comments. Want to see it work on your data? 👇
- Edge ImpulseSince 7 Aug 2026
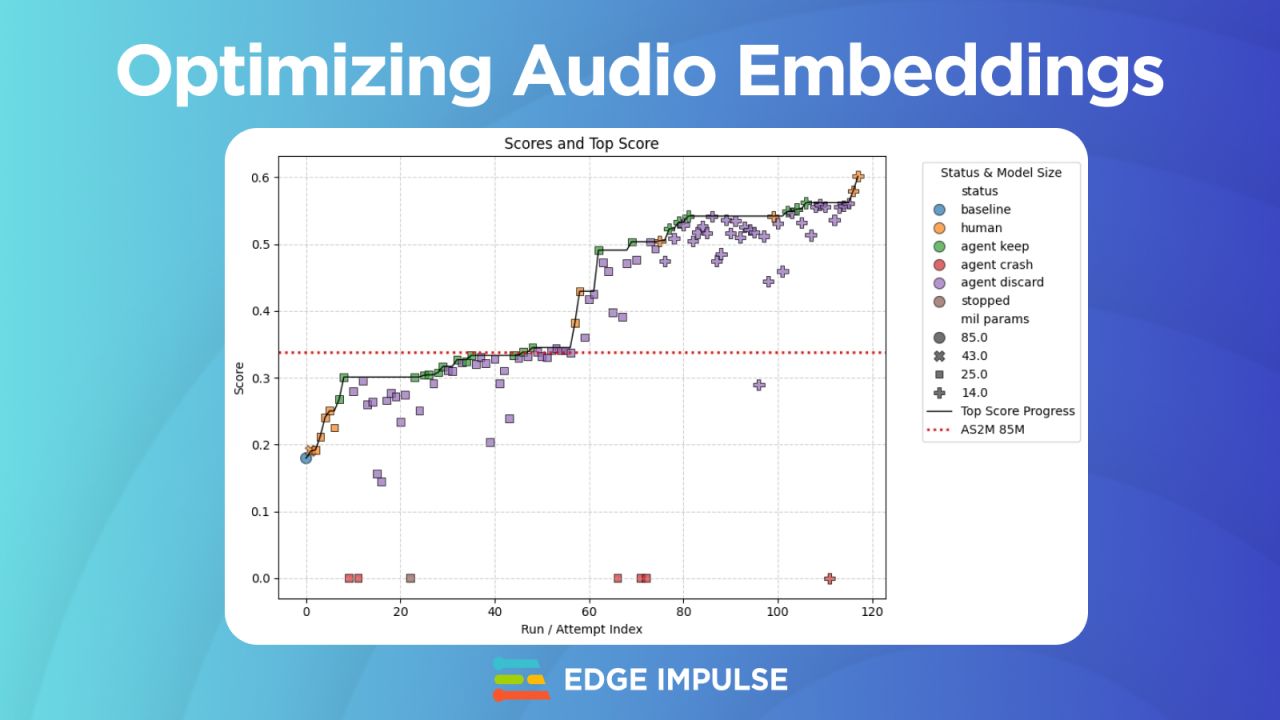
One of our Applied Research Engineers, Yan L., built a smaller, open-data-trained audio embedding model for real-world sound classification and anomaly detection use cases. Here's how it came together. https://lnkd.in/eKAQNFP5 #edgeAI #AI
- Edge ImpulseSince 18 Aug 2026
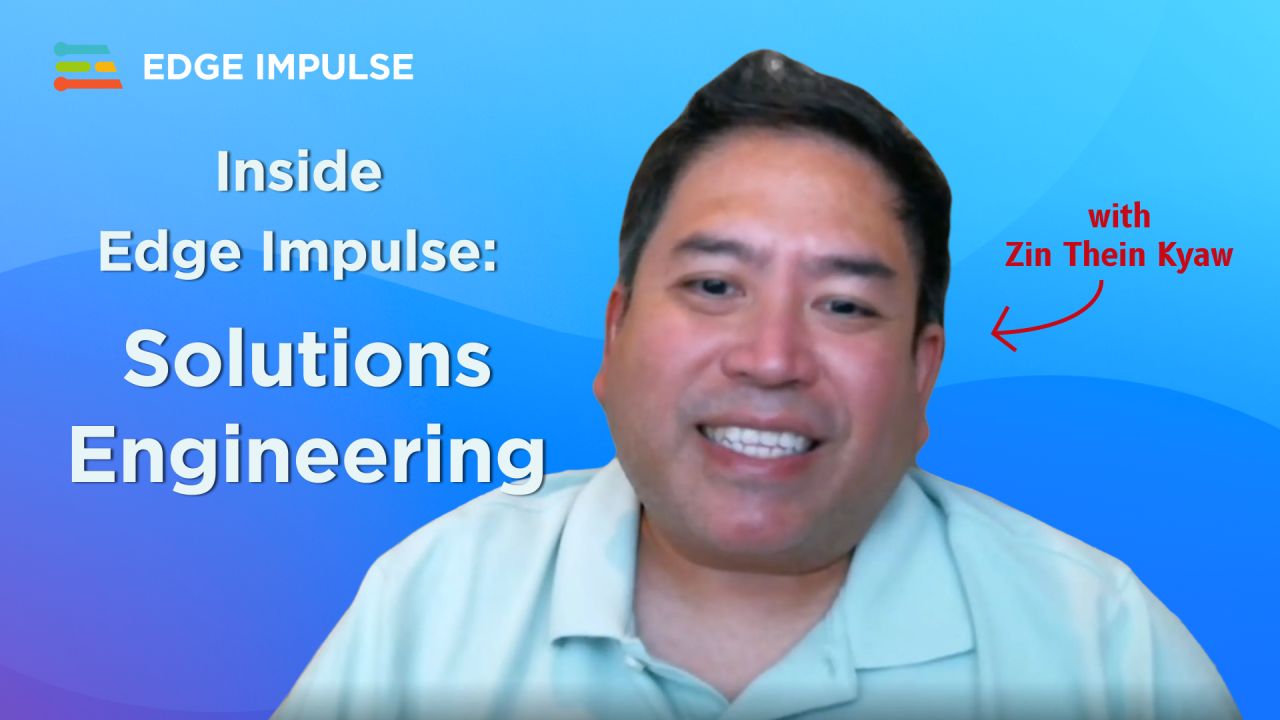
We recently sat down with Zin Thein Kyaw, head of solutions engineering here at Edge Impulse, to talk about the evolving landscape of #edgeAI and how this technology is transforming industries like laundry automation and pet care. In the discussion, Zin covers: - The role of AI in augmenting the workforce, rather than replacing jobs -Real-world customer production use cases with HP Poly and Purina -Common misconceptions about data readiness and model accuracy And lots more. Check out the full discussion: https://lnkd.in/gynVEDdT And reach out to Zin or Edge Impulse here on Linkedin or on any of our channels to talk about your use case.
- Edgescale AIRecorded 17 Sept 2026
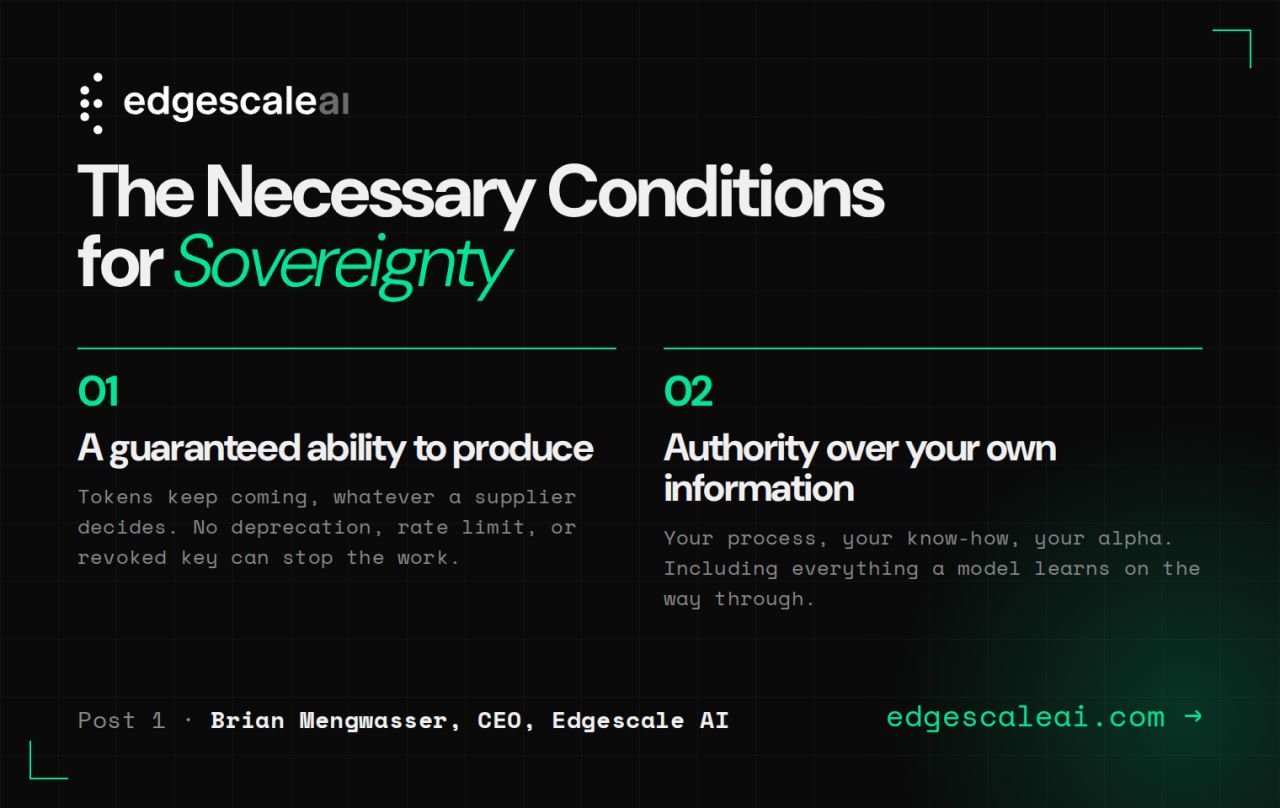
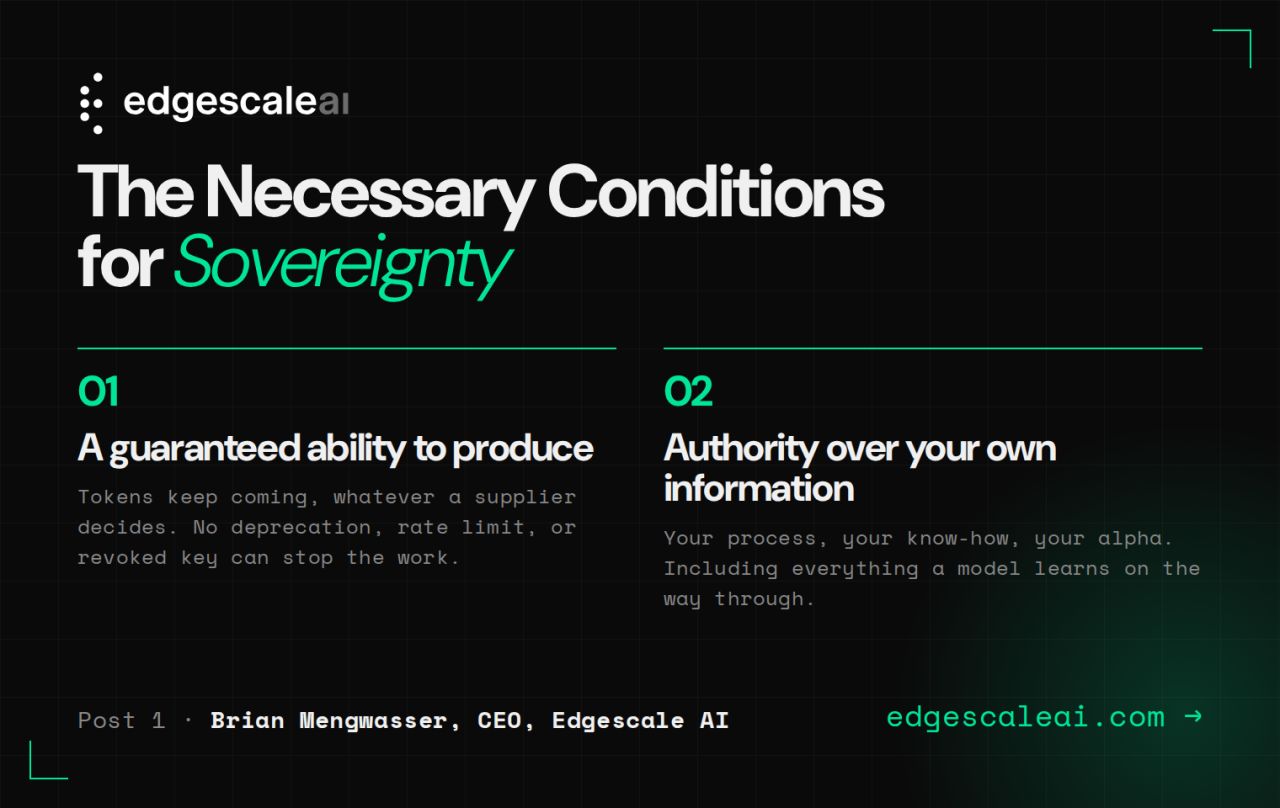
If your business increasingly runs on AI, AI sovereignty isn't a philosophical question - it's a business continuity one. Our new post lays out the two necessary conditions for Sovereign AI, and why enterprises need to act now, not later.
- Edgescale AIRecorded 17 Sept 2026
AI data-center buildout is projected to hit $1.4 trillion a year by 2030 - seven times the peak of the dot-com telecom boom. Who controls that infrastructure determines who controls your business. Our new piece on Sovereign AI breaks down what's actually at stake.
- ELYZA, Inc.Recorded 17 Sept 2026
Get the latest jobs and industry news
- Eigen AI (Now part of Nebius)Since 12 Nov 2025
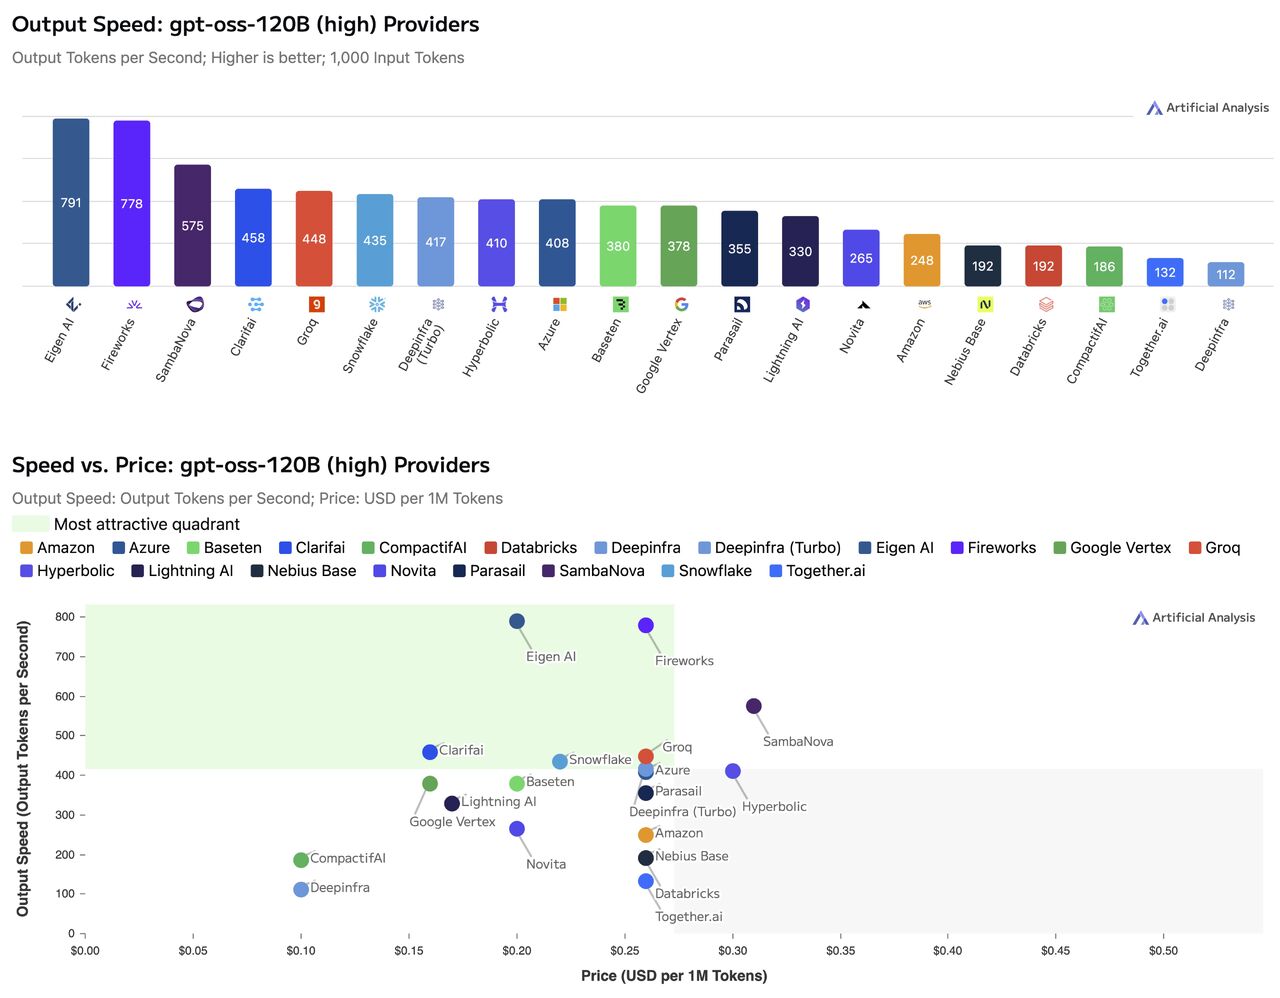
Eigen AI ranks #1 on Artificial Analysis for multiple popular models. 🚀 Today we’re excited to share that Eigen AI’s serving APIs are now listed on Artificial Analysis—with standout results in output speed, TTFT, and speed-for-price. 𝐇𝐢𝐠𝐡𝐥𝐢𝐠𝐡𝐭𝐬 • #1 output speed (tokens/s) among all GPU-based providers for GPT-OSS-120B, DeepSeek-V3.1-Terminus, and Qwen3-VL-235B-A22B 🚀 • Compelling speed-for-price: high throughput without premium pricing • Low latency at high speed (and low price): efficient placement on latency-vs-speed plots • Low TTFT: snappy first-token response for chat, agents, and copilots How we do it: 𝐄𝐢𝐠𝐞𝐧𝐈𝐧𝐟𝐞𝐫𝐞𝐧𝐜𝐞 A full-stack acceleration toolkit: FP4/NV-FP4 quantization (plus PTQ/QAT), sparsity, speculative decoding, KV-cache optimizations, and kernel/graph work (fused ops, custom CUDA/Triton). Why it stays up: 𝐄𝐢𝐠𝐞𝐧𝐃𝐞𝐩𝐥𝐨𝐲 Run serverless, on-demand, or dedicated. Traffic-aware autoscaling, hot restarts, and multi-replica HA keep latency and reliability steady. • Run anywhere: our managed cloud, your VPC/on-prem, or self-built clusters across regions • Observability & controls: token-level traces, metrics, budget alerts, audit logs • Uptime: 99.9%+ envelope Coming soon: 𝐄𝐢𝐠𝐞𝐧𝐂𝐥𝐨𝐮𝐝 Launching in a month—turn your SLA into a production API in a few clicks, powered by the same acceleration + reliability stack. Learn more & Compare results • Artificial Analysis provider view: https://lnkd.in/edYgbibm • Full blog: https://lnkd.in/eff-8RUW • Playground and API: https://app.eigenai.com/ • Eigen AI: https://www.eigenai.com/ Special thanks to Artificial Analysis team for the great efforts onboarding Eigen! #AI #LLM #Inference #MLOps #GenAI #Quantization #FP4 #Sparsity #SpeculativeDecoding #DevOps #Cloud #VPC #Agents #AEI
- ElizaRecorded 17 Sept 2026
Most companies have ChatGPT, but few use it for high-value, ROI-unlocking use cases. It's time to move beyond simple tasks. Eliza's 4-week, hands-on training model helps you do exactly that, embedding ChatGPT into daily workflows through: ✅ Co-build sessions with internal champions to tailor use cases by role and function ✅ Playbooks and prompts that target measurable outcomes like hours saved and quality improved ✅ Team workshops and office hours that drive adoption and confidence The result: rapid scale, high engagement, and visible ROI across the organization. Want to see this model in action? Request a free consultation to get a custom AI adoption roadmap for your organization. Fill out the form to connect.
- ElulaRecorded 17 Sept 2026
Super fund members often switch without all the facts and end up in the wrong fund for their needs. Our AI software helps you spot which former members to re-engage with. It provides insights that power the right conversations to win them back. Discover how Elula can do more for all your members. Visit elula.ai today.
- ElulaRecorded 17 Sept 2026
Millions of Australians are paying duplicate fees because they hold more than one super account. Our software uses the power of AI to identify which of your members are most likely to consolidate. That means stronger balances for your fund and better outcomes for your members. Discover more at elula.ai
- Elvex, Inc.Recorded 17 Sept 2026
🔥 Hot take: Your AI training program is a waste of money. So is your "AI champions" initiative. And your prompt library. And probably your ChatGPT Enterprise licenses. Microsoft just learned this the hard way. $35B in infrastructure spending. Aggressive sales targets. Less than 20% of reps hit quota. The companies seeing real adoption aren't training harder. They're not mandating usage. They're not appointing champions. They're doing something else entirely. Think your AI strategy is different? Read this first 👇 #EnterpriseAI #AIAdoption #GenerativeAI #AIStrategy #Leadership
- ElizaRecorded 17 Sept 2026
Is your organization stuck on 'basic' ChatGPT use? Move beyond email drafting to automated, high-impact workflows that deliver measurable ROI. Stop settling for low adoption. Eliza guarantees high-impact ChatGPT ROI in just 4 weeks with a custom adoption roadmap designed for your business. The Eliza 4-Week Impact Program Includes: ➡ Use Case Discovery Workshop: Co-create & prioritize 10–20 high-impact use cases; prototype the top set for immediate ROI. ➡ Hands-On Workshops: Role-based training (HR, Finance, Sales) to master prompts, build Custom GPTs, and automate key workflows. ➡ Change Management: AI champions program, communications, and a rollout plan to drive safe, sustained adoption. ➡ Enablement Hub: A central source for Adoption KPIs, time-Saved Mmetrics, prompts, guides, and playbooks. Proven Results from Pilot Teams: ✅ 75%+ weekly active usage. ✅ High-impact use cases saving hundreds of hours/week. ✅ An up-skilled organization ready to leverage AI as a true business differentiator. Ready to unlock guaranteed AI ROI? Request a FREE Consultation for your custom ChatGPT adoption roadmap.
- Elvex, Inc.Recorded 17 Sept 2026
Imagine if your team could connect data seamlessly across systems while leveraging advanced AI models such as ChatGPT or Claude for actionable insights instantly?
- Dyna.AiSince 4 Feb 2026
AI is no longer an experiment in banking and insurance, it’s a profit engine. From credit decisioning to claims automation, leading BFSI players are already reducing costs and unlocking new revenue streams. With the AI market projected to grow from USD 35B in 2023 to USD 368B by 2032, the gap between adopters and laggards is widening fast. Are you positioned to win?
- Dyna.AiSince 4 Feb 2026
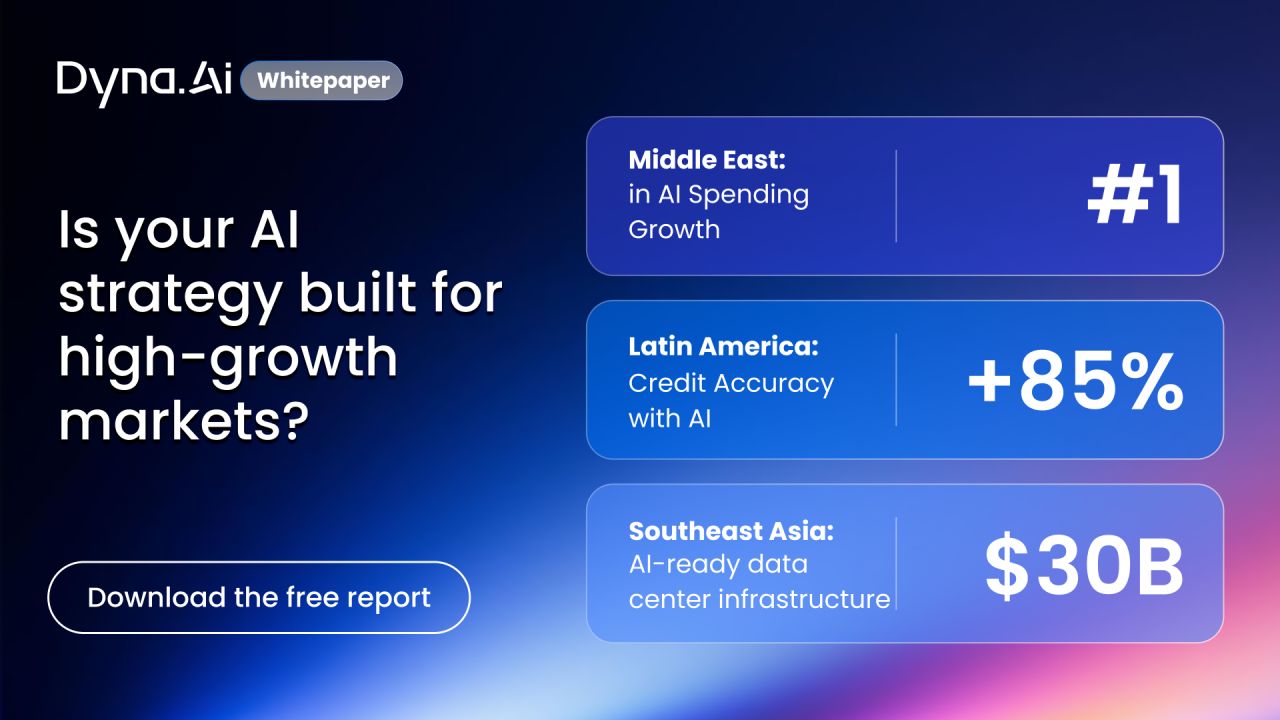
AI is driving unprecedented growth across MEA, LATAM, and SEA. Are you capturing your share? See how financial leaders are scaling AI to boost credit accuracy, digital payments, and market impact.
- DisarrayRecorded 16 Sept 2026
AI agents are increasingly deployed on long-horizon tasks across complex, fragmented enterprise systems. To do that work well, they need a unified view of the data, the code, decisions and history. Right now, most agents don't have that. They reconstruct it from scratch, on every single query. The common responses to this problem? "Just give the agent more tools." "Wait for the next model release." "An infinite context window will solve this." Fair objections. We've heard them all, and we've stress-tested them in production. Runtime reconstruction taxes every query, and the result is fragile code, authority bias toward clean-but-wrong config files, and no lasting memory once the session ends. A larger context window doesn't help when retrieved documents contradict each other and the agent has no way to tell which is canonical. Stronger models don't fix missing data infrastructure any more than faster CPUs make database indices unnecessary. We published a deep dive on why AI agents need a context graph, when it's worth building one, and what it actually takes to build it. In the article, we cover: • What a context graph is and the four operational roles it plays • The four most difficult construction challenges • The importance of calibrated trust and why it matters more than raw retrieval power • Where the engineering investment pays off and where simpler retrieval is enough Read it here: https://lnkd.in/gD89aUtX Have you run into these issues with long-running agents? Tell us your story in the comments. #AIAgents #ContextGraph #DataInfrastructure #KnowledgeGraph #EnterpriseAI #MLOps #AgenticAI #AIEngineering
- DisarrayRecorded 16 Sept 2026
AI agents are increasingly deployed on long-horizon tasks across complex, fragmented enterprise systems. To do that work well, they need a unified view of the data, the code, decisions and history. Right now, most agents don't have that. They reconstruct it from scratch, on every single query. The common responses to this problem? "Just give the agent more tools." "Wait for the next model release." "An infinite context window will solve this." Fair objections. We've heard them all, and we've stress-tested them in production. Runtime reconstruction taxes every query, and the result is fragile code, authority bias toward clean-but-wrong config files, and no lasting memory once the session ends. A larger context window doesn't help when retrieved documents contradict each other and the agent has no way to tell which is canonical. Stronger models don't fix missing data infrastructure any more than faster CPUs make database indices unnecessary. We published a deep dive on why AI agents need a context graph, when it's worth building one, and what it actually takes to build it. In the article, we cover: • What a context graph is and the four operational roles it plays • The four most difficult construction challenges • The importance of calibrated trust and why it matters more than raw retrieval power • Where the engineering investment pays off and where simpler retrieval is enough
- DKubeRecorded 16 Sept 2026
DKube reads every supplier paper for you, so you stop manually reviewing purchasing and receiving documents.
- DKubeRecorded 16 Sept 2026
DKube reconciles the documents first and sends only the exceptions to your team.
- DomynSince 24 Aug 2026
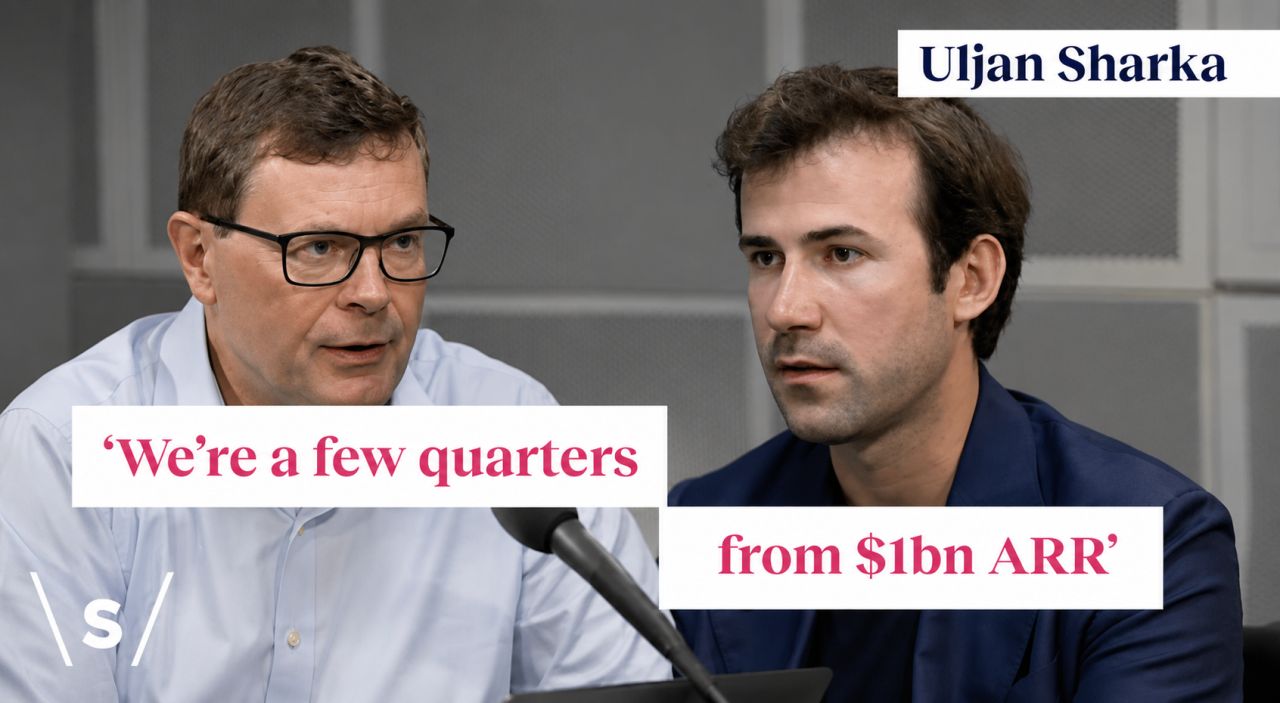
Yesterday, our CEO and Founder Uljan Sharka joined John Thornhill on the Sifted podcast for a conversation on Europe's real position in the AI race. In the podcast, Uljan discussed his own path into tech and how he came to found Domyn. He also covered why the next phase of AI will be won through applications and distribution (not model size) and how fast-improving chips are closing the compute gap faster than expected. Thank you John and the Sifted team for having Uljan on. 🎧 Listen to the full episode: https://lnkd.in/dWyYHNUp
Other LinkedIn formats
Watch the companies you care about.
Filter every ad by industry, country, format and network, and get alerts when a company you watch starts running new ads.