On air · 1 of 3 networks
Disarray
- disarray.ai
- AI
- US
- 19 employees
Disarray’s ads on LinkedIn, Meta and Google, recorded by adsrunning. Browse the latest here for free. Sign up free to see all 71. Watch Disarray with Starter to get each new one in your feed.
Watchlist with Starter · $49/mo
| Network | Status | Live ads | Nov 2025LinkedIn activity · 52 weeksOct 2026 | Checked | Next step |
|---|---|---|---|---|---|
| Running | 71 | Checked 30 Oct 2026 | See all 71 ads → | ||
| Meta | Not checked | — | |||
| None recorded | 0 | No ads found on the Google Ads Transparency Center | Checked 27 Oct 2026 | Collect them with the API → |
Disarray has 71 live LinkedIn ads. We recorded no Google ads on 27 Oct 2026.
Latest ads
- LINKEDIN · IMAGERecorded 16 Sept 2026
In a TechCrunch article on RSI, I was quoted saying “[RSI] is not a creative endeavor.” What makes me say this? To oversimplify, RSI is about finding configurations that lead to AI improvement from a vast, uncertain space. With infinite resources, you can sample randomly until something works. Without infinite resources, progress depends on testing high-quality hypotheses. That is where “creativity” comes in. A creative breakthrough often means sampling from a subspace no one had thought to search before. AI can test far more hypotheses than humans, but it can’t generate good, novel hypotheses effectively if it doesn’t understand the entire search space and can’t leverage existing knowledge to prune the space for efficiency. The "meat and potatoes engineering" I was referring to is about building specific mechanisms to overcome these limitations: A context graph tells an agent what has already been tried, which evidence is trustworthy, which assumptions are stale, and where adjacent opportunities may exist. A harness keeps the search process coherent over time, so the agent does not lose state, repeat failed work, overtrust its own judgment, or keep pursuing a bad trajectory. These are the hard engineering challenges we need to solve to meaningfully move towards RSI today. The full TechCrunch article by Russell Brandom offers diverse perspectives on the topic from luminaries in the field and a sharp synthesis: https://lnkd.in/gWy6qqas
- LINKEDIN · IMAGERecorded 16 Sept 2026
It's always energizing when one of our founders helps move an industry conversation forward. This week, TechCrunch's Russell Brandom dug into one of the most-hyped (and least-understood) ideas in AI right now: recursive self-improvement (RSI), the point at which AI systems can meaningfully improve themselves. For the piece, he turned to Doris Xin, Co-Founder & CEO of .406 portfolio company Disarray. Doris doesn't see #RSI the way most of the field does. The common view treats it as a problem of intelligence, that once models get smart enough, they'll start improving themselves. Her argument is that the intelligence is largely here already, and what's missing is the infrastructure to put it to work: "Given infinite compute and infinite time horizon, we are already there. I want to make an argument that this is not a creative endeavor, really. It's just a lot of meat-and-potatoes engineering." It's a characteristically clear-eyed take from someone who builds rather than speculates. She demonstrated the value of infrastructure to activate the current model intelligence in her recent 24-hour run, where on a single A100, Disarray's MLE agent earned 28 Kaggle medals, with nine top-10 finishes and a #1 ranking ahead of every human team. Congratulations to Doris and the team on the well-deserved recognition. You can read the full article below. https://lnkd.in/eEt3fVk2 Moustafa AbdelBaky, Kevin C. Wang
- LINKEDIN · IMAGERecorded 16 Sept 2026
The term recursive self-improvement (RSI) is everywhere right now, appearing in roadmaps, startup names and near-term visions of AI systems that improve themselves with little to no human input. But what does it actually take to get there? TechCrunch's Russell Brandom dug into that question in an article titled “RSI is the new AGI — and it’s just as hard to pin down,” and as part of his reporting, he spoke to our CEO Doris Xin about it. The common framing treats RSI as a problem of intelligence. As the frontier models get smarter, they’ll eventually be able to improve themselves. Jack Clark, Anthropic's co-founder recently wrote on his Substack that he expects RSI to arrive by the end of 2028. Others, including Doris, believe it will happen much sooner, as early as next year. She takes this position because she argues models already possess the intelligence for RSI, but lack the required infrastructure, and developing that infrastructure will happen much more quickly than the release of new frontier models. Brandom quotes Doris in his article saying, "I would argue, given infinite compute and infinite time horizon, we are already there. I want to make an argument that this is not a creative endeavor, really. It's just a lot of meat-and-potatoes engineering." That framing tracks with what we see in enterprise ML every day. The bottleneck is rarely the model, but rather the context that's fragmented, and the lack of agentic supervision that can help it determine the value of continuing on the current trajectory. Read the full TechCrunch piece here: https://lnkd.in/ewAMwrdg Where do you think the real bottleneck is on the path to self-improving AI systems? Drop your take in the comments.
- LINKEDIN · IMAGERecorded 16 Sept 2026
The term recursive self-improvement (RSI) is everywhere right now, appearing in roadmaps, startup names and near-term visions of AI systems that improve themselves with little to no human input. But what does it actually take to get there? TechCrunch's Russell Brandom dug into that question in an article titled “RSI is the new AGI — and it’s just as hard to pin down,” and as part of his reporting, he spoke to our CEO Doris Xin about it. The common framing treats RSI as a problem of intelligence. As the frontier models get smarter, they’ll eventually be able to improve themselves. Jack Clark, Anthropic's co-founder recently wrote on his Substack that he expects RSI to arrive by the end of 2028. Others, including Doris, believe it will happen much sooner, as early as next year. She takes this position because she argues models already possess the intelligence for RSI, but lack the required infrastructure, and developing that infrastructure will happen much more quickly than the release of new frontier models. Brandom quotes Doris in his article saying, "I would argue, given infinite compute and infinite time horizon, we are already there. I want to make an argument that this is not a creative endeavor, really. It's just a lot of meat-and-potatoes engineering." That framing tracks with what we see in enterprise ML every day. The bottleneck is rarely the model, but rather the context that's fragmented, and the lack of agentic supervision that can help it determine the value of continuing on the current trajectory.
- LINKEDIN · IMAGERecorded 16 Sept 2026
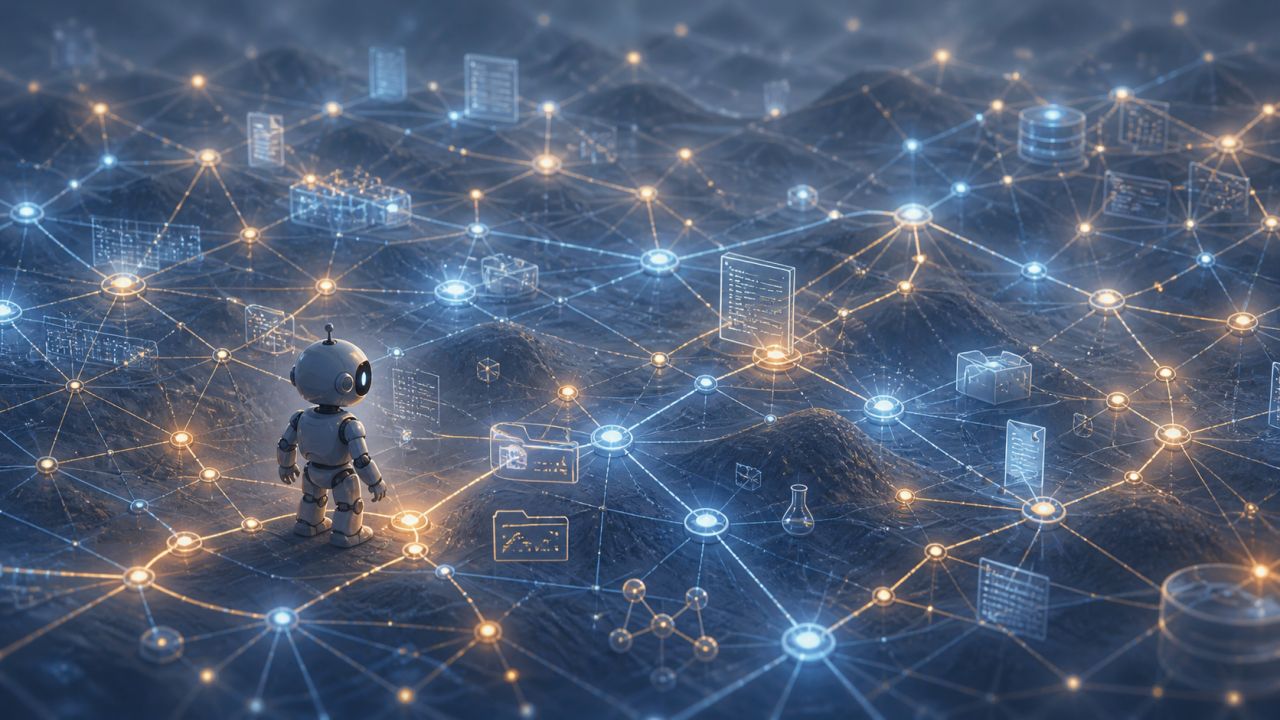
AI agents are increasingly deployed on long-horizon tasks across complex, fragmented enterprise systems. To do that work well, they need a unified view of the data, the code, decisions and history. Right now, most agents don't have that. They reconstruct it from scratch, on every single query. The common responses to this problem? "Just give the agent more tools." "Wait for the next model release." "An infinite context window will solve this." Fair objections. We've heard them all, and we've stress-tested them in production. Runtime reconstruction taxes every query, and the result is fragile code, authority bias toward clean-but-wrong config files, and no lasting memory once the session ends. A larger context window doesn't help when retrieved documents contradict each other and the agent has no way to tell which is canonical. Stronger models don't fix missing data infrastructure any more than faster CPUs make database indices unnecessary. We published a deep dive on why AI agents need a context graph, when it's worth building one, and what it actually takes to build it. In the article, we cover: • What a context graph is and the four operational roles it plays • The four most difficult construction challenges • The importance of calibrated trust and why it matters more than raw retrieval power • Where the engineering investment pays off and where simpler retrieval is enough
- LINKEDIN · IMAGERecorded 16 Sept 2026
AI agents are increasingly deployed on long-horizon tasks across complex, fragmented enterprise systems. To do that work well, they need a unified view of the data, the code, decisions and history. Right now, most agents don't have that. They reconstruct it from scratch, on every single query. The common responses to this problem? "Just give the agent more tools." "Wait for the next model release." "An infinite context window will solve this." Fair objections. We've heard them all, and we've stress-tested them in production. Runtime reconstruction taxes every query, and the result is fragile code, authority bias toward clean-but-wrong config files, and no lasting memory once the session ends. A larger context window doesn't help when retrieved documents contradict each other and the agent has no way to tell which is canonical. Stronger models don't fix missing data infrastructure any more than faster CPUs make database indices unnecessary. We published a deep dive on why AI agents need a context graph, when it's worth building one, and what it actually takes to build it. In the article, we cover: • What a context graph is and the four operational roles it plays • The four most difficult construction challenges • The importance of calibrated trust and why it matters more than raw retrieval power • Where the engineering investment pays off and where simpler retrieval is enough Read it here: https://lnkd.in/gD89aUtX Have you run into these issues with long-running agents? Tell us your story in the comments. #AIAgents #ContextGraph #DataInfrastructure #KnowledgeGraph #EnterpriseAI #MLOps #AgenticAI #AIEngineering
6 of 71 adsSign up to see every Disarray ad, filter by format and date, and get alerts on new ones.
See all 71 adsWatch the companies you care about.
Filter every ad by industry, country, format and network, and get alerts when a company you watch starts running new ads.