Not on air · 2 of 3 networks checked

VeloDB (Powered by Apache Doris) ads
- velodb.io
- Technology, Information and Internet
- US
- 51 employees
VeloDB (Powered by Apache Doris)’s ads on LinkedIn, Meta and Google, recorded by adsrunning. Browse the latest here for free. Sign up free to see all 215. Watch VeloDB (Powered by Apache Doris) on any plan to get each new one in your feed.
Watchlist included in every plan
What VeloDB (Powered by Apache Doris) runs
- Single image · LinkedIn
- 6
- Google ads on 16 Oct 2026
- 24
| Network | Status | Live ads | Nov 2025LinkedIn activity · 52 weeksNov 2026 | Checked | Next step |
|---|---|---|---|---|---|
| None recorded | 0 | Checked 3 Nov 2026 | See all 215 ads → | ||
| Meta | Not checked | — | |||
| Recently | 24 | Ads on the Google Ads Transparency Center | Checked 16 Oct 2026 | Collect them with the API → |
VeloDB (Powered by Apache Doris) has no live LinkedIn ads. We recorded 24 Google ads on 16 Oct 2026.
Latest ads
- LINKEDIN · IMAGESince 14 Oct 2026
2026 has been the year of agents. Join us online on October 21 and 22 for Doris Summit 2026! Apache Doris has been supporting a new kind of power user: AI agents. They bring new demands for data freshness, query speed, and access to multimodal context. Come see how Apache Doris is evolving for these workloads, including a preview of the upcoming Apache Doris 5.0 capabilities. This year, we have 31 sessions from 34 speakers. Hear from the engineers building Apache Doris and teams at HubSpot, Sony Interactive Entertainment, Atlassian, Apache Fluss, Raiffeisen Bank Romania, LanceDB, Columnar, EMQ, AutoMQ, and more. Bring your questions and check out the full agenda in the registration link below 👇 📅 October 21–22, 2026 🌐 Free and online 👉 Register: https://lnkd.in/gkg_Cg5i #ApacheDoris #DorisSummit2026
- LINKEDIN · IMAGESince 12 Sept 2026
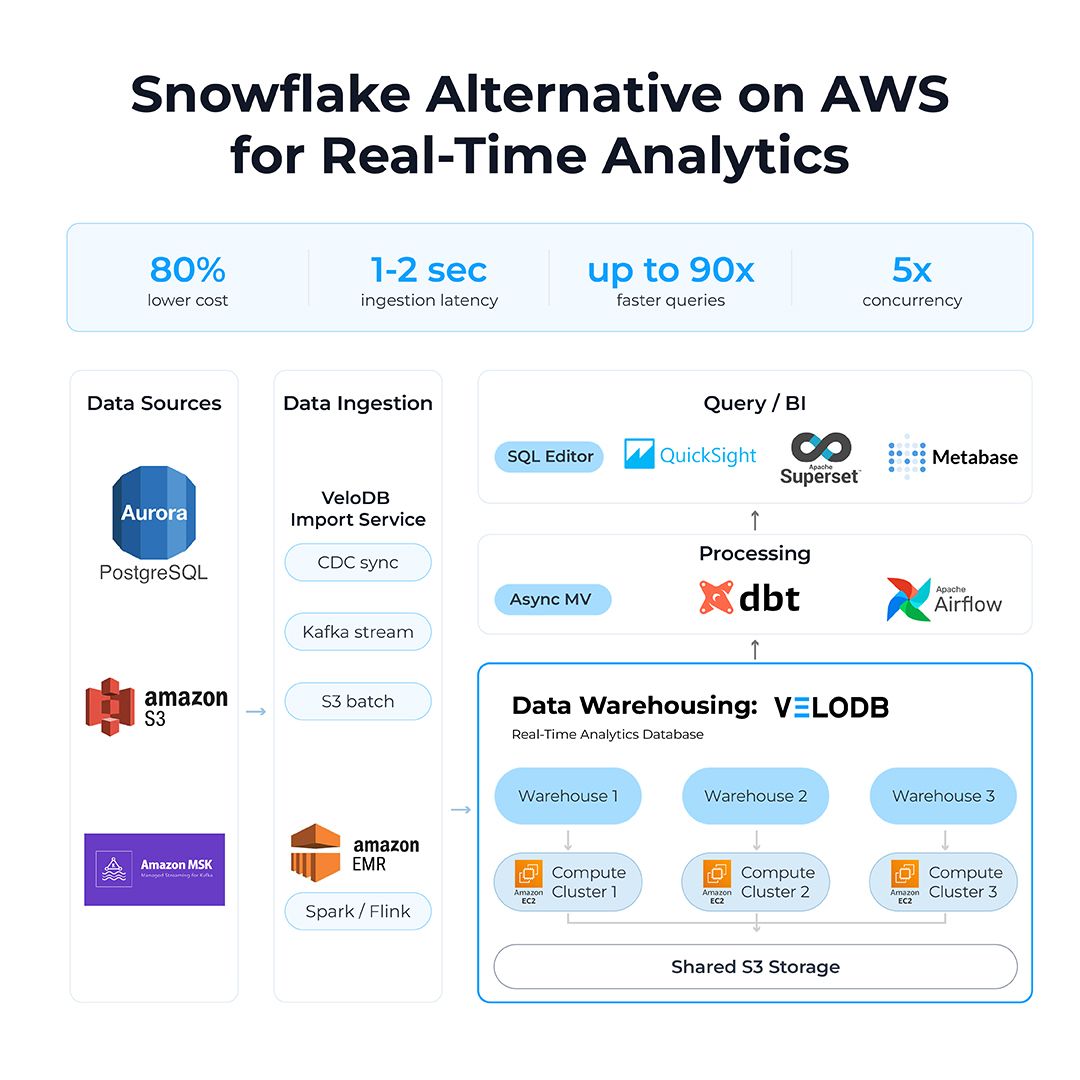
Build a Snowflake alternative on AWS and get real-time, high-concurrency analytics at a much lower cost. 💡 Results: A fintech team moved TB-scale analytics from Snowflake to the alternative build on AWS. - 80% lower monthly cost (cut from $25,000 to $5,000) - 1-2 second ingestion latency - up to 90x faster queries on 475M-row scans 💡 Architecture: 1️⃣ Data Sources: Aurora Postgres, S3, AWS MSK 2️⃣ Data Ingestion: ↳ VeloDB provide native CDC for Postgres, Routine Load for Kafka, and handles S3 with batch imports ↳ Amazone EMR (Spark, Flink): VeloDB provides Spark and Flink connectors for additional batch and streaming ingestion 3️⃣ Data Warehouse: VeloDB Cloud, a real-time analytics database deployed on AWS, provides data warehousing, with storage-compute separated architecture, offering data storage, compute cluster, and metadata management 4️⃣ Data Processing: dbt Connector, async materialized views, and Airflow ETL jobs run on top of VeloDB 5️⃣ Data Visualization: AWS QuickSight, Superset, Metabase query VeloDB directly 💡 Why build a Snowflake alternative on cloud: - AI agents are becoming the new users of databases and warehouses. Consumption-based pricing model could become very unpredictable and expensive with agents. - Build the real-time analytics at a cheaper price, set the infra ready for large-scale agent workloads. 🔗 More details in blog: https://lnkd.in/g2ibEgjB 🔗 30-day free trial of VeloDB on AWS: https://lnkd.in/gqYKpF9M #AWS, #ApacheDoris, #Snowflake
- LINKEDIN · IMAGESince 24 Jul 2026
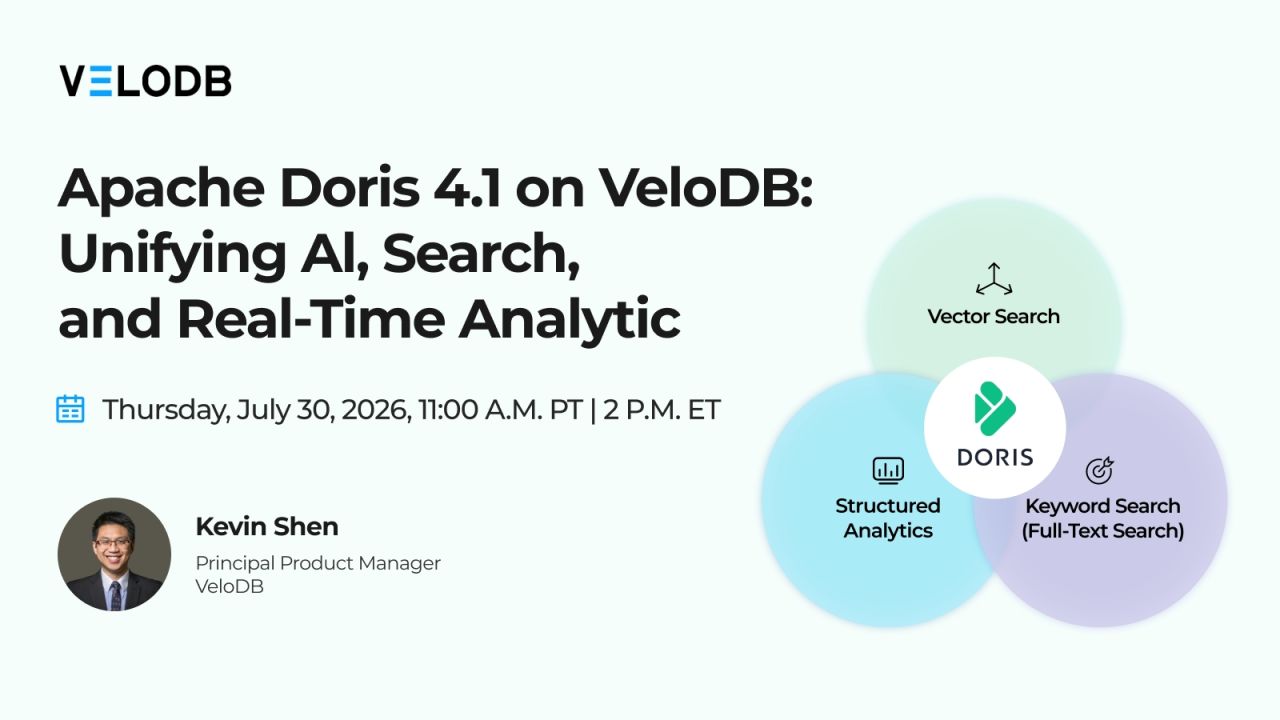
Supporting AI workloads often means managing too many systems: a vector database, a search engine, and an analytical database. Join our webinar to see how Apache Doris 4.1 brings AI, search, and real-time analytics into one SQL engine. Doris 4.1 also ranked first on ClickBench in cold query, and runs faster than 4.0 across standard benchmarks. Key Takeaways: 1️⃣ What’s new in Apache Doris 4.1: larger vector indexes (IVF), BM25 scoring, and 100MB JSON documents for long-context AI. 2️⃣ Live walkthrough: Apache Doris 4.1 on VeloDB Cloud, from AI search to real-time analytics 📅 Thursday, July 30, 11:00 AM PT | 2:00 PM ET #ApacheDoris #VectorSearch #HybridSearch #RealTimeAnalytics #AI
- LINKEDIN · IMAGESince 11 Jul 2026
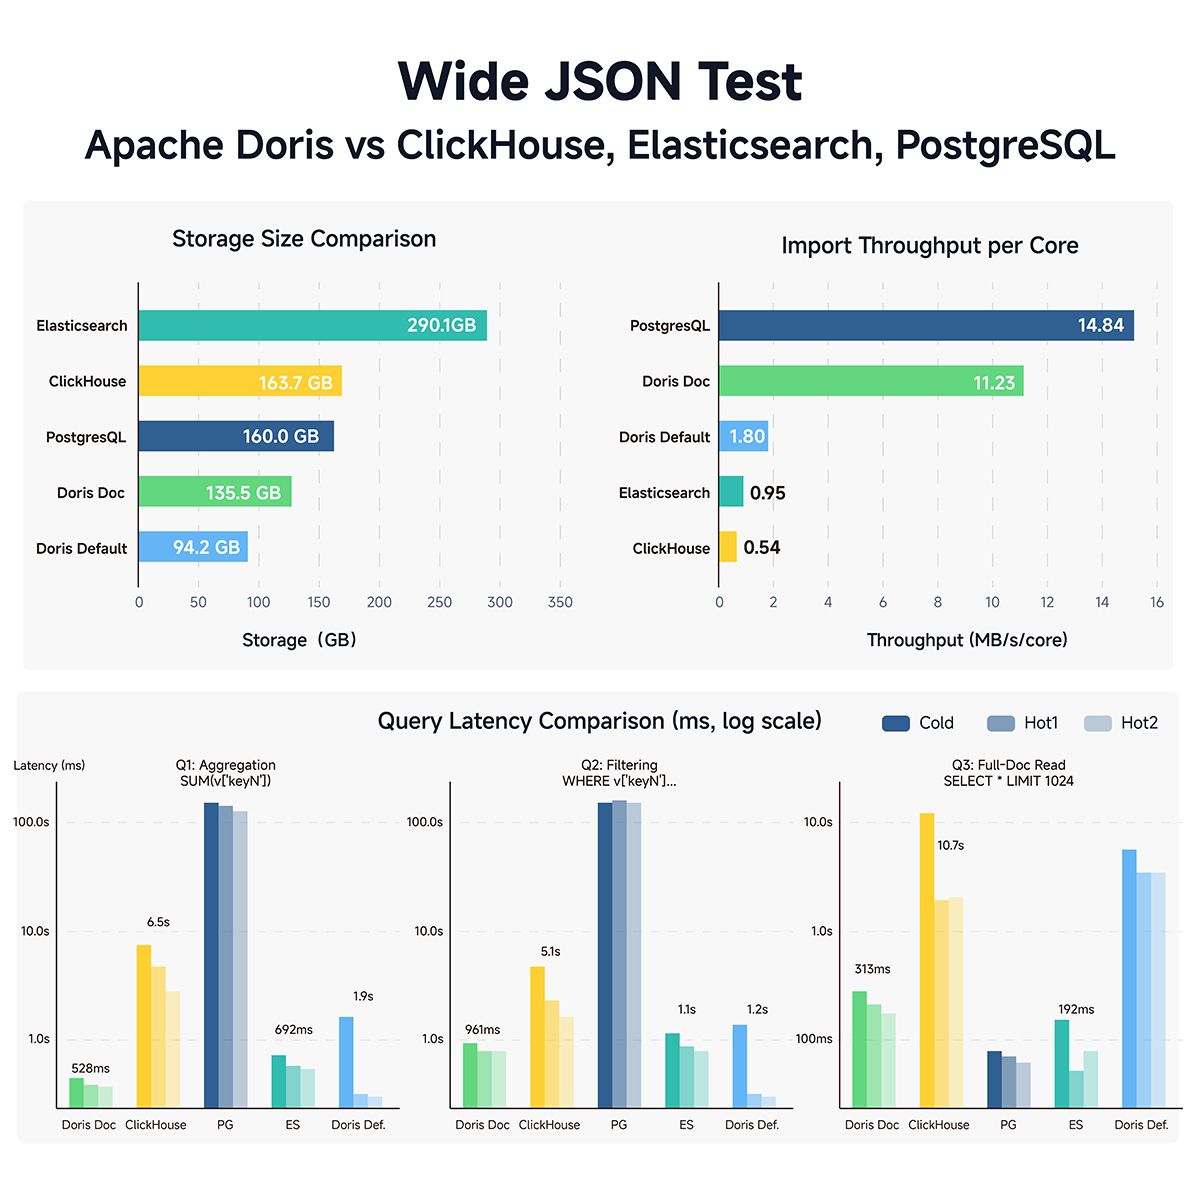
We tested Apache Doris against ClickHouse, Elasticsearch, and PostgreSQL on wide JSON workload. Wide JSON matters because it is close to how real operational data shows up in modern systems. Test Setup: - About 10,000 unique JSON paths - No fixed schema - Each row fills ~100 random keys (1% sparsity) - 100M rows, ~160 GB raw data - 1,000 input files - Single machine: 16 cores, 64 GB RAM, SSD Systems tested: - Apache Doris 4.1: default VARIANT - Apache Doris 4.1: DOC mode + Storage Format V3 - ClickHouse 26.3 - Elasticsearch 9.3.0 - PostgreSQL 14.4 Results: 1️⃣ Storage footprint Doris Default: 94 GB Doris DOC mode: 135 GB PostgreSQL: 160 GB ClickHouse: 164 GB Elasticsearch: 290 GB Doris Default produced the most compact storage. Elasticsearch used nearly 2x the raw data size. 2️⃣ Import throughput (MB/s per core) PostgreSQL: 14.84 Doris DOC mode: 11.23 Doris Default: 1.80 Elasticsearch: 0.95 ClickHouse: 0.54 PostgreSQL led on ingestion. Doris DOC mode stayed close. ClickHouse was 27x slower than PostgreSQL in this test. 3️⃣ Query latency (cold run) - Aggregation: Doris DOC: 528ms / ClickHouse: 6.5s / Elasticsearch: 692ms / PostgreSQL: 100s+ - Filtering: Doris Doc: 961ms / ClickHouse: 5.1s / Elasticsearch: 1.1s / PostgreSQL: 100s+ - Full-document read: PostgreSQL: ~100ms (fastest here) / Elasticsearch: 192ms / Doris Doc: 313ms / ClickHouse: 10.7s The takeaway: - Every system had a strong point. - PostgreSQL was excellent at document storage and full-row reads. - ClickHouse remains strong for analytics when the field count is bounded. - Elasticsearch performed well on retrieval-style workloads. The trade-offs were also clear: - PostgreSQL struggled with analytical queries on Q1 and Q2. - ClickHouse was much slower on writes and full-document reads in this wide-JSON test. - Elasticsearch had the largest storage footprint. Apache Doris DOC mode was the only configuration that stayed competitive across storage, ingestion, and query latency at the same time. That's why we updated DOC mode + Storage Format V3 in Apache Doris 4.1, making wide JSON analytics practical without forcing teams to choose between compact storage, fast ingestion, and low-latency queries. 🔗 More details in blog for DOC mode and Storage Format V3: https://lnkd.in/gYf3bytp #JSON, #ClickHouse, #PostgreSQL, #Elasticsearch
- LINKEDIN · IMAGESince 9 Jul 2026
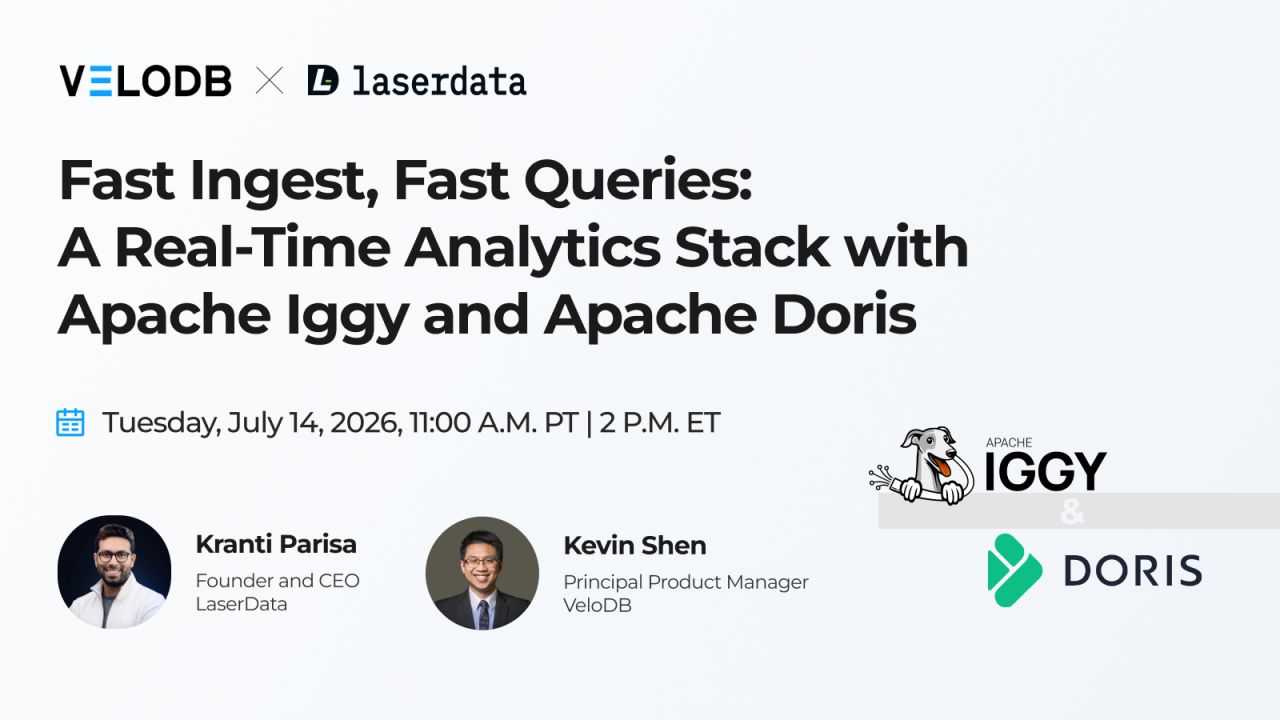
Join us for a webinar on building a real-time analytics stack with Apache Iggy and Apache Doris. You get a leaner, open-source stack: - Apache Iggy handles high-throughput, low-latency event streaming. - Apache Doris serves fresh data with sub-second analytical queries. Key Takeaways: 1️⃣ Benchmark: Iggy delivered 3x throughput and 29x lower P99 latency than Kafka in the same Doris pipeline. 2️⃣ Demo: Apache Iggy → Iggy sink connector → Apache Doris for real-time analytics Iggy is a a fast, persistent message streaming platform written in Rust. Doris is a real-time search and analytics database. 📅 July 14, 11:00 AM PT | 2:00 PM ET
- LINKEDIN · IMAGESince 9 Jun 2026
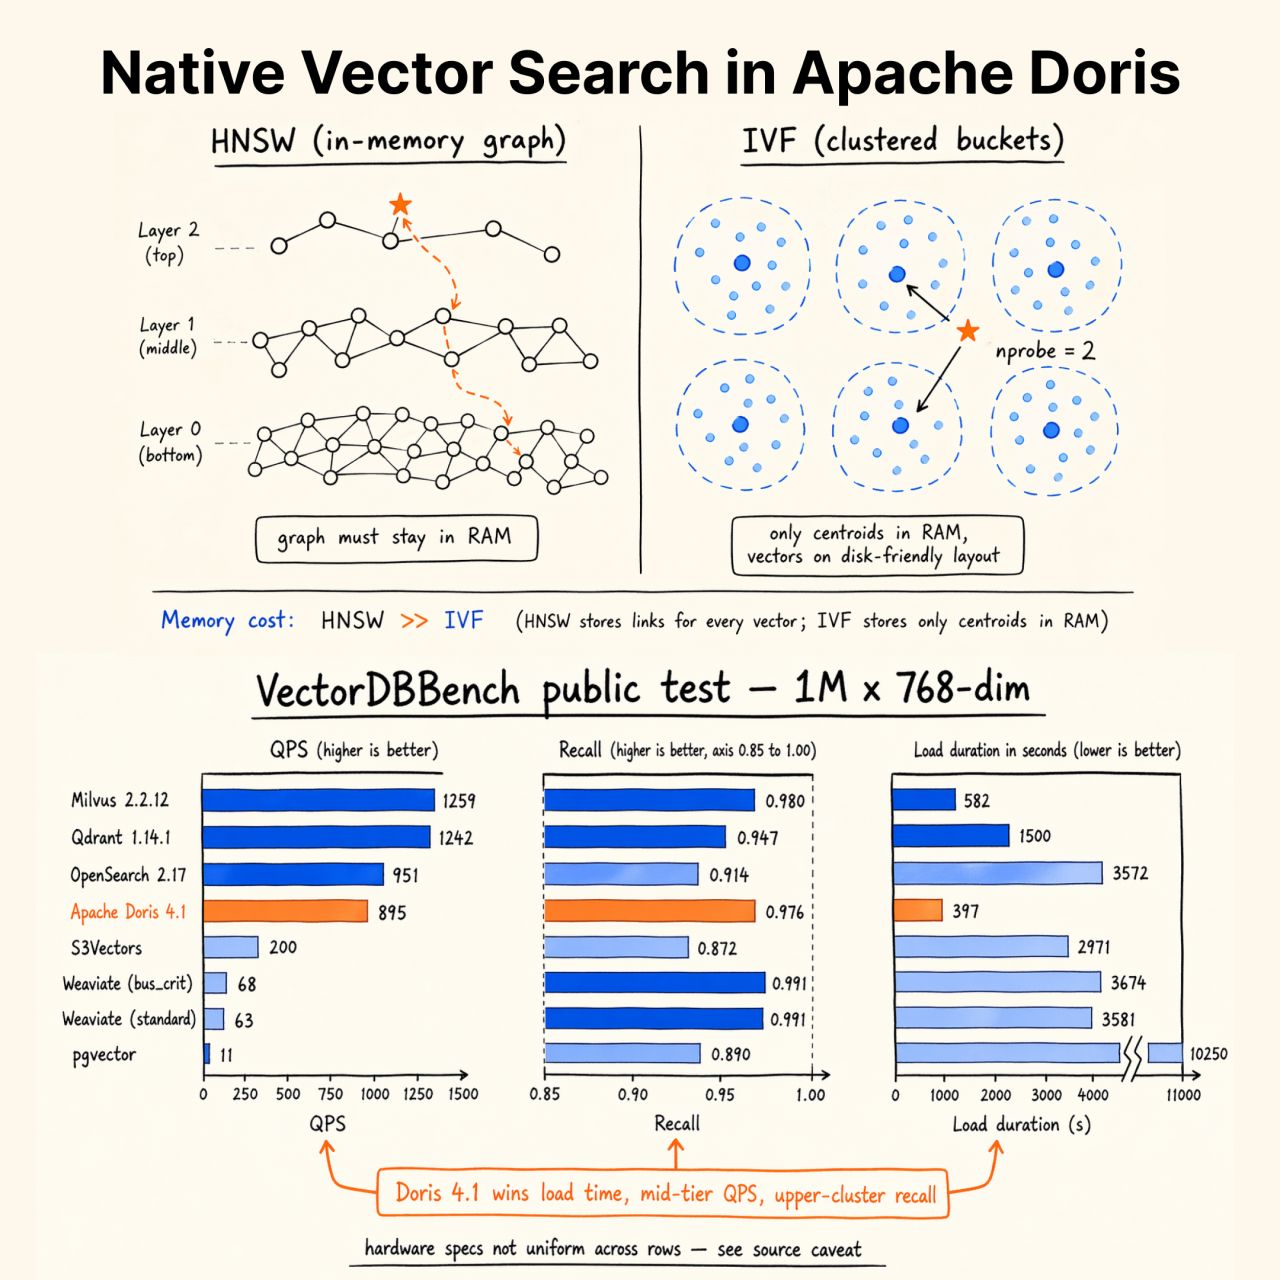
The vector index you pick for AI workloads determines many key factors: memory footprint, latency, and how far the system scales. Apache Doris 4.1 offers native vector search, with different index choices designed to match each scale tier: 1️⃣ Vector Indexes: ↳ HNSW: best for millions of vectors HNSW offers in-memory graph, high recall, low latency. The tradeoff is it roughly doubles your memory footprint. A billion 768-dim vectors approach 1 TB in memory. Works well for smaller datasets with strict recall requirements. ↳ IVF: best for tens to hundreds of millions of vectors IVF offers k-means clustering partitions vectors into buckets. Queries check only the closest clusters. Memory requirements drop substantially because only centroids and bucket mappings stay in memory, not the vectors themselves. ↳ IVF_ON_DISK / SPANN: best for vectors more than billions Offers centroids in memory, bucket data on SSD. Hot buckets stay cached, cold buckets read from disk. Billion-scale vector workloads on commodity hardware, no GPU required. 2️⃣ Optimization on top: ↳ Quantization (INT8, INT4, PQ): Product Quantization compresses 768-dim float32 vectors from 3,072 bytes to 64 bytes (48x). Typical recall loss is 1-3%, tunable by how many sub-vectors you split into. ↳ Pre-filter vs post-filter: This is the advantage of using vector search inside an analytical database like Apache Doris. Because you can combine vector search with structured SQL filters. Pre-filtering narrows candidates but loses index structure, post-filtering keeps index efficiency but may cut results short. Doris picks dynamically based on predicate selectivity. 3️⃣ Doris Vector Search Performance: Results from VectorDBBench (1M × 768-dim, 16-core/64GB) in Jan 2026: - 895 QPS at 97.6% recall - Fastest index build time of the systems tested: Doris at 397s, Milvus at 582s, OpenSearch at 3,572s, pgvector at 10,250s. 🔗 Full engineering breakdown by Mingyu Chen, Apache Doris PMC: https://lnkd.in/gc3q8Thw #ApacheDoris #VectorSearch #Infra #HNSW #IVF
6 of 215 adsSign up to see every VeloDB (Powered by Apache Doris) ad, filter by format and date, and get alerts on new ones.
See all 215 adsQuestions about VeloDB (Powered by Apache Doris)’s ads
Is VeloDB (Powered by Apache Doris) running LinkedIn ads?
We recorded no live LinkedIn ads for VeloDB (Powered by Apache Doris) on 7 Nov 2026.
How many LinkedIn ads has VeloDB (Powered by Apache Doris) run?
LinkedIn’s ad library lists 190 ads for VeloDB (Powered by Apache Doris). We recorded 215 LinkedIn ads for VeloDB (Powered by Apache Doris), first recorded on 3 Oct 2026 and last recorded on 30 Oct 2026.
Does VeloDB (Powered by Apache Doris) run Google ads?
Yes. We recorded 24 Google ads for the domain velodb.io on 16 Oct 2026.
Which ad formats does VeloDB (Powered by Apache Doris) use?
The 6 LinkedIn ads on this page include 6 image ads.
Watch the companies you care about.
Filter every ad by industry, country, format and network, and get alerts when a company you watch starts running new ads.