Not on air · 2 of 3 networks checked
vCluster
- vcluster.com
- Software Development
- US
- 115 employees
vCluster’s ads on LinkedIn, Meta and Google, recorded by adsrunning. Browse the latest here for free. Sign up free to see all 256. Watch vCluster on any plan to get each new one in your feed.
Watchlist included in every plan
| Network | Status | Live ads | Nov 2025LinkedIn activity · 52 weeksNov 2026 | Checked | Next step |
|---|---|---|---|---|---|
| None recorded | 0 | Checked 3 Nov 2026 | See all 256 ads → | ||
| Meta | Not checked | — | |||
| Recently | 20 | Ads on the Google Ads Transparency Center | Checked 14 Oct 2026 | Collect them with the API → |
vCluster has no live LinkedIn ads. We recorded 20 Google ads on 14 Oct 2026.
Latest ads
- LINKEDIN · IMAGESince 26 Oct 2026
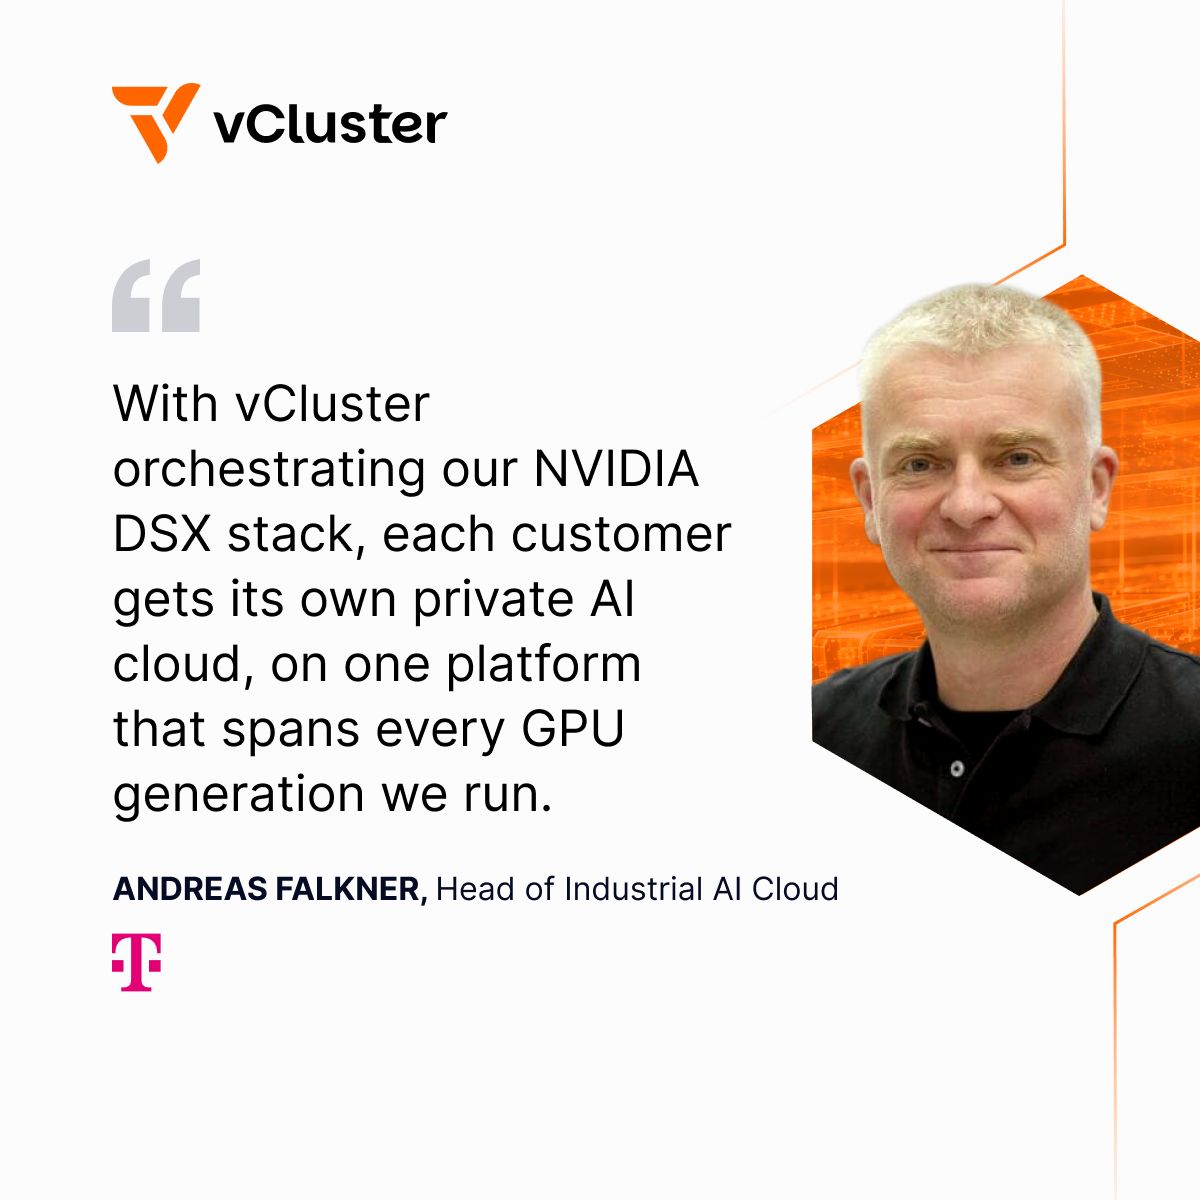
Andreas Falkner leads the Industrial AI Cloud at Deutsche Telekom, and his team now gives every customer its own private AI cloud on a single platform. That platform runs on NVIDIA RTX PRO Servers and DGX B200 today, with DGX B300 to follow, and new GPU generations join behind the same customer-facing APIs. Thank you to Andreas Falkner and the Telekom team for building this with us. Read the full announcement: https://lnkd.in/eBV6zE-f
- LINKEDIN · IMAGESince 26 Oct 2026
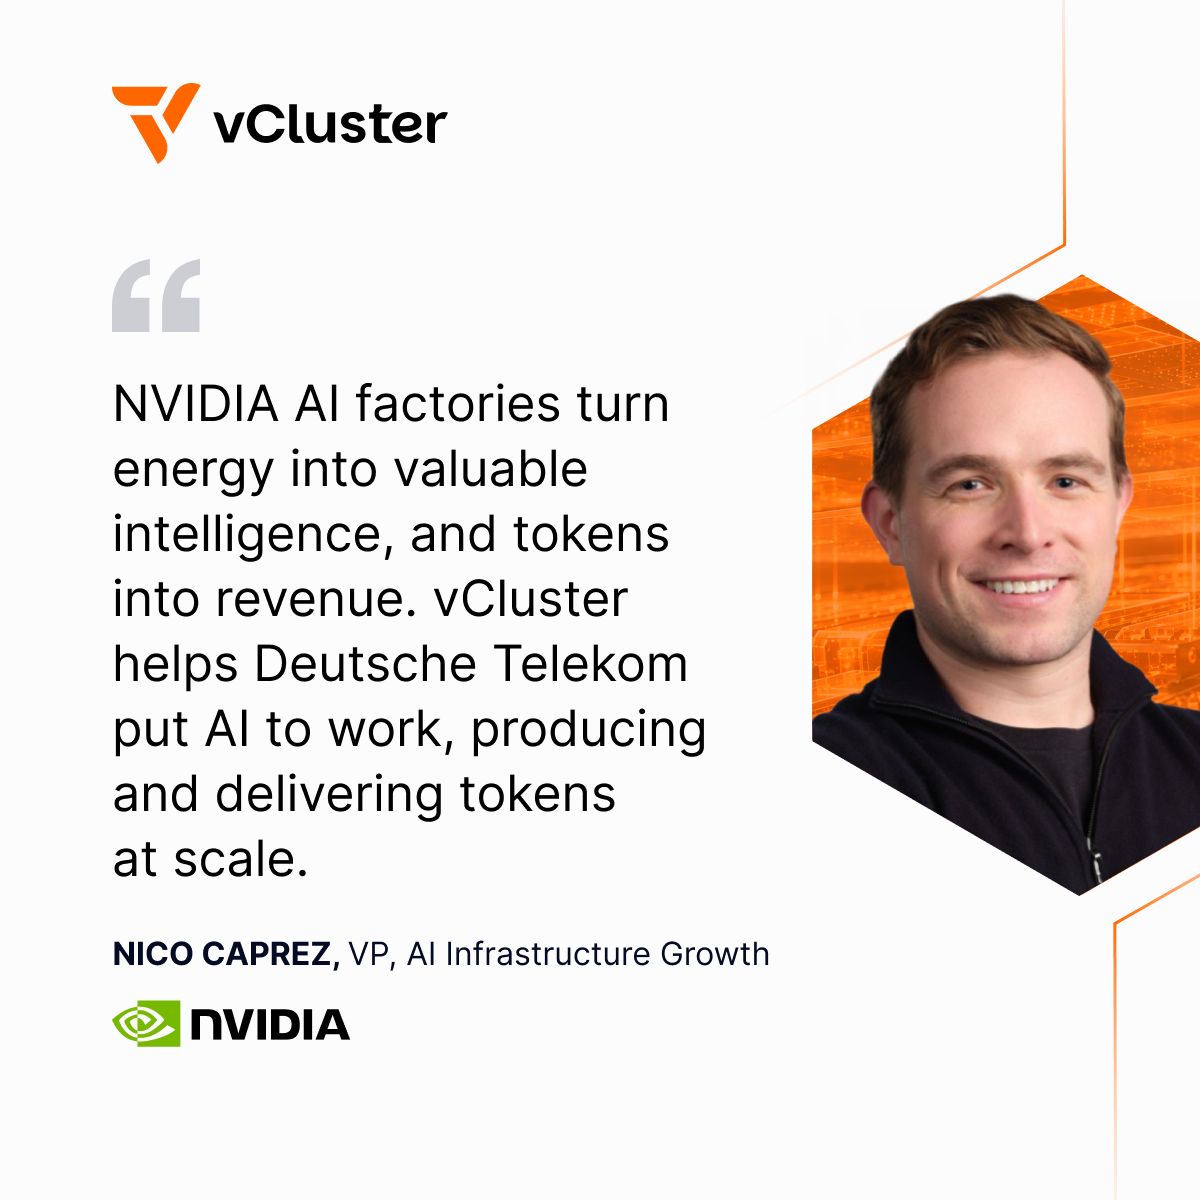
We're grateful to Nico Caprez and the NVIDIA DSX team for working with us on Deutsche Telekom's Industrial AI Cloud. vCluster orchestrates core DSX OS components there, including NVSentinel, the GPU Operator and the Network Operator, into an automated path from raw GPUs to a private AI cloud for each customer. Any NVIDIA Cloud Partner can follow the same blueprint. Read the full announcement: https://lnkd.in/eBV6zE-f
- LINKEDIN · IMAGESince 26 Oct 2026
Every new customer on Deutsche Telekom's Industrial AI Cloud signs in to its own Telekom-branded portal at its own URL. From there, the customer picks how to run its workloads: Kubernetes, Slurm, GPU virtual machines, or bare metal with Deutsche Telekom golden images. That speed matters for where the platform is headed. Deutsche Telekom runs 500 NVIDIA GPUs on it today and expects to pass 10,000 NVIDIA Blackwell and Rubin GPUs, with every new customer getting the same isolated setup. Read the announcement: https://lnkd.in/eBV6zE-f
- LINKEDIN · IMAGESince 22 Oct 2026
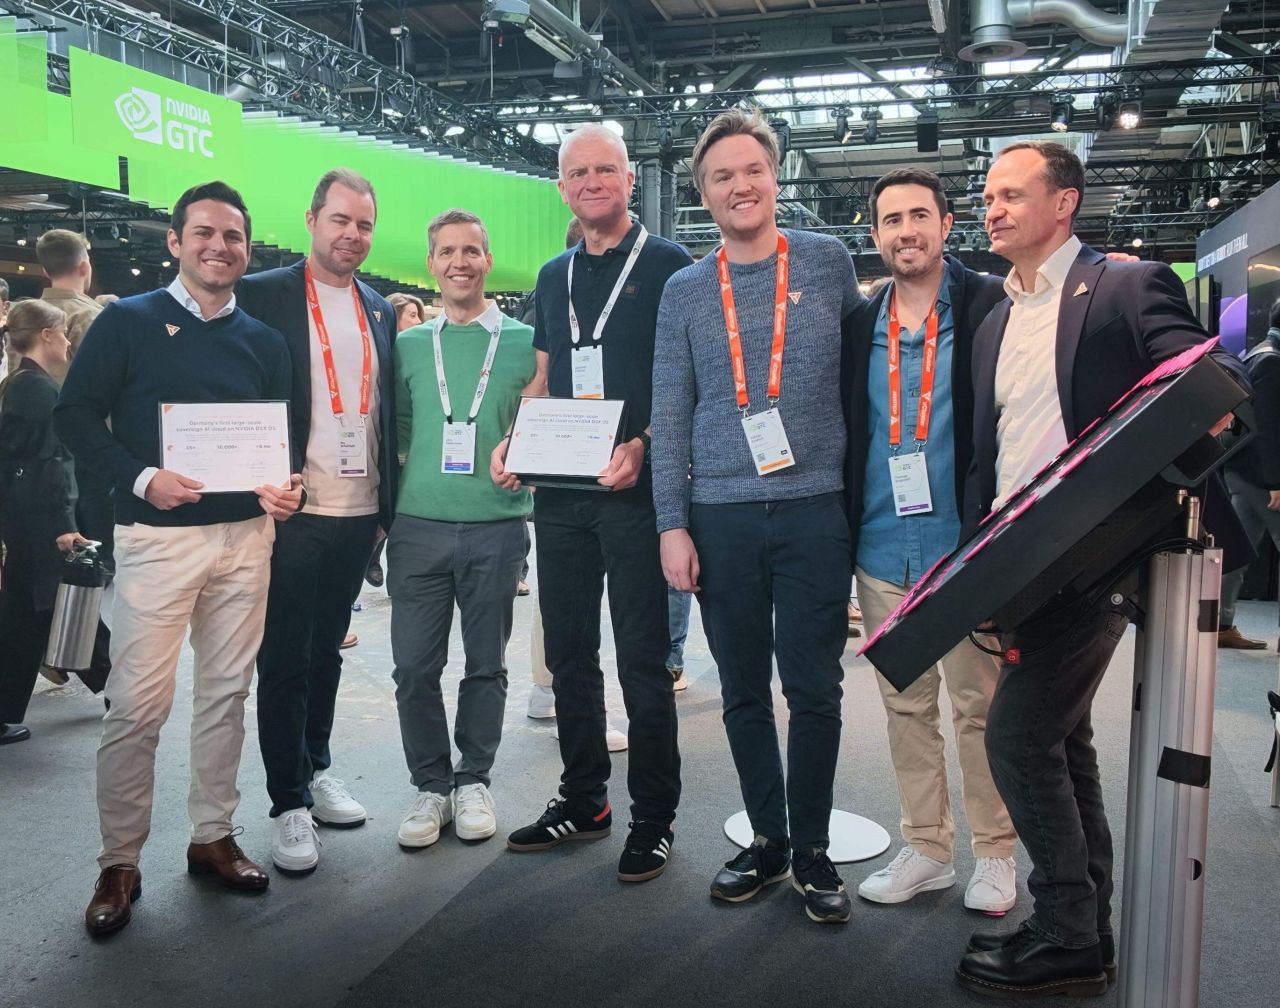
I started vCluster with a group of German engineers. Today Germany’s national telco announced that the AI cloud it’s building for German industry runs on what we built. The part I’m proudest of isn’t the headline. Six months ago, bringing a new customer onto the Industrial AI Cloud took days of manual work across three teams. Today it takes one click, and every customer gets its own private AI cloud. This afternoon Andreas Falkner and I signed a certificate at the Deutsche Telekom booth at NVIDIA GTC Berlin marking the milestone. Thank you to Andreas and the Deutsche Telekom team, and to Nico Caprez and the NVIDIA team. Any NVIDIA Cloud Partner can follow this path, and we’d like to help. Announcement: https://lnkd.in/eGTNkEhC
- LINKEDIN · IMAGESince 21 Oct 2026
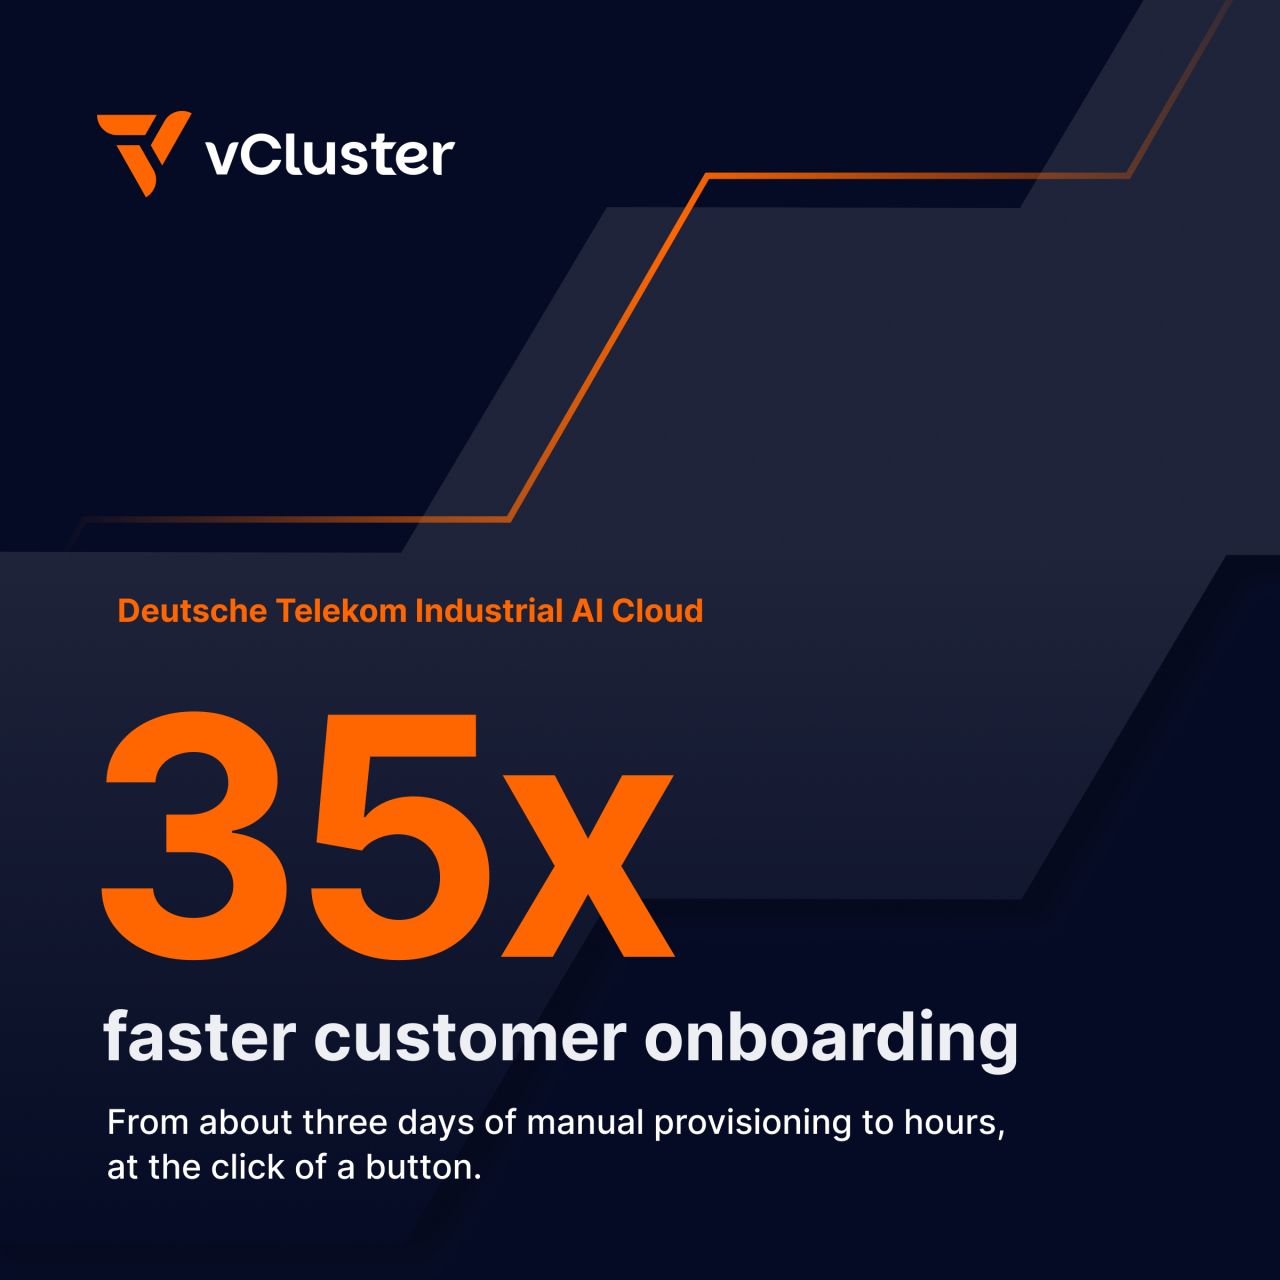
Deutsche Telekom's Industrial AI Cloud is the first large-scale industrial AI cloud to put NVIDIA DSX OS into production, and vCluster automates the private AI cloud each of its customers gets. Deutsche Telekom did it less than six months after NVIDIA launched DSX OS. Onboarding a new industrial customer used to take days of manual work across network, platform, and infrastructure teams. Now it takes hours and starts with a click. Every customer gets its own private AI cloud, with its own URL, cloud console, control plane, observability, and isolated network. Their data stays in Germany. A leading German automaker is the first customer running on it. The platform runs on 500 NVIDIA GPUs today across RTX PRO Servers and DGX B200, with DGX B300 to follow. Deutsche Telekom expects to scale past 10,000 NVIDIA Blackwell and Rubin GPUs, and future systems like Vera Rubin NVL72 can join behind the same customer-facing APIs. vCluster Labs was founded by German engineers, so it means a lot to see this happen in Germany first. Any NVIDIA Cloud Partner can follow the same blueprint. Read the announcement: https://lnkd.in/eBV6zE-f
- LINKEDIN · IMAGESince 30 Sept 2026
Once you have the GPUs, inference stops being a compute problem and becomes a memory problem. Lukas Gentele sat down with Shimon Ben-David, CTO at WEKA, to talk about what actually limits token output. They covered: - The real bottleneck for tokens. Long context windows fill GPU high bandwidth memory fast, and when it runs out, GPUs waste cycles recomputing tokens they already calculated. - Training vs. inference storage. Training is batch oriented and can run for weeks. Inference is real time, with users and agents expecting a response in under a second. - The token warehouse. KV cache overflows to storage instead of being deleted, so a GPU loads in a second what would take a minute to recompute. Partners have verified 6x to 10x more tokens. - Tenant isolation for AI Clouds. Some operators now require dedicated NVMe drives, CPUs, and memory per tenant. Shimon assumed government would ask first. A GPU cloud did. - Why WEKA built its own hardware. After 13 years as a software-defined platform, WEKApod 3 delivers roughly 30% better efficiency than running on OEM servers. - The next three years. New models are cutting memory needs by up to 30x, but agentic workloads are generating up to 1,000x more tokens. The math doesn't work without fixing the data path. Full conversation: https://lnkd.in/djy7edWN #AIInfrastructure #Inference #AICloud #Kubernetes #AIInfraSummit
6 of 256 adsSign up to see every vCluster ad, filter by format and date, and get alerts on new ones.
See all 256 adsWatch the companies you care about.
Filter every ad by industry, country, format and network, and get alerts when a company you watch starts running new ads.