Not on air · 2 of 3 networks checked

Centaur.ai ads
- centaur.ai
- Software Development
- US
- 81 employees
Centaur.ai’s ads on LinkedIn, Meta and Google, recorded by adsrunning. Browse the latest here for free. Sign up free to see all 84. Watch Centaur.ai on any plan to get each new one in your feed.
Watchlist included in every plan
What Centaur.ai runs
- Single image · LinkedIn
- 6
- Google ads on 24 Oct 2026
- 8
| Network | Status | Live ads | Nov 2025LinkedIn activity · 52 weeksNov 2026 | Checked | Next step |
|---|---|---|---|---|---|
| None recorded | 0 | Checked 8 Nov 2026 | See all 84 ads → | ||
| Meta | Not checked | — | |||
| Recently | 8 | Ads on the Google Ads Transparency Center | Checked 24 Oct 2026 | Collect them with the API → |
Centaur.ai has no live LinkedIn ads. We recorded 8 Google ads on 24 Oct 2026.
Latest ads
- LINKEDIN · IMAGESince 29 Sept 2026
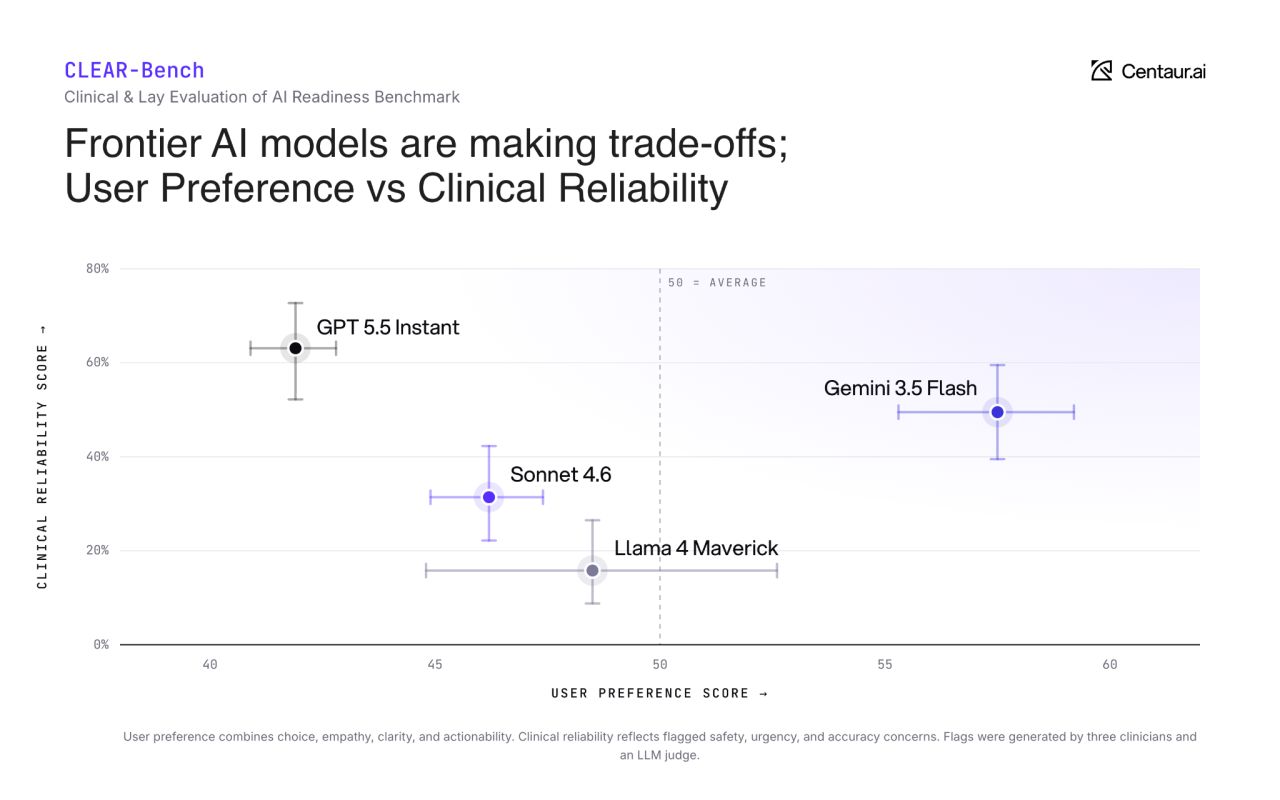
🚀 Introducing: Centaur’s CLEAR-Bench (Clinical & Lay Evaluation of AI Readiness)!! There’s a disconnect between what users prefer and what is safe and reliable. We’ve seen this movie before with tech built to maximize engagement. Especially in domains like health, technology shouldn’t just optimize for what users like most. If we only optimize for user preference, we'll build AI that's reassuring, agreeable, but sometimes dangerous. If we only optimize for complete risk elimination, we’ll build an overly sensitive model that users would find frustrating to engage with. So we built CLEAR-Bench. The key idea: evaluate models separately on what consumers value (empathy, helpfulness) and what clinicians require (safety, accuracy, urgency), then look at where they diverge. They diverge a lot. No model was best at both. The model (GPT 5.5 Instant) that drew the fewest clinical flags had the lowest consumer ratings, while the model (Gemini 3.5 Flash) that had the highest consumer ratings drew more clinical flags. The answer people prefer isn't necessarily the most clinically-sound. Consumer ratings don’t track clinical quality. How we did it: across model responses to health queries grounded in real-world usage, we collected multiple consumer, clinician, and LLM judgments across the dimensions that matter most. Consumers rewarded answers that felt warm and clear (and longer!). The LLM judge mostly flagged incorrect facts. Clinicians mostly flagged what was missing: the warning sign, the escalation, the follow-up question. That's why building health AI needs strategic human involvement and multi-dimensional evaluation. It's the Centaur approach: know where experts are essential, where everyday users are the right judges, and where to rely on models. Health AI evaluation needs to measure what matters, not just what people click. Identifying the tradeoffs and realities before and during deployment lets you see where and how to fill the gaps from a robust, grounded standpoint. Building in health? We'll run CLEAR-Bench on your model, be your continuous eval machine, and help bridge any gaps.
- LINKEDIN · IMAGESince 28 Sept 2026
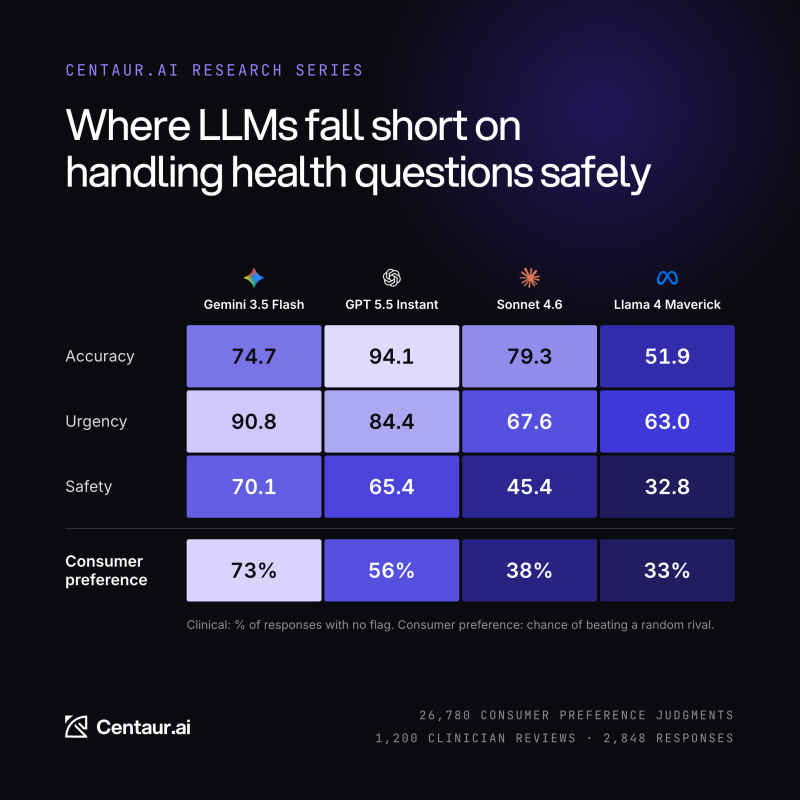
The most clinicially-sound model responses for consumer health questions aren't the ones ordinary people like the most. Gemini 3.5 Flash was the most preferred model at 73%, but it was not the strongest on clinical accuracy. The percentage of answers with no clinical inaccuracies was 74.7%, behind both GPT 5.5 Instant at 94.1% and Sonnet 4.6 at 79.3%. GPT 5.5 Instant had the fewest accuracy flags overall. Llama 4 Maverick 17B had the highest flag rate across accuracy, urgency, and safety. And the biggest gap came from how clinicians and an LLM judge reviewed the exact same responses. Clinicians flagged 155 answers for safety that the LLM judge didn’t, with many of their concerns centered on missing warning signs, weak escalation, or questions the model should have asked. The LLM judge, meanwhile, surfaced more factual accuracy issues. Same prompts. Same model responses. Very different picture depending on what you measure and who is doing the evaluation. Full results are live today: https://lnkd.in/efeSrCua
- LINKEDIN · IMAGESince 15 Sept 2026
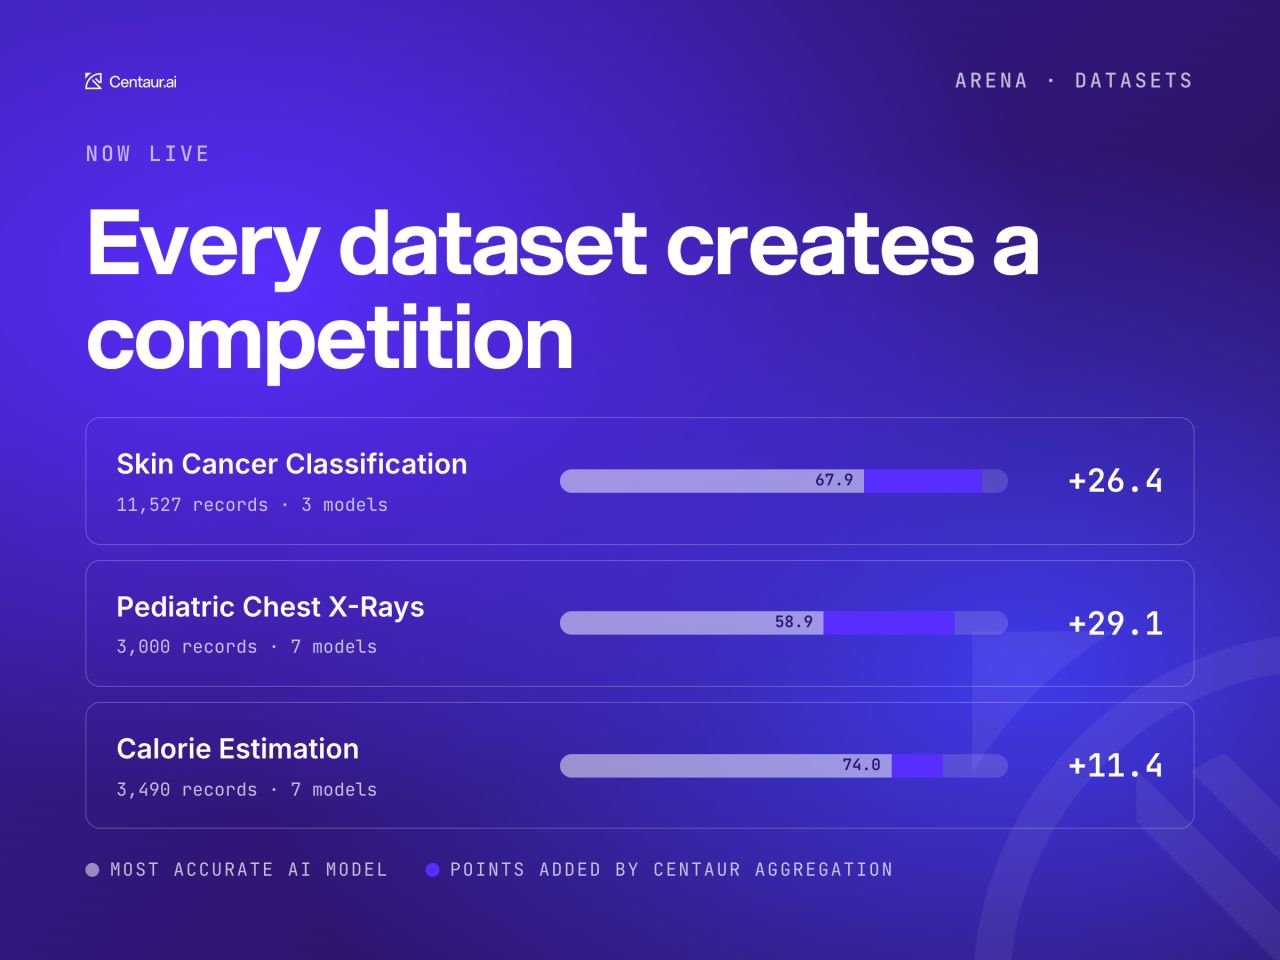
Three new datasets just landed in Centaur’s Arena: 🔬 Lymph node tissue slices 🩻 Pediatric chest X-rays 🧠 EEG recordings Across all three, Centaur’s human consensus outperformed every frontier model tested -- with gaps ranging from 7.8 to 35.1 percentage points. Take a look at the Arena and see how today’s leading models stack up against human expertise! Full story in the comments 👇
- LINKEDIN · IMAGESince 6 Nov 2025
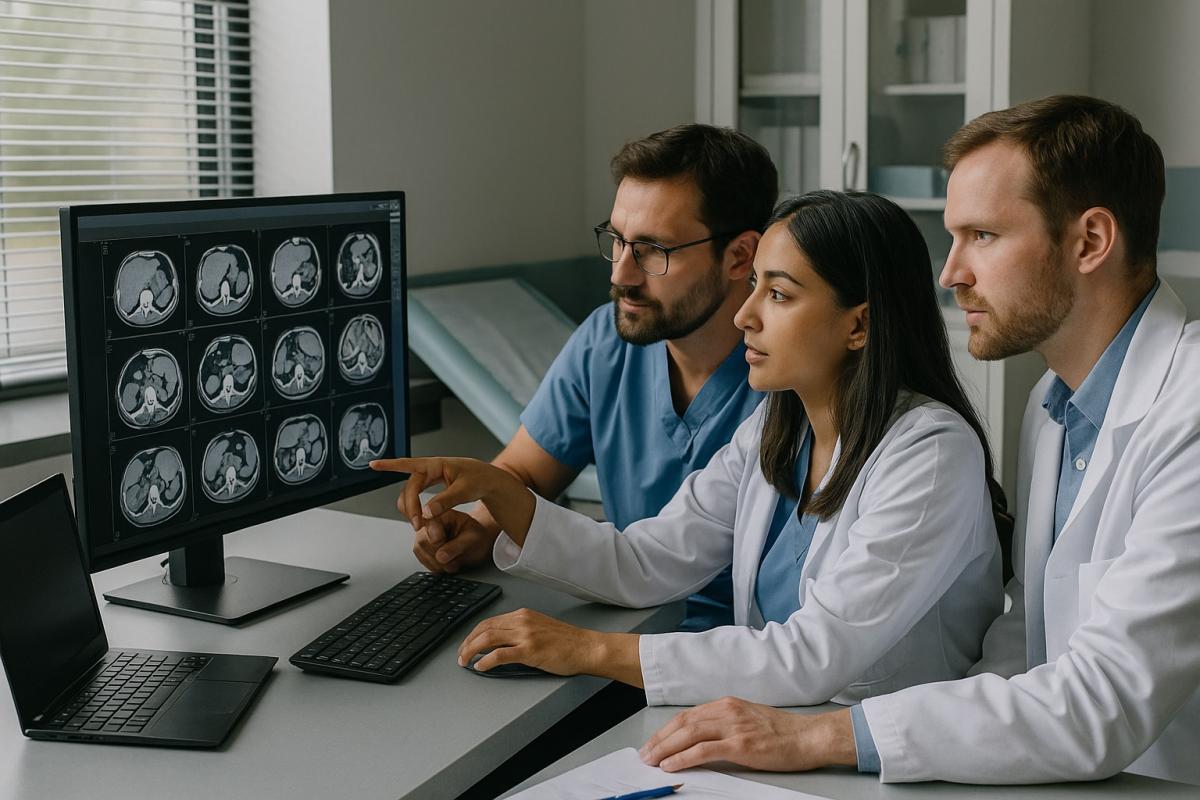
Radiology is a domain where the stakes of AI quality immediately impact patient outcomes. When quality matters this much, accuracy must be engineered. This is exactly why radiology is such a clear use case for collective intelligence annotation. https://lnkd.in/eRT7ez4H #RadiologyAI #MedicalImaging #LLMEvaluation #AIQuality #CollectiveIntelligence #DataAnnotation #ModelEvaluation #MedTech #DigitalPathology #HealthcareAI #CentaurAI
- LINKEDIN · IMAGESince 5 Nov 2025
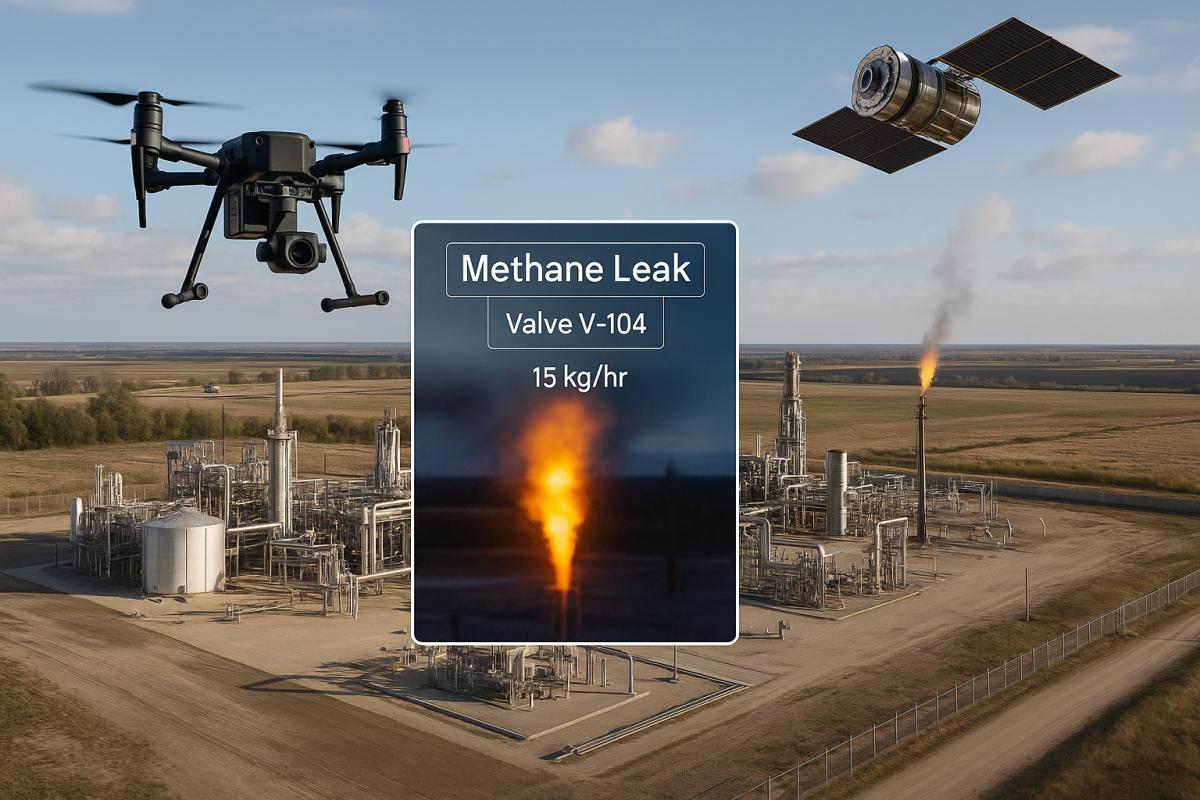
Drones and satellites can reveal hidden emissions, but the real breakthrough comes from expert annotation. High-quality labeled data transforms raw images into actionable intelligence—and trains the AI models that will scale this work. Centaur.ai delivers the accuracy-first, expert-validated annotation that ensures your data is trusted. https://lnkd.in/eZVrwjcg #AI #ClimateTech #DataAnnotation #LLM #ModelEvaluation #Sustainability #CentaurAI
- LINKEDIN · IMAGERecorded 12 Sept 2026
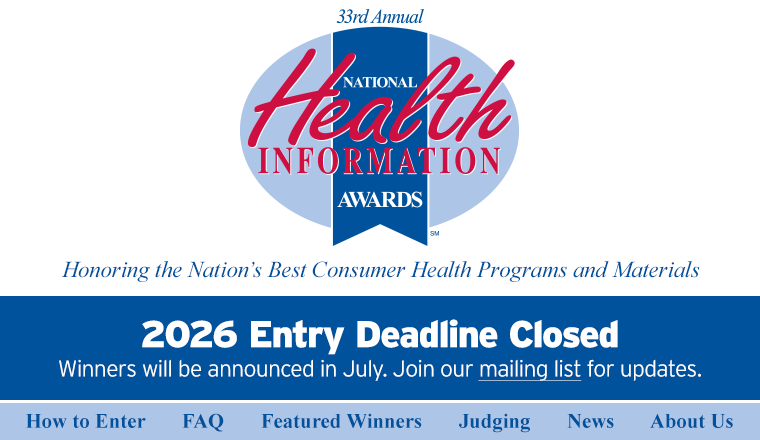
We’re thrilled to share that our mobile clinical-reasoning platform, DiagnosUs, has been awarded Gold by HealthAwards.com for Mobile Digital Health Resources. The award underscores what we’ve believed since our earliest research days: high-quality, expert-validated annotation is the foundation of trustworthy AI. https://lnkd.in/em3AFqA5 Thank you to all the clinicians, specialists, and contributors in our network whose expertise makes this possible. #HealthcareAI #DigitalHealth #DataAnnotation #MedAI #ClinicalAI #CentaurAI
6 of 84 adsSign up to see every Centaur.ai ad, filter by format and date, and get alerts on new ones.
See all 84 adsQuestions about Centaur.ai’s ads
Is Centaur.ai running LinkedIn ads?
We recorded no live LinkedIn ads for Centaur.ai on 10 Nov 2026.
How many LinkedIn ads has Centaur.ai run?
LinkedIn’s ad library lists 81 ads for Centaur.ai. We recorded 84 LinkedIn ads for Centaur.ai, first recorded on 12 Sept 2026 and last recorded on 8 Oct 2026.
Does Centaur.ai run Google ads?
Yes. We recorded 8 Google ads for the domain centaur.ai on 24 Oct 2026.
Which ad formats does Centaur.ai use?
The 6 LinkedIn ads on this page include 6 image ads.
Watch the companies you care about.
Filter every ad by industry, country, format and network, and get alerts when a company you watch starts running new ads.