Not on air · 3 of 3 networks checked
Akamas
- akamas.io
- Software Development
- IT
- 41 employees
Akamas’s ads on LinkedIn, Meta and Google, recorded by adsrunning. Browse the latest here for free. Sign up free to see all 340. Watch Akamas on any plan to get each new one in your feed.
Watchlist included in every plan
| Network | Status | Live ads | Nov 2025LinkedIn activity · 52 weeksNov 2026 | Checked | Next step |
|---|---|---|---|---|---|
| None recorded | 0 | Checked 3 Nov 2026 | See all 340 ads → | ||
| Meta | None recorded | 0 | No active ads recorded on the Meta Ad Library | Checked 16 Oct 2026 | Collect them with the API → |
| None recorded | 0 | No ads found on the Google Ads Transparency Center | Checked 31 Oct 2026 | Collect them with the API → |
Akamas has no live LinkedIn ads. Its Facebook page had no active ads on 16 Oct 2026, and we recorded no Google ads on 31 Oct 2026.
Latest ads
- LINKEDIN · CAROUSELSince 17 Jun 2026
Same infrastructure. 53% more AI throughput. Our study shows what optimal inference configuration actually unlocks at the GPU layer.
- LINKEDIN · CAROUSELSince 17 Jun 2026
40-60% of K8s spend is typically recoverable. See how much of yours is - in 90 seconds.
- LINKEDIN · CAROUSELSince 17 Jun 2026
Not what it bills. What it wastes. Calculate your annual overspend estimate, benchmarked against environments of your size.
- LINKEDIN · CAROUSELSince 17 Jun 2026
Most K8s environments have 8–15 workloads at risk from misconfigured resources. Get your estimate in 90 seconds.
- LINKEDIN · IMAGESince 26 May 2026
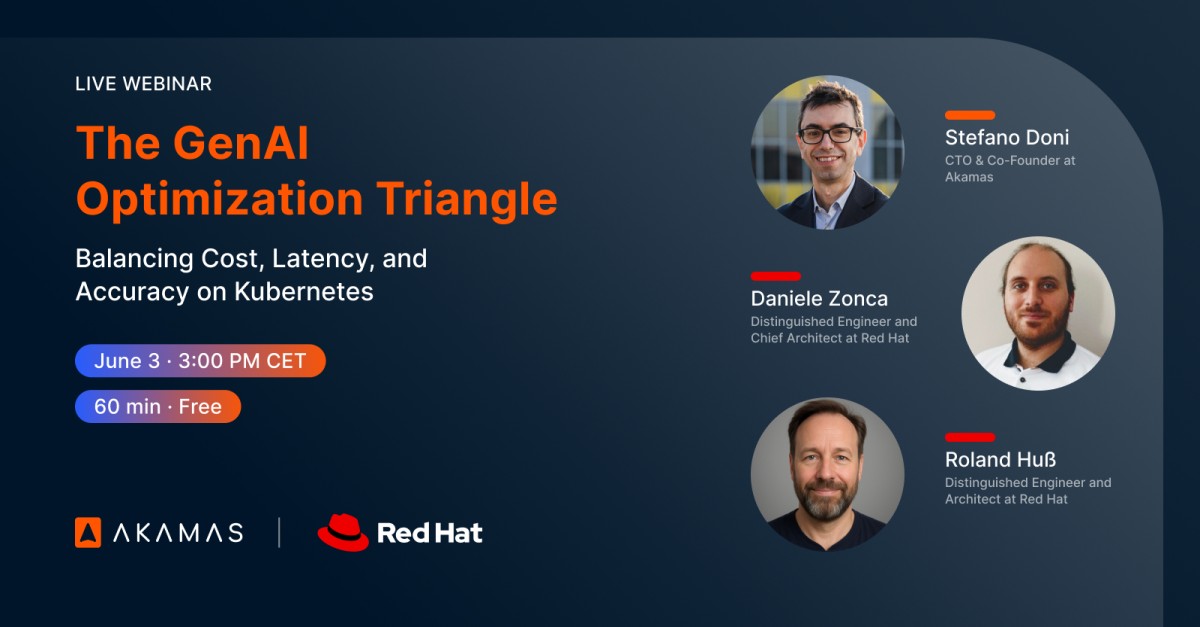
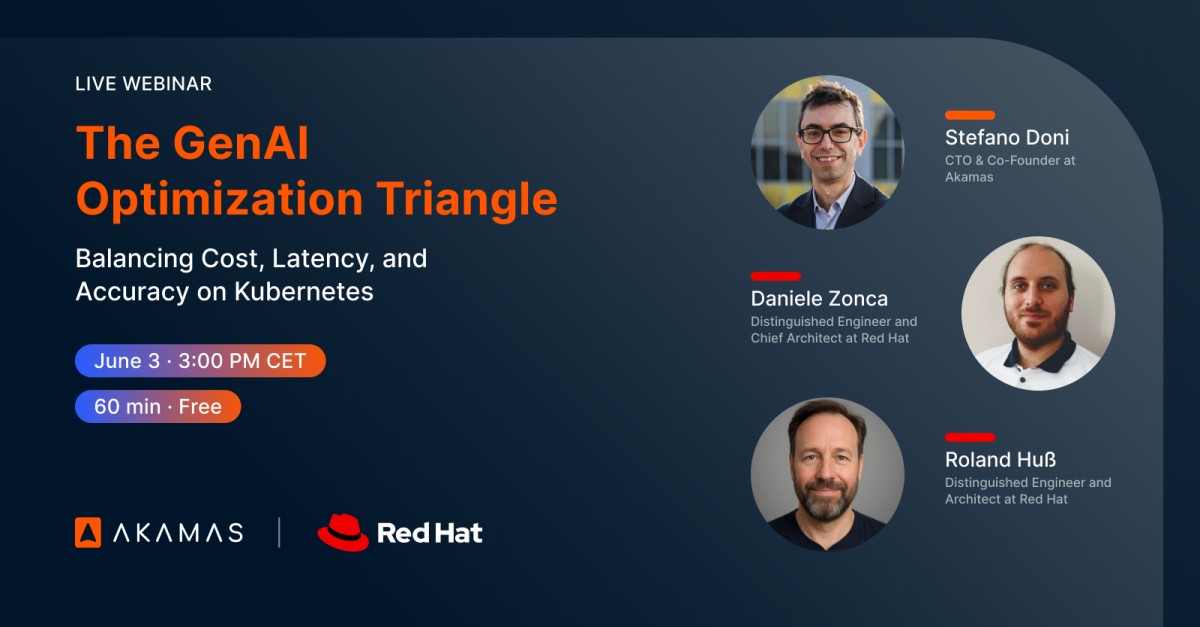
Free webinar on AI inference & GPU optimization on K8s - next week, June 3rd, 3PM CEST - 9AM EST! We're going to talk about how to make the most out of your existing GPUs and serve more users without spending more $$$. At the same time, optimizing inference performance is key to drive adoption of AI use cases - a slow or unreliable service means customer churn. Last but not least, accuracy: If your model (or agent) quality is not good, the overall value of your AI solution will be impacted. Optimizing AI workloads is not a walk in the park: it's a whole new performance engineering game in terms of complexity and skills. But if done right, the impact is huge. I'm super glad to discuss those topics with Daniele Zonca and Roland Huß, Distinguished Engineers from the Red Hat Openshift AI team. Daniele and Roland have a front seat in the development of llm-d, the new AI distributed serving stack for K8s, and they even wrote a book on these topics. Register here: https://lnkd.in/dMifd2yd #GenAI #K8s #GPU #PerformanceEngineering
- LINKEDIN · IMAGESince 18 May 2026
📅 Save the date: June 3, 15:00 CEST Red Hat and Akamas are teaming up for a 1-hour webinar on running GenAI workloads efficiently on #Kubernetes. We won't pitch products. We'll walk through the real optimization challenges: GPU infrastructure right-sizing, cost savings in inference serving, agent tracing, and the cost-latency-accuracy tradeoffs that make GenAI optimization unique. Save your seat 👇
6 of 340 adsSign up to see every Akamas ad, filter by format and date, and get alerts on new ones.
See all 340 adsWatch the companies you care about.
Filter every ad by industry, country, format and network, and get alerts when a company you watch starts running new ads.