On air · 1 of 3 networks
AIEEV
- aieev.com
- AI
- KR
- 10 employees
AIEEV’s ads on LinkedIn, Meta and Google, recorded by adsrunning. Browse the latest here for free. Sign up free to see all 44. Watch AIEEV with Starter to get each new one in your feed.
Watchlist with Starter · $49/mo
| Network | Status | Live ads | Nov 2025LinkedIn activity · 52 weeksOct 2026 | Checked | Next step |
|---|---|---|---|---|---|
| Running | 40 | Checked 30 Oct 2026 | See all 44 ads → | ||
| Meta | Not checked | — | |||
| Not checked | — |
AIEEV has 40 live LinkedIn ads.
Latest ads
- LINKEDIN · IMAGESince 19 Oct 2026
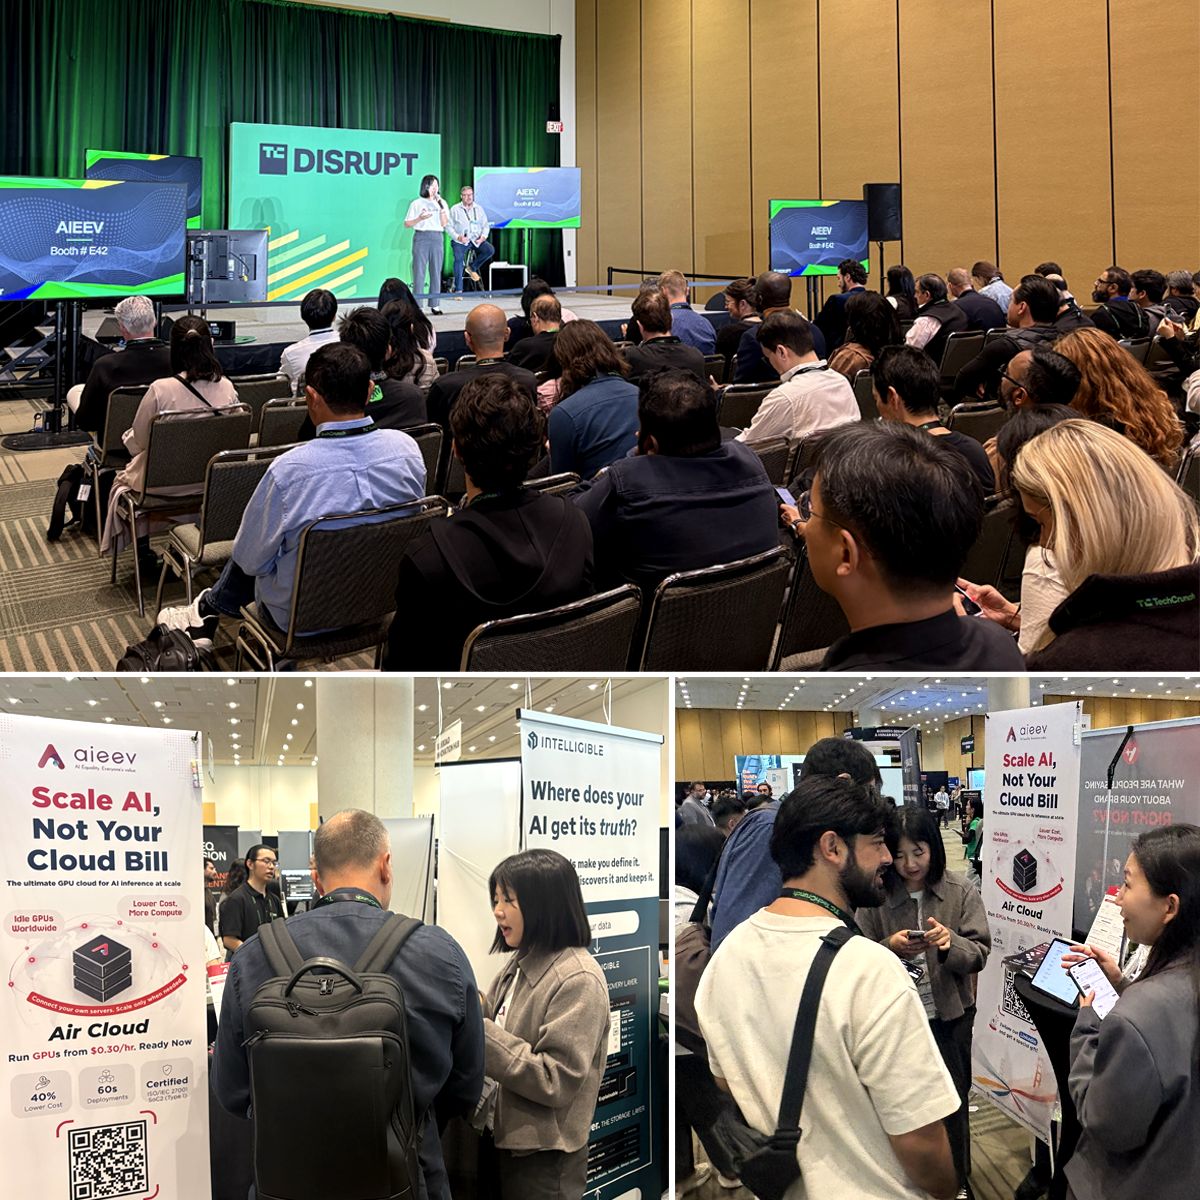
"What happens when our cloud credits run out?" At TechCrunch Disrupt 2026 last week, we met many AI teams already thinking about the problem we set out to solve. AIEEV joined the event as a Startup Battlefield 200 company. Co-Founder Karen Kim introduced Air Cloud on stage, and our team spent the rest of the week at booth E42, walking AI teams through live demos. Visitors picked a workload and a GPU, then compared the cost with what they run today. A few themes kept coming up: 1. Teams on cloud credits already planning what comes after 2. Small teams wanting to start with only the GPU they need 3. Public sector teams asking where their data is processed Air Cloud is our answer. It connects underused GPUs into a cloud where teams can deploy models and serve requests, without costs growing out of reach as usage scales. Every conversation at the booth helps us shape Air Cloud around what AI teams actually need. Thank you to everyone who stopped by and shared what you're building. We'd love to keep the conversation going. 📖 You can find the full story on our blog: https://lnkd.in/gSce98kP 🚀 Curious how Air Cloud would fit your setup? Try it here: https://www.aieev.com/ #TechCrunch #Disrupt2026 #StartupBattlefield200 #AIEEV
- LINKEDIN · IMAGESince 13 Oct 2026
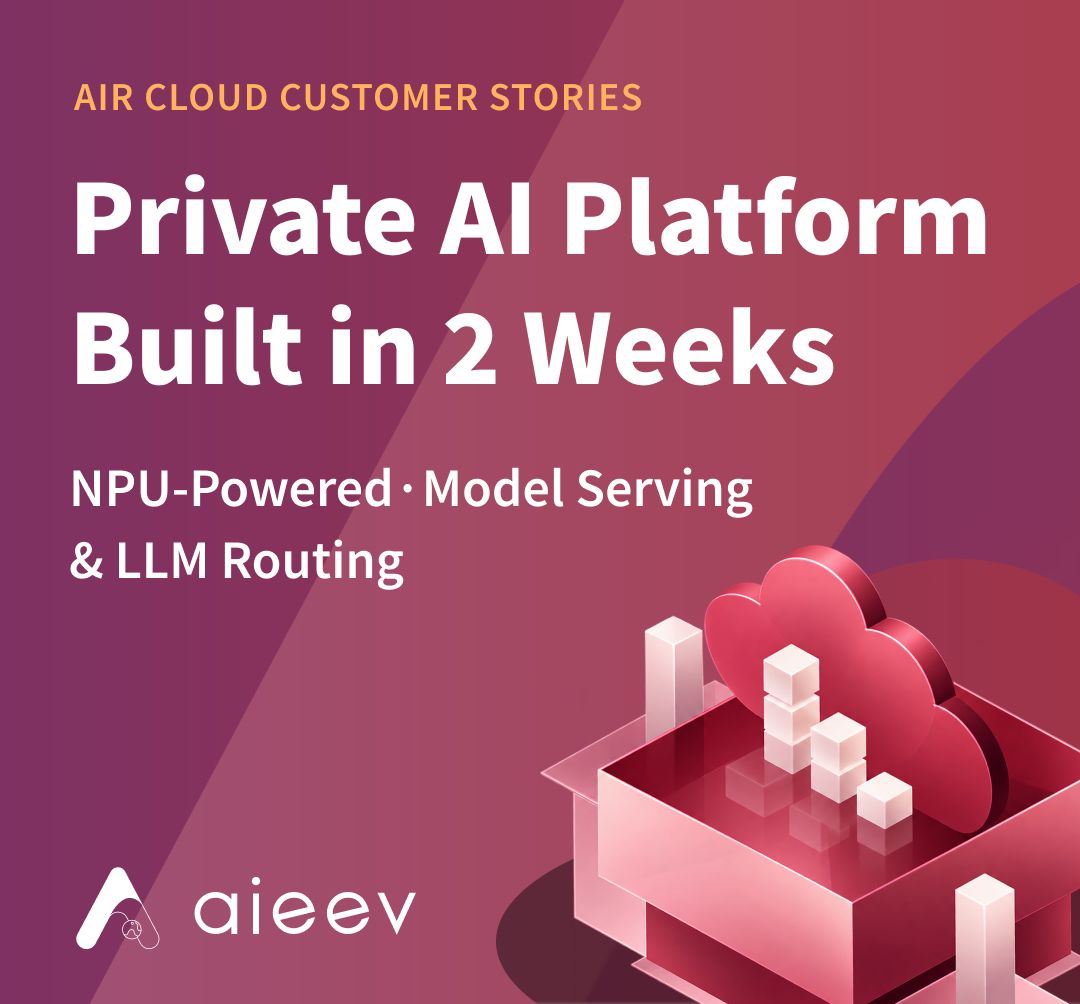
💡 2 weeks. That is all it takes to turn an enterprise NPU hardware infrastructure into a production ready private AI platform. When enterprise teams want to run AI models on their own infrastructure, the real challenge begins after model selection: making those models smoothly accessible to internal applications. Here is how AIEEV connected the NPU infrastructure of Company A, Korea’s largest AI contact center (AICC) platform provider, to their internal applications. 1. Deploying Private Air Cloud We set up Private Air Cloud directly on their NPU environment, establishing a secure private cloud foundation for their data and operations. 2. NPU Model Serving Configured a tailored model serving environment so internal tools could send requests and receive model responses seamlessly on NPU hardware. 3. Intelligent LLM Routing Connected internal application requests to multiple models via an LLM router, allowing developers to call and evaluate different models for features like document summarization. How the system works together: Internal App → LLM Router → Model Serving → Response Building a private AI environment around your existing GPU or NPU resources does not have to be complex. Planning to deploy AI models on your own hardware? Talk to AIEEV today. Read the full case study in the comments below!👇
- LINKEDIN · IMAGESince 12 Oct 2026
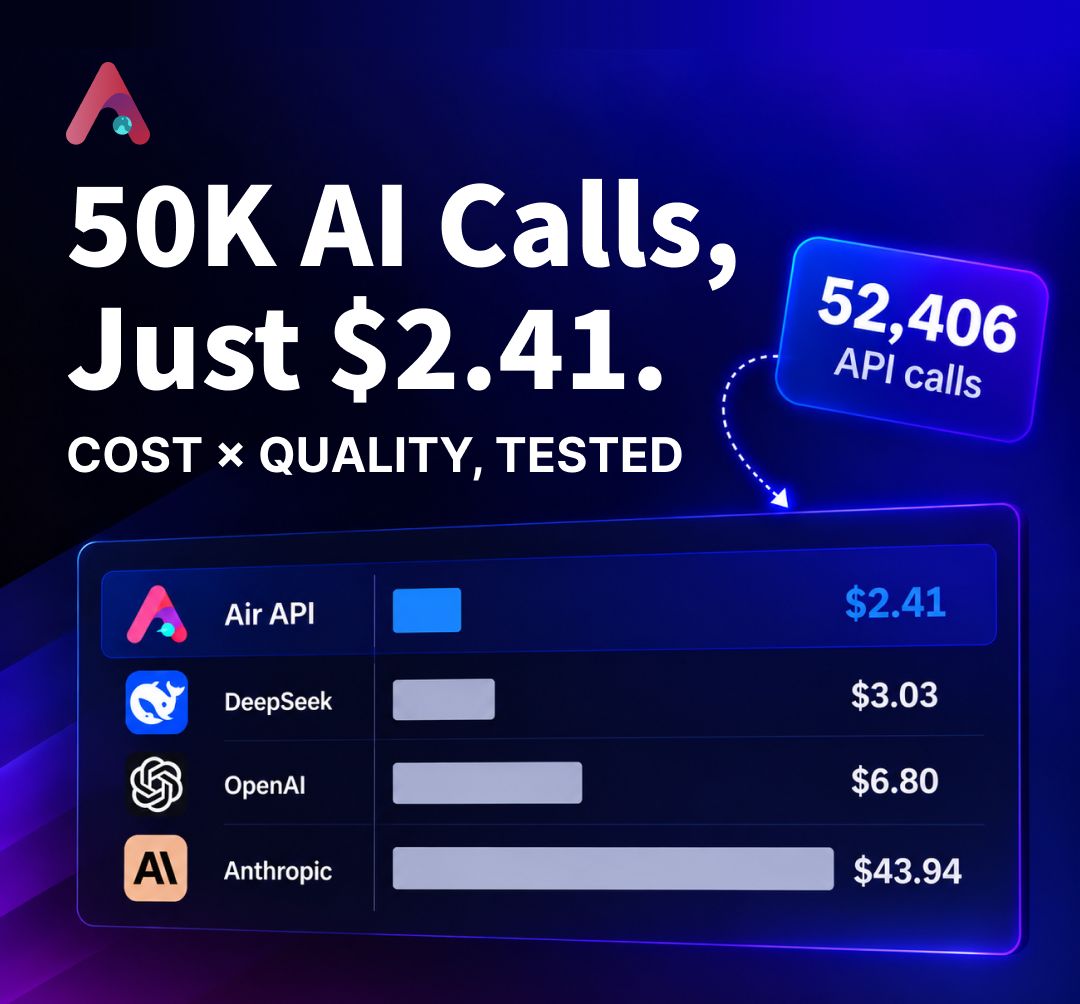
💰 We processed 52,406 API calls for $2.41. Here’s what we learned about AI cost structure. When building AI agents, model choice quickly stops being a matter of preference and becomes a core cost driver. To see what agent operations actually cost in practice, our marketing team built a research agent to process over 43,000 Hacker News posts on AI infrastructure. After running 50,000+ model calls, the entire bill came out to just $2.41. Here are 3 key takeaways from the experiment: 1️⃣ Cost is decided at the step with the highest volume Classification accounted for 83% of all API calls and half the total bill. If you want to cut costs, optimize the model behind your most frequent step rather than replacing the most expensive model in your stack. 2️⃣ One parameter tweak can beat switching models Turning off "thinking mode" for simple classification dropped average output tokens from thousands down to 21 per call—cutting token usage and output cost by an order of magnitude overnight. 3️⃣ Smart model matching delivers 16x savings with minimal accuracy loss Using a tiered stack (Qwen3.5-9B for classification and Qwen3.6-35B-A3B for extraction/summarization) cost 16x less than GPT-5 while outperforming lower-cost alternatives like GPT-5-Mini in classification accuracy. The goal isn't just to find the cheapest model—it’s matching the right model and settings to the difficulty of each task. How is your team optimizing API call costs and model pipelines for AI agents? We’d love to hear your approach! Read the full breakdown and prompt setups — link in the comments below!👇 #AIEEV #AirAPI #AIOps #LLM
- LINKEDIN · IMAGESince 7 Oct 2026
🇺🇸 Heading to San Francisco next week? Connect with AIEEV at TechCrunch Disrupt 2026! TechCrunch Disrupt 2026 is just around the corner! Selected as one of the Startup Battlefield 200 top early-stage startups from thousands of global applicants, AIEEV is heading to Moscone West from Oct 13–15. As AI agents become more sophisticated, the biggest engineering hurdle isn’t just building models—it’s sustaining the rapidly scaling costs and operational load of continuous inference, search, and tool-calling. That’s exactly where AirCloud comes in. Instead of waiting months on expensive new data center builds, AIEEV unifies distributed GPU resources into a seamless, enterprise-ready AI inference cloud. Backed by ISO/IEC 27001 certification, we are already powering AI cloud environments for 300+ organizations across the industry. Are you attending Disrupt 2026 or looking to optimize your enterprise AI inference costs? We’d love to meet you in person! 👉 Schedule a Meeting with Our Team: https://lnkd.in/gAZi38tJ See you in San Francisco! #TechCrunchDisrupt #StartupBattlefield200 #AIEEV
- LINKEDIN · VIDEORecorded 4 Sept 2026
🚀 What really happened at SK AI Summit 2025? Last week, AIEEV joined the AI Startup Zone at SK AI Summit — and something interesting happened. We met dozens of teams struggling with the same challenge: “How can we scale AI services without overspending?” Many were surprised to see how Air Cloud connects idle GPUs from consumers and enterprises to build a fully distributed inference cloud — no single data center, yet fully orchestrated and auto-scaling. If you’re curious about how that works in real service environments (and what kind of impact it can make), we’d love to share more — and yes, we’ve still got a few special gifts left for those who reach out. 🎁 Let’s talk. 👉 https://lnkd.in/gN4zpzy3 | DM us anytime #AIEEV #AirCloud #SKAISummit #AIInfrastructure #DistributedComputing #GPUpower #StartupZone - 🚀 SK AI 서밋 2025, 현장에서 들은 진짜 이야기 지난주 코엑스에서 열린 SK AI Summit 2025에 AI Startup으로 선정된 AIEEV도 함께했습니다. 행사에서 가장 많이 들은 질문은 단연 이거였어요. “데이터센터 없이도 AI 서비스를 확장할 수 있나요?” Air Cloud가 소비자와 기업의 유휴 GPU를 연결해 완전히 분산된 AI 인퍼런스 클라우드를 만든다는 사실에 많은 관계자분들이 관심을 가져주셨습니다. 특히 데이터센터 없이도 오케스트레이션과 오토 스케일링이 가능하다는 점이 특히 인상 깊었다는 피드백이 많았습니다. 혹시 Air Cloud가 실제 서비스에서 어떻게 작동하는지, 또 비용이나 속도 측면에서 어떤 차이가 있는지 궁금하시다면, 짧은 대화로 자세히 공유드릴게요. 이번 행사에서 준비했던 스페셜 기프트도 아직 조금 남아 있습니다 :) 👉 https://lnkd.in/gN4zpzy3 궁금하신 분들은 언제든 DM 주세요. #AIEEV #AirCloud #SKAISummit #AIStartupZone #분산형GPU클라우드 #AI인프라 #스타트업
- LINKEDIN · IMAGERecorded 4 Oct 2026
"Securing GPUs and making them usable for AI services are two completely different engineering challenges." Following Kitae Yoo’s presentation at KCD x Ceph x OpenInfra Day Korea 2026, the AIEEV Dev Team has published a new technical deep dive exploring why owned GPU/NPU hardware often sits idle—and how to turn scattered compute into production-ready inference capacity. In the field, developers often find GPUs in workstations, lab servers, or edge boxes. However, driver mismatches, missing SDKs, and network restrictions often prevent them from loading models when needed. Here is how AIEEV transforms fragmented compute resources into a unified execution pool for real world AI inference: 1️⃣ Verification Before Registration: Rather than adding devices immediately upon discovery, AIEEV's proprietary agent inspects the runtime environment and validates it against actual workloads. Only verified machines join the active serving pool. 2️⃣ Strategic Role Division (Kubernetes + Ray): We leverage Kubernetes for central control plane stability while orchestrating dynamic AI workload scaling across heterogeneous nodes using Ray Serve. 3️⃣ Solving Real World Production Bottlenecks: Operating across distributed, non-datacenter environments introduces challenges from power/cooling constraints to node-level fault tolerance. The post details how we overcome these operational bottlenecks in live production. How is your team handling GPU utilization and cold starts in distributed environments? We’d love to hear your thoughts and operational experiences. Read the full technical blog post — link in the comments below! 👇 #AIEEV #AIInfrastructure #GPU
6 of 44 adsSign up to see every AIEEV ad, filter by format and date, and get alerts on new ones.
See all 44 adsWatch the companies you care about.
Filter every ad by industry, country, format and network, and get alerts when a company you watch starts running new ads.