On air · 2 of 3 networks
Cast AI
- cast.ai
- Software (horizontal)
- US
- 360 employees
Cast AI’s ads on LinkedIn, Meta and Google, recorded by adsrunning. Browse the latest here for free. Sign up free to see all 555. Watch Cast AI with Starter to get each new one in your feed.
Watchlist with Starter · $49/mo
| Network | Status | Live ads | Nov 2025LinkedIn activity · 52 weeksOct 2026 | Checked | Next step |
|---|---|---|---|---|---|
| Running | 204 | Checked 30 Oct 2026 | See all 555 ads → | ||
| Meta | None recorded | 0 | No active ads recorded on the Meta Ad Library | Checked 18 Oct 2026 | Collect them with the API → |
| Running | 200+ | Ads on the Google Ads Transparency Center | Checked 24 Oct 2026 | Collect them with the API → |
Cast AI has 204 live LinkedIn ads. Its Facebook page had no active ads on 18 Oct 2026, and we recorded 200+ Google ads on 24 Oct 2026.
Latest ads
- LINKEDIN · IMAGESince 21 Aug 2026
Akamai runs infrastructure at a scale where a single percentage point is a budget line. Cast AI cut 40–70% of their cloud spend and returned engineering time alongside it. "An iPhone moment. Two minutes into the integration we saw the cost analytics, and I had an insight I had never had before." - Dekel Shavit, Sr Director of Engineering
- LINKEDIN · IMAGESince 21 Aug 2026
𝗔𝗟𝗟𝗘𝗡 𝗗𝗶𝗴𝗶𝘁𝗮𝗹 ran seven models on Amazon SageMaker - three open-source, four custom. • 𝗚𝗣𝗨 𝗶𝗻𝘀𝘁𝗮𝗻𝗰𝗲𝘀 sat underutilized while they paid for full capacity. • 𝗚𝗣𝗨 𝘁𝗶𝗺𝗲-𝘀𝗹𝗶𝗰𝗶𝗻𝗴 put multiple models on one instance. • 𝗟𝗮𝘁𝗲𝗻𝗰𝘆 matched or beat SageMaker. Cost fell more than 70%. • 𝗔𝗻 𝗶𝗱𝗹𝗲 𝗖𝗣𝗨 core costs cents an hour. An idle GPU costs dollars.
- LINKEDIN · IMAGESince 21 Aug 2026
Caudalie's team had already done the hard work. ARM on Graviton. 80% of production on Spot. The application tuned on both the code and resource sides. Cast AI still took 40% off their EC2 bill. Hand-tuning gets you to a good configuration once. Automation holds you at the best one as workloads change.
- LINKEDIN · IMAGESince 21 Aug 2026
Unstract put Kubernetes on 𝗮𝘂𝘁𝗼𝗽𝗶𝗹𝗼𝘁 and got 𝟴𝟬% 𝗼𝗳 𝗶𝘁𝘀 𝗗𝗲𝘃𝗢𝗽𝘀 𝘁𝗶𝗺𝗲 𝗯𝗮𝗰𝗸. - 𝗥𝗲𝗾𝘂𝗲𝘀𝘁𝘀 are now set from three days of real usage rather than a worst-case guess, with headroom left on the limit. - 𝗠𝗲𝗺𝗼𝗿𝘆 𝗮𝗹𝗲𝗿𝘁𝘀 moved from P0 to P1 because the agent resolves them before they turn critical. - 𝗠𝗼𝗻𝘁𝗵𝗹𝘆 team platform reviews instead of daily.
- LINKEDIN · IMAGESince 20 Aug 2026
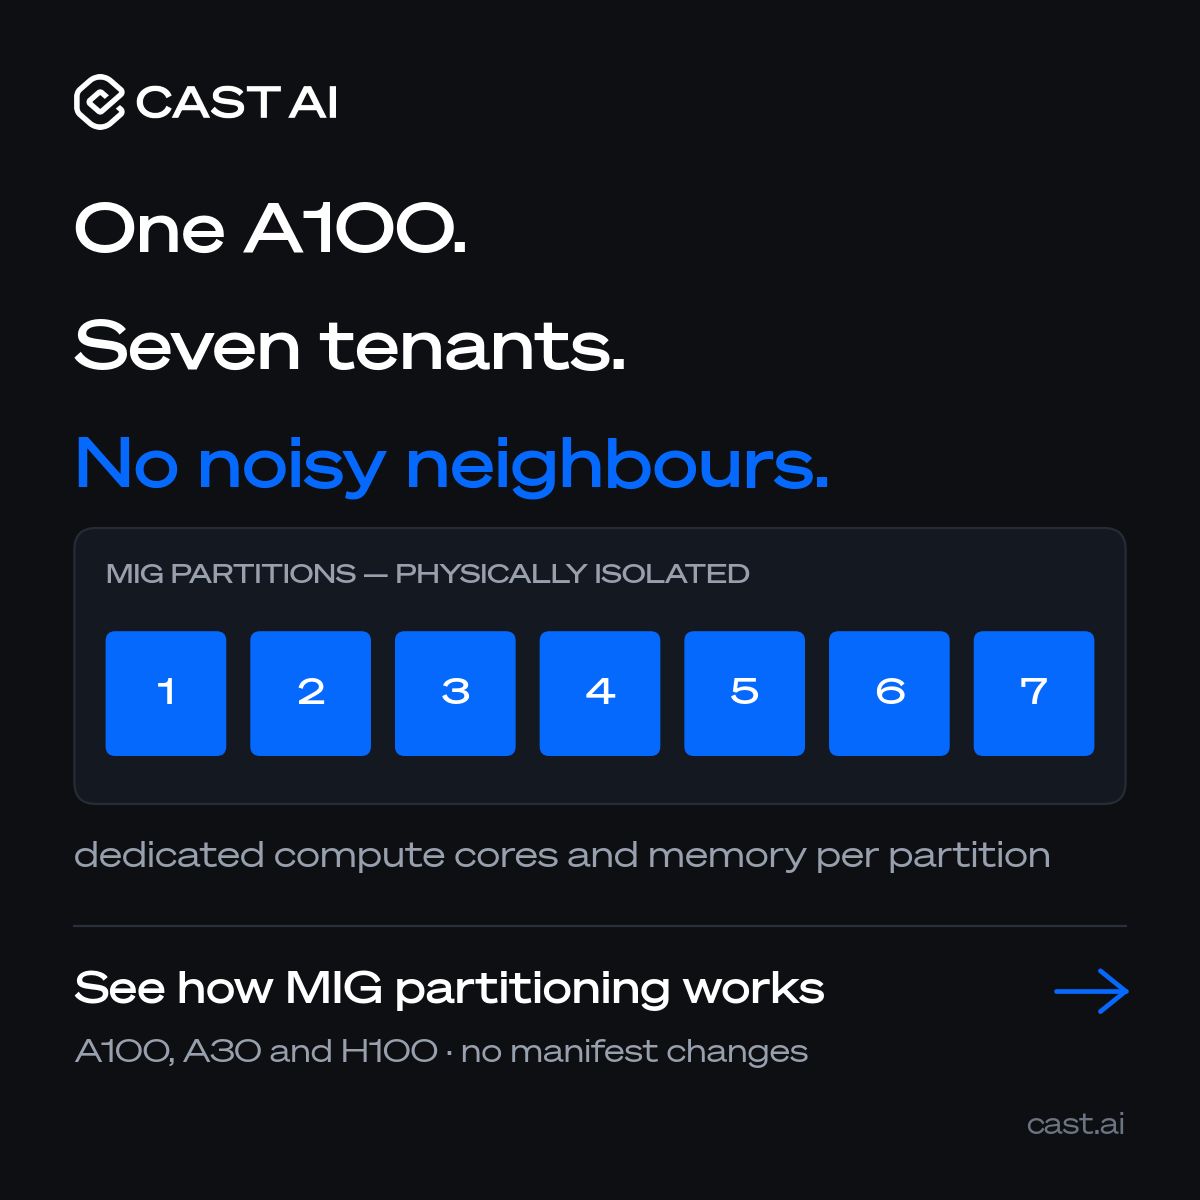
The usual objection to GPU sharing is isolation. Nobody wants an inference endpoint sharing silicon with a training job that spikes. MIG answers it in hardware. A100, A30 and H100 divide into physically isolated instances, each with dedicated compute cores and its own memory. No noisy neighbours, because there is no shared pool to be noisy in. Cast AI configures the partitioning and places workloads across it automatically, alongside time-slicing and MPS where those fit better.
- LINKEDIN · IMAGESince 20 Aug 2026
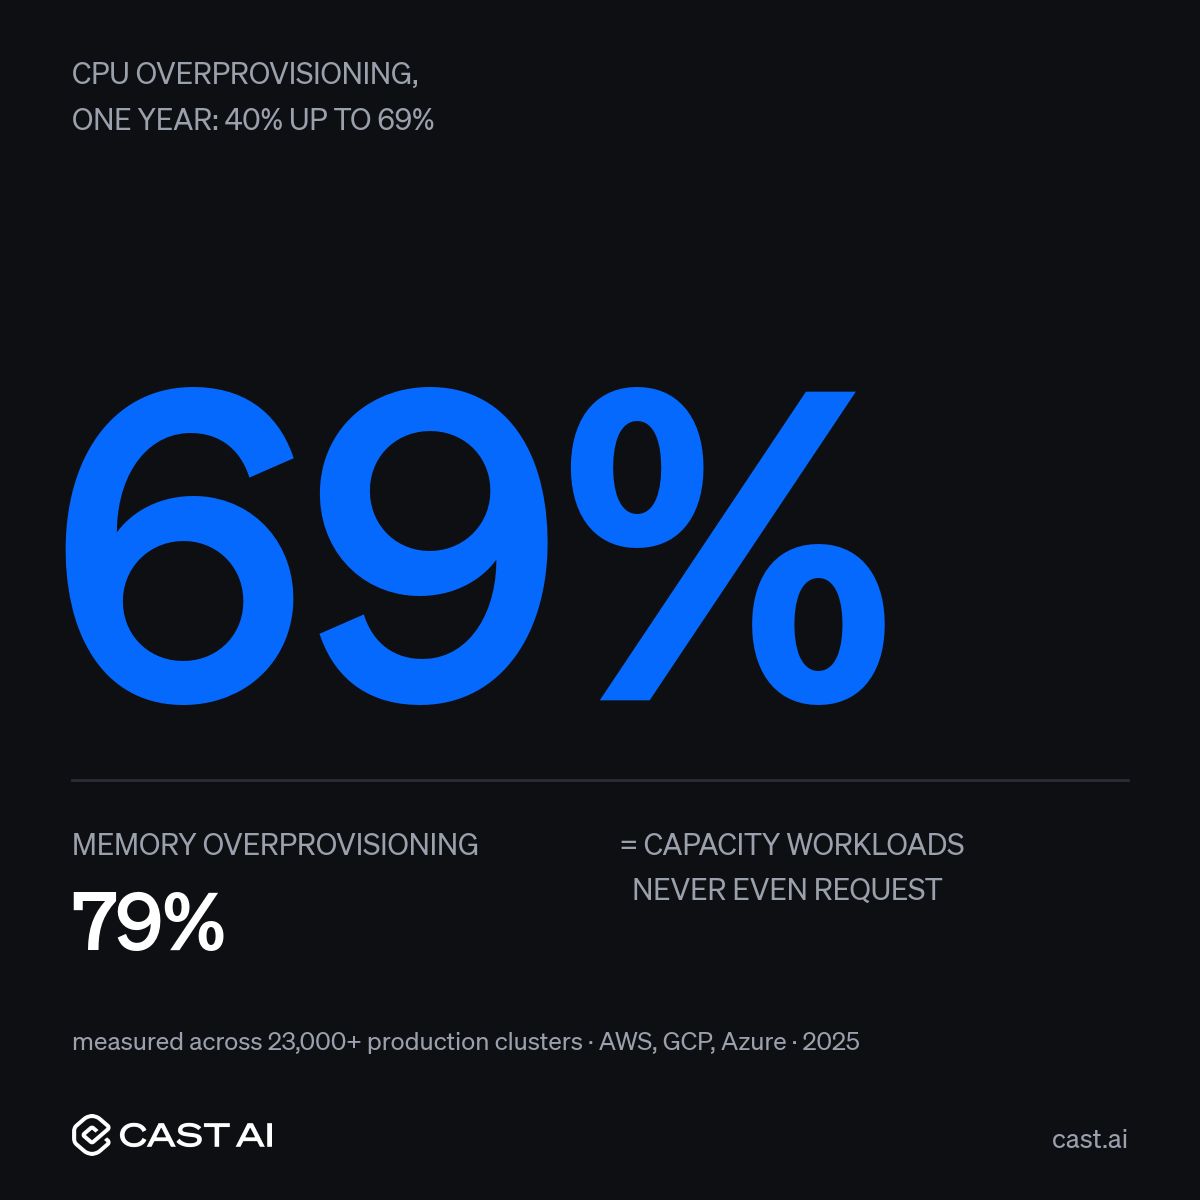
CPU overprovisioning went from 40% to 69% in a single year. Memory: 79%. Teams are paying for capacity their workloads never even request. We measured 23,000+ production K8s clusters for the 2026 State of Kubernetes Optimization Report - utilization benchmarks by cloud, Spot survival curves by region, and what the top teams do differently. Free download.
6 of 555 adsSign up to see every Cast AI ad, filter by format and date, and get alerts on new ones.
See all 555 adsWatch the companies you care about.
Filter every ad by industry, country, format and network, and get alerts when a company you watch starts running new ads.