On air · 2 of 3 networks
Forage AI
- forage.ai
- Data
- US
- 161 employees
Forage AI’s ads on LinkedIn, Meta and Google, recorded by adsrunning. Browse the latest here for free. Sign up free to see all 38. Watch Forage AI with Starter to get each new one in your feed.
Watchlist with Starter · $49/mo
| Network | Status | Live ads | Nov 2025LinkedIn activity · 52 weeksOct 2026 | Checked | Next step |
|---|---|---|---|---|---|
| Running | 38 | Checked 30 Oct 2026 | See all 38 ads → | ||
| Meta | None recorded | 0 | No active ads recorded on the Meta Ad Library | Checked 20 Oct 2026 | Collect them with the API → |
| Running | 3 | Ads on the Google Ads Transparency Center | Checked 29 Oct 2026 | Collect them with the API → |
Forage AI has 38 live LinkedIn ads. Its Facebook page had no active ads on 20 Oct 2026, and we recorded 3 Google ads on 29 Oct 2026.
Latest ads
- LINKEDIN · IMAGERecorded 19 Sept 2026
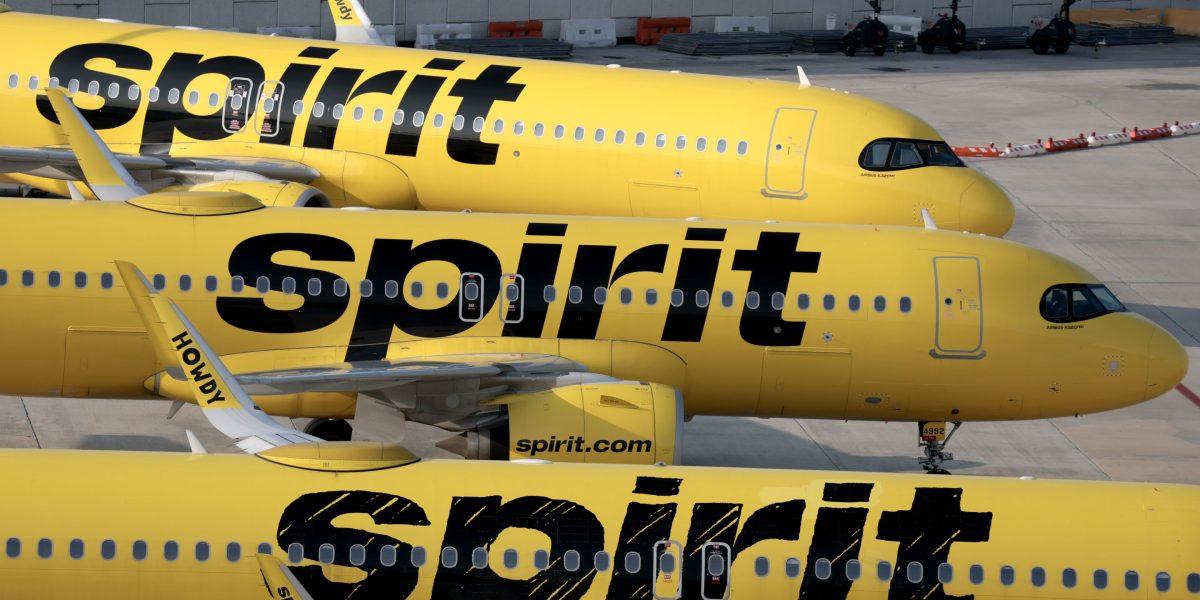
Is this the start of AI data wars? The Spirit Airlines story has been making the rounds for a while, but for those who don't yet know, Google bid $10 million for Spirit Airlines' internal data- a bankrupt airline's data. Another AI startup, Micro1, has topped it with a $12.5 million late bid. Mercor was already involved with a $7.5 million bid. What are they actually bidding for? 100 million emails, 500 million Teams messages, 30 million lines of production code, and deep records covering pricing, operations, and audits. All de-identified. This deal is shaping the future of the data industry in so many ways! 1) This isn't "content" in the traditional sense. They want to see how companies run. Three years ago, no one would have even called this training data. The big AI labs have already scraped the public web. Now they're hunting for the raw, messy reality of how a real company operates day to day. 2) Almost every mid-sized company is sitting on a similar data mine. What set Spirit apart was how it was packaged: de-identified, offered as one lot, something a buyer could actually walk away with. That's rarer than it sounds and quite valuable. I can see more AI labs going down this route - finding deeper, hidden, more valuable data that gives insights traditional web data cannot. In some ways, it's already happening. 3) We finally have a benchmark. Executives have spent years talking up the value of internal data without a number to back it up. Now there is: $10 million for an entire airline's operating history, with a competing bid of $12.5 million. This will also encourage people to look at data through a different lens. 4) A court-appointed ombudsman will oversee the de-identification before it gets the data. The flight attendants' union, AFA-CWA, has objected anyway, arguing the deal's privacy protections were built for passengers, not employees, and demanding flight attendant data be excluded entirely. This one is being watched closely, because it could set the precedent for how companies sell internal data to AI firms, and for what actually counts as adequate de-identification. The story isn't over yet. Court hearings are still pending; bankruptcy debtors are resisting Micro1's bid. However, the underlying point this deal reinforces is that if you want your models or AI products to pull ahead, you have to go deeper and source the hidden data others don't have access to. That doesn't mean you need to bid millions on a bankrupt company's servers; it means knowing exactly what you need and going after the long-tail 20% of data that's hard to get. https://lnkd.in/dcHbA_jC
- LINKEDIN · IMAGERecorded 19 Sept 2026
The scarce resource in AI isn't compute anymore. It's data worth training on. The free corpus is exhausted and the authoritative sources are closing fastest. The teams that win from here source deliberately. We acquire and verify that data. Talk to us.
- LINKEDIN · IMAGERecorded 19 Sept 2026
We'll be the first to say it: if you need one source scraped once, don't call us. But if you need many sources, refreshed on a cadence, delivered to a custom schema, and your best engineers free to build the actual product: · Your team stays on the model, not the pipeline · Acquisition runs on whatever cadence the product needs · One partner owns the whole stack, nothing to reconcile We acquire the data. You build the AI. Get in touch.
- LINKEDIN · IMAGERecorded 19 Sept 2026
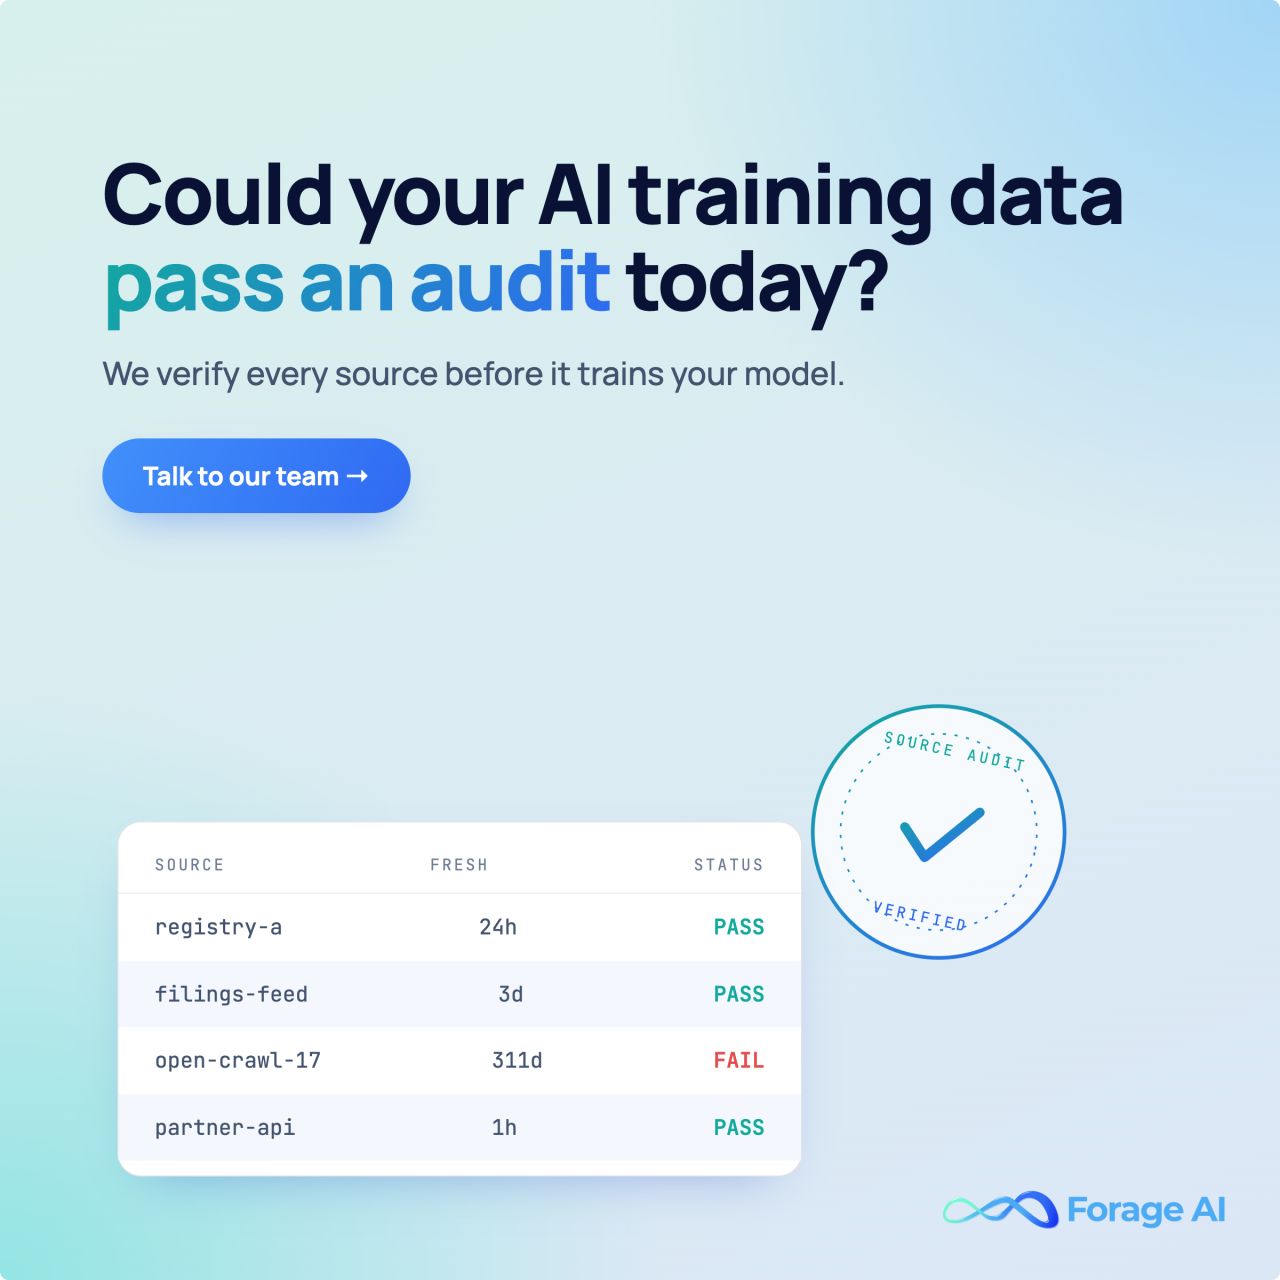
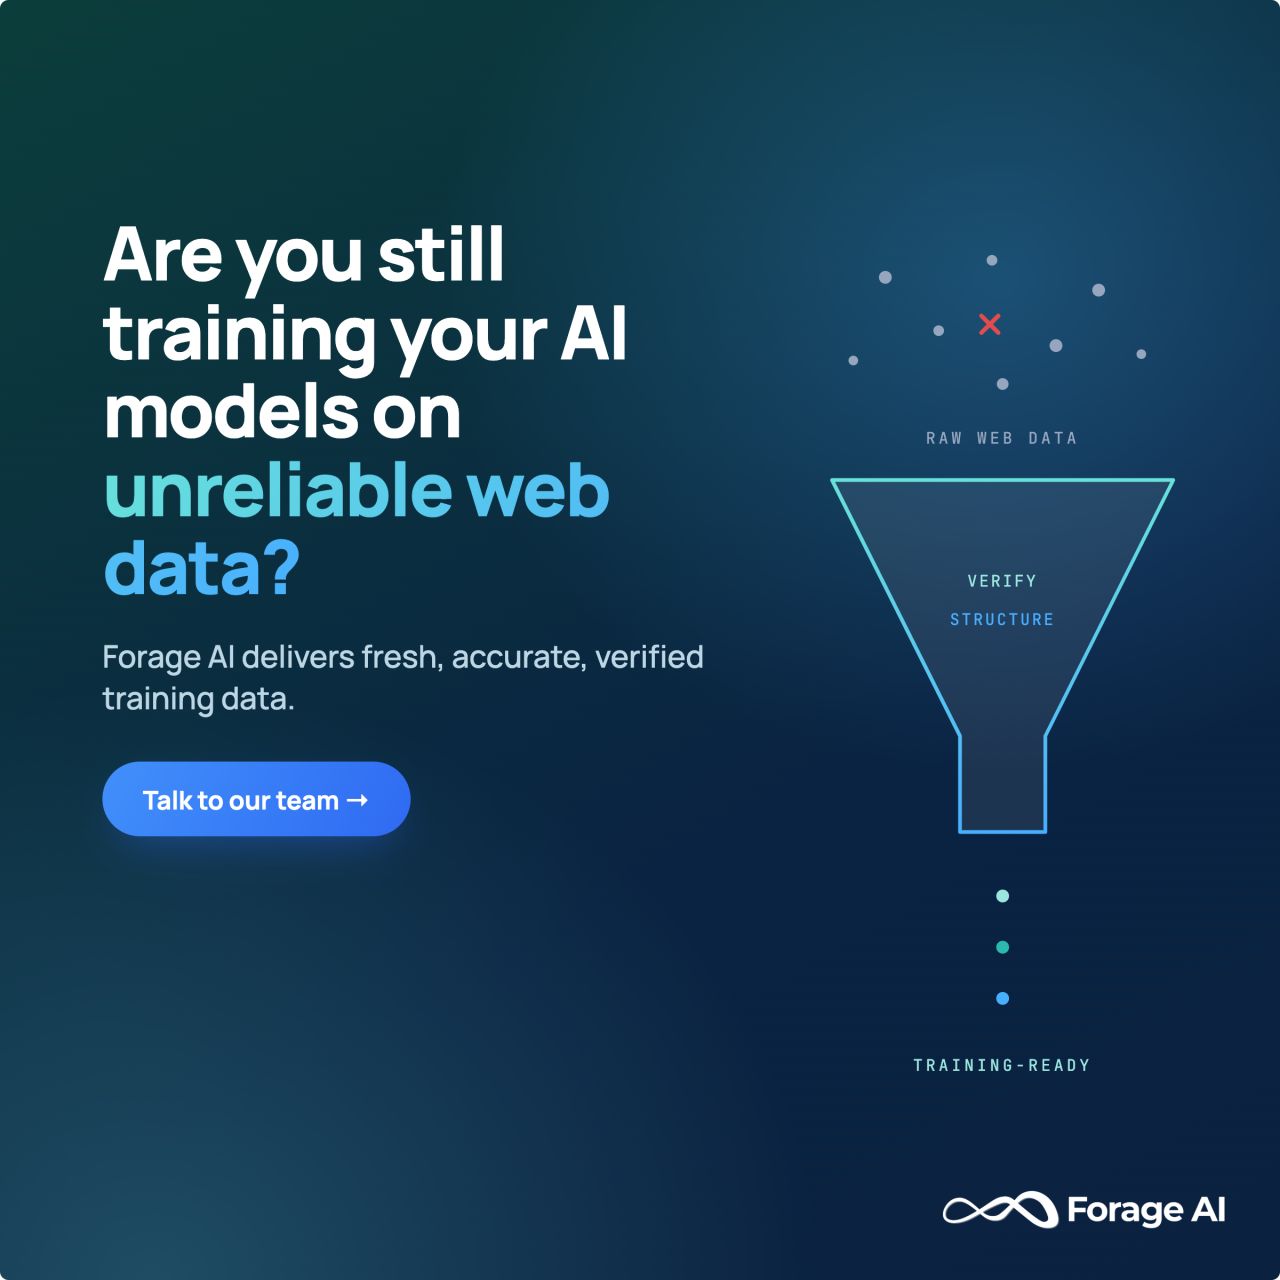
Which of your training sources would fail an audit today? Most teams can't answer. The cost lands later: a model that quietly underperforms in exactly the segments the bad source covered. We verify every source before it ships. Provenance tagged, field by field. Get a source-quality audit.
- LINKEDIN · IMAGERecorded 19 Sept 2026
80% to prepare the documents. 20% to build the system. That's how AI teams describe their own projects, and it matches what we see: · A corpus with 27 different PDF types, each breaking the parser a new way · Tables that lose their structure, entities split across line breaks · A quarter of 'AI work' that is actually document plumbing We take the 80%. Extraction, structuring, verification: your corpus arrives AI-ready, in your schema. Your team keeps the 20% they were hired for. Talk to us about your corpus.
- LINKEDIN · IMAGERecorded 19 Sept 2026
The team behind one of the best open web corpora reported something remarkable: the 10% of data they kept was 'actually worse than the 90% we removed.' That's the free corpus. It took 60,000+ GPU-hours just to validate one filtering pipeline, and the conclusion was that filtering barely helps. The implication for anyone building on web data: · Free and usable are different products · Cleaning at corpus scale is a research programme, not a preprocessing step · The differentiating data was never in the free crawl anyway We acquire, structure, and verify the data your model actually needs, from sources the crawlers don't reach. Talk to us about your corpus.
6 of 38 adsSign up to see every Forage AI ad, filter by format and date, and get alerts on new ones.
See all 38 adsWatch the companies you care about.
Filter every ad by industry, country, format and network, and get alerts when a company you watch starts running new ads.