On air · 2 of 3 networks
DataFlint
- dataflint.io
- Data
- 12 employees
DataFlint’s ads on LinkedIn, Meta and Google, recorded by adsrunning. Browse the latest here for free. Sign up free to see all 20. Watch DataFlint with Starter to get each new one in your feed.
Watchlist with Starter · $49/mo
| Network | Status | Live ads | Nov 2025LinkedIn activity · 52 weeksOct 2026 | Checked | Next step |
|---|---|---|---|---|---|
| Running | 2 | Checked 28 Oct 2026 | See all 20 ads → | ||
| Meta | Not checked | — | |||
| Running | 2 | Ads on the Google Ads Transparency Center | Checked 26 Oct 2026 | Collect them with the API → |
DataFlint has 2 live LinkedIn ads. We recorded 2 Google ads on 26 Oct 2026.
Latest ads
- LINKEDIN · VIDEOSince 8 Oct 2026
Your AI sees your code, not what actually ran. DataFlint Spark Copilot reads your real Spark runs. Setup is one URL. 👉 Try it yourself: https://www.dataflint.io/ #ApacheSpark #DataEngineering #AI
- LINKEDIN · IMAGESince 24 Sept 2026
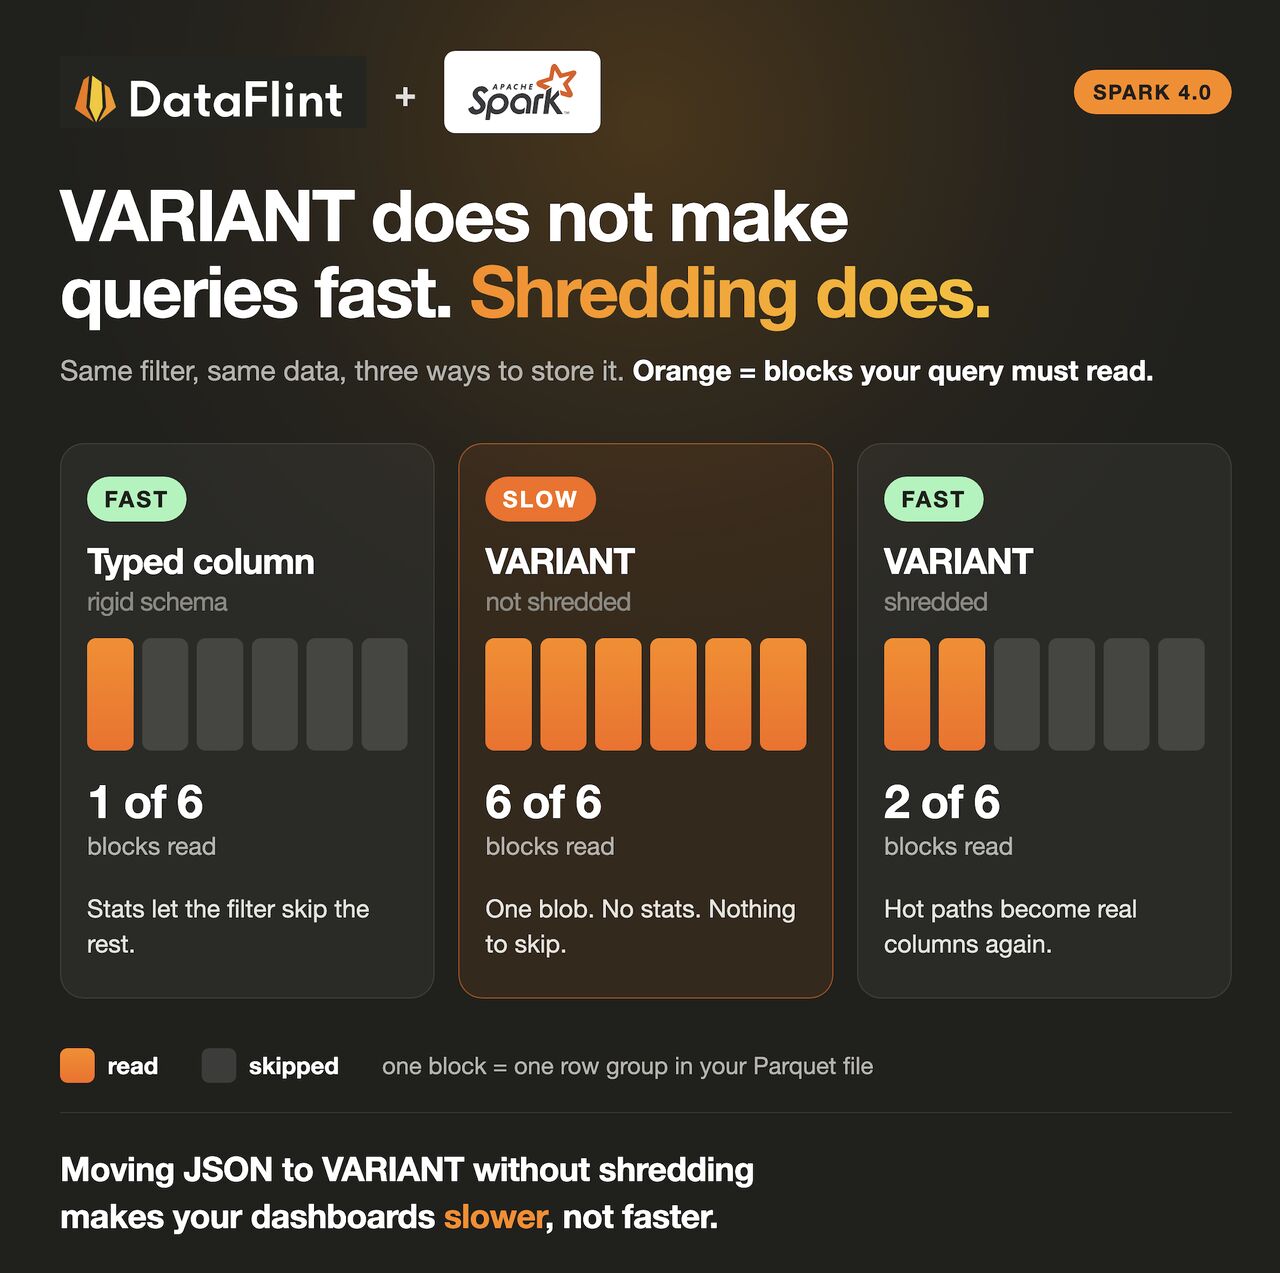
Apache Spark 4.0 gave you the VARIANT type. It will not make your queries faster. Shredding will. Every post about it says the same three things: no schema, no from_json, 8x faster. Teams are already planning to move their JSON columns over. VARIANT is stored as one binary blob inside Parquet. Parquet is fast for one reason. Every column keeps min and max values per row group, and a filter uses them to skip most of the file without opening it. A blob has no stats for the fields inside it, so your filter skips nothing. Every block gets read, then decoded. You stop paying to parse. You start paying to read. So what is shredding? At write time, Spark pulls chosen paths out of the blob and writes each one as its own typed column, next to the blob. user.id becomes a real BIGINT column with min and max stats. Whatever you did not choose stays in the binary leftover. That is how skipping comes back. The decision: ✅ Still on STRING plus from_json? Move to VARIANT. Clear win. ✅ Already have typed columns in your gold tables? Leave them alone. ✅ Putting VARIANT where people run queries? Shred it, then verify. If the value column still holds binary data for that field, it never got shredded and you are scanning blobs. VARIANT did not delete the cost of JSON. Shredding moves it out of your query path. #ApacheSpark #DataEngineering #Lakehouse
- LINKEDIN · EVENTSince 29 Jun 2026
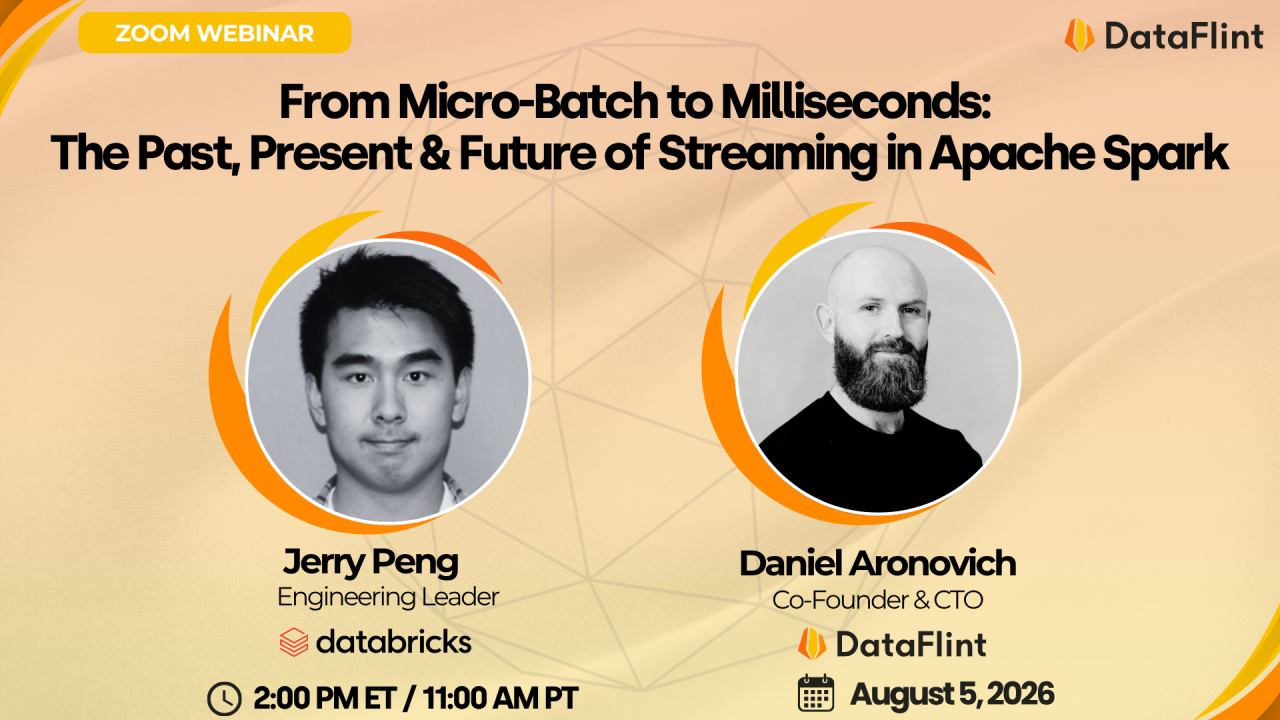
New Webinar alert: From Micro-Batch to Milliseconds! Spark streaming has come a long way, from micro-batch to near-real-time processing. Join us for a live deep dive into how it got here and where it's going next.
- LINKEDIN · IMAGESince 7 Jun 2026
Refresh the Spark UI, read the logs, guess what's slow, repeat. Sound familiar? There's a better way, and we'll prove it at booth #712. Bring your slowest job to Databricks Data+AI Summit. Any platform, any size. That one job nobody wants to touch, the one that's been "fine" for two years while quietly burning 40% more compute than it needs. We plug it into DataFlint live, you'll watch the bottleneck show up on screen, and you'll leave with a fix you can ship before you board your flight home. We've done this for 100+ jobs in 2026 and haven't missed yet. See you at the booth! #DataAISummit #ApacheSpark #Databricks #DataEngineering
- LINKEDIN · IMAGESince 17 May 2026
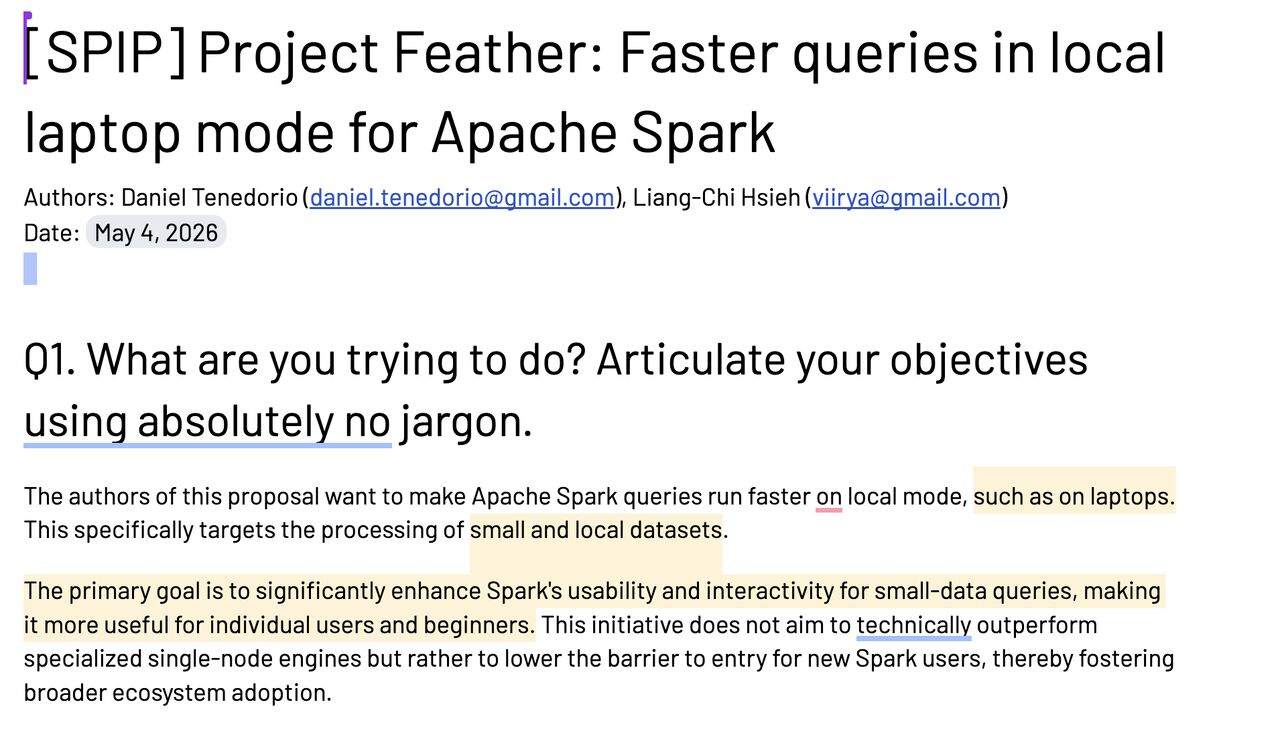
Your Apache Spark unit tests take 3 seconds each. Not because the logic is complex. Because Spark thinks it's on a cluster. A new SPIP (Spark project improvement proposal) called Project Feather targets this. Shout out to Daniel Tenedorio and Liang-Chi Hsieh. Every local test pays for distributed overhead you're not using. Shuffle writes to disk. Serialization between stages. Multi-partition planning for data that fits in memory ten times over. Three fixes: ✅ Smarter partitioning that skips unnecessary shuffles. Prototype: 330ms → 150ms. ✅ Arrow-based df.cache for faster iteration and smaller footprint. ✅ Shuffle-free local execution: in-memory channels, no disk, no serialization. This isn't about beating pandas. It's about making the Spark dev loop fast. 📖 Full SPIP: https://lnkd.in/e5rx_Yds #ApacheSpark #DataEngineering #OpenSource
- LINKEDIN · EVENTSince 23 Apr 2026
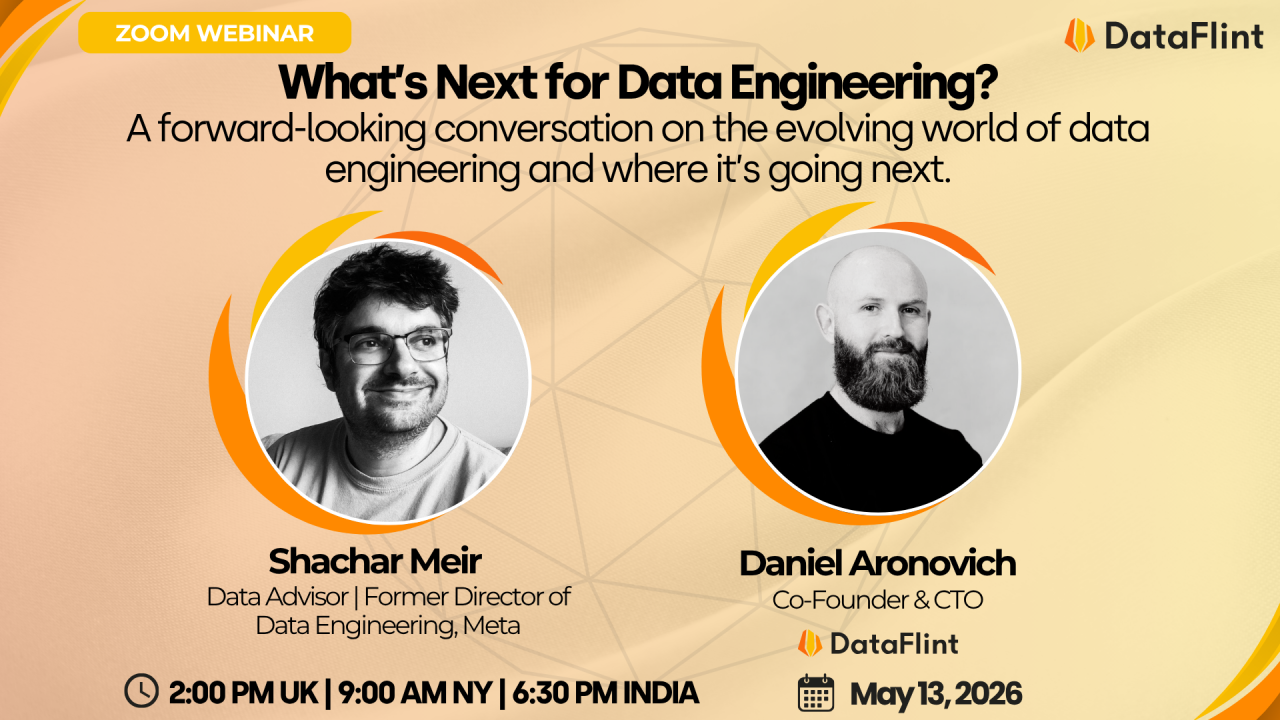
6 of 20 adsSign up to see every DataFlint ad, filter by format and date, and get alerts on new ones.
See all 20 adsWatch the companies you care about.
Filter every ad by industry, country, format and network, and get alerts when a company you watch starts running new ads.