On air · 1 of 3 networks
AutoMQ | Low Latency Diskless Kafka® on S3
- automq.com
- Data
- US
- 17 employees
AutoMQ | Low Latency Diskless Kafka® on S3’s ads on LinkedIn, Meta and Google, recorded by adsrunning. Browse the latest here for free. Sign up free to see all 23. Watch AutoMQ | Low Latency Diskless Kafka® on S3 with Starter to get each new one in your feed.
Watchlist with Starter · $49/mo
| Network | Status | Live ads | Nov 2025LinkedIn activity · 52 weeksOct 2026 | Checked | Next step |
|---|---|---|---|---|---|
| Running | 5 | Checked 30 Oct 2026 | See all 23 ads → | ||
| Meta | Not checked | — | |||
| Recently | 4 | Ads on the Google Ads Transparency Center | Checked 7 Oct 2026 | Collect them with the API → |
AutoMQ | Low Latency Diskless Kafka® on S3 has 5 live LinkedIn ads. We recorded 4 Google ads on 7 Oct 2026.
Latest ads
- LINKEDIN · IMAGESince 3 Sept 2026
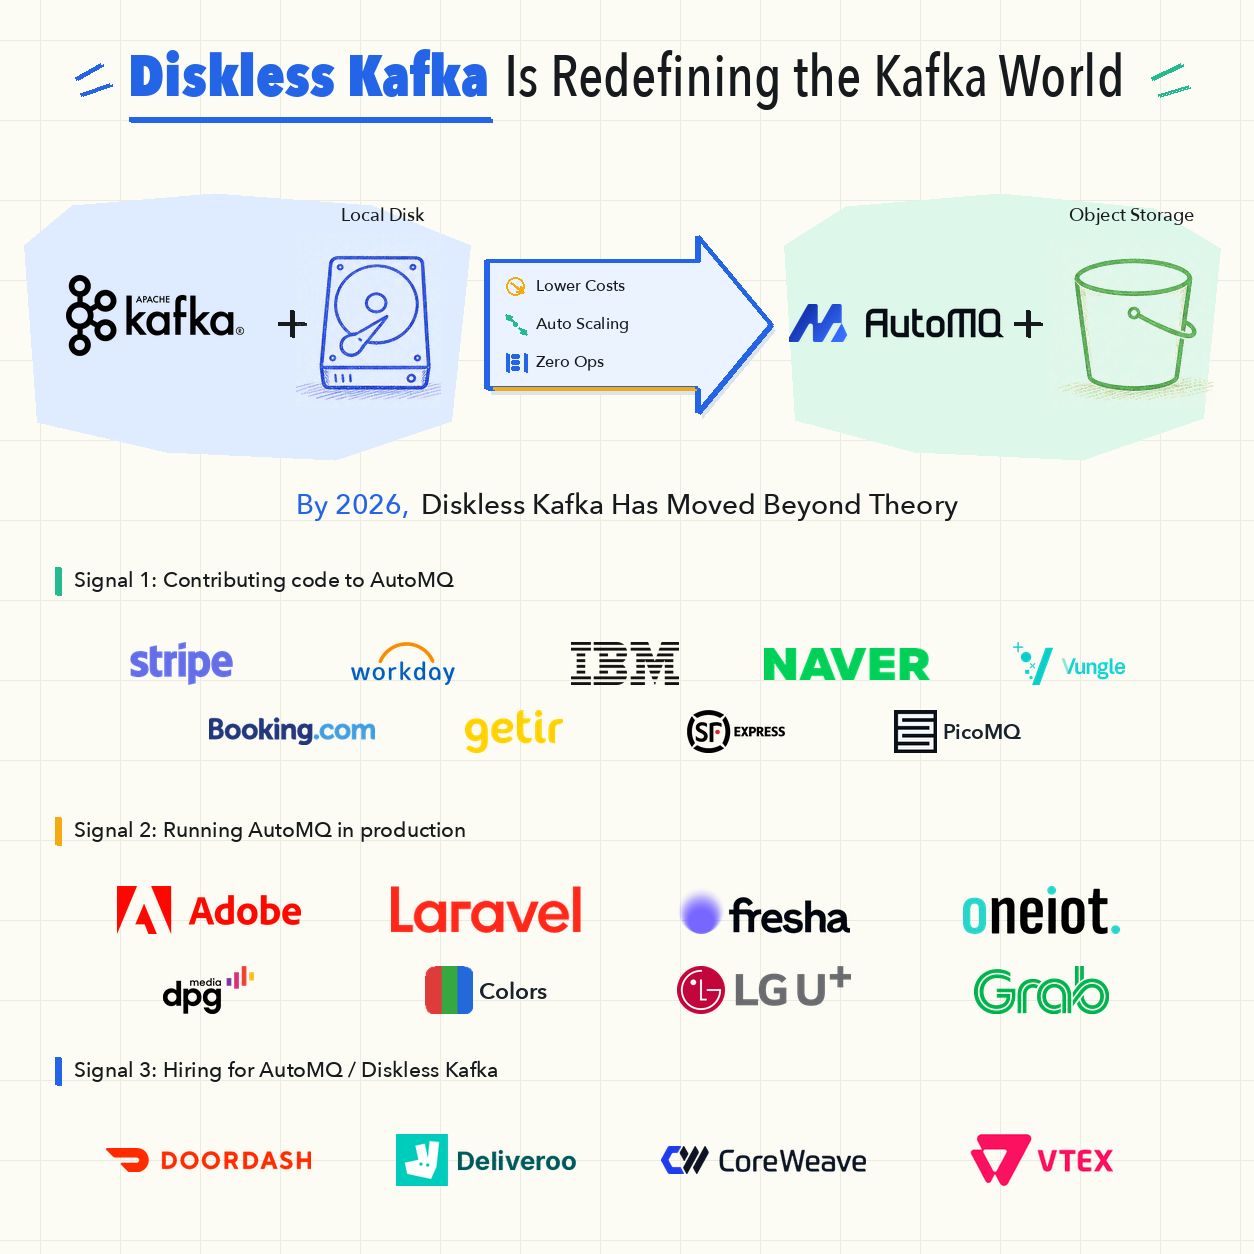
𝐃𝐢𝐬𝐤𝐥𝐞𝐬𝐬 𝐊𝐚𝐟𝐤𝐚 𝐈𝐬 𝐑𝐞𝐝𝐞𝐟𝐢𝐧𝐢𝐧𝐠 𝐭𝐡𝐞 𝐊𝐚𝐟𝐤𝐚 𝐖𝐨𝐫𝐥𝐝. By 2026, Diskless Kafka has moved beyond theory. Don't take my word for it. Check the comments for first-hand AutoMQ production stories, job posts naming AutoMQ, and open-source contributions to AutoMQ from engineers at leading companies. Traditional Kafka binds compute to broker-local disks. In the cloud, scaling means partition movement, overprovisioned storage, and stateful broker recovery. Diskless Kafka changes the model: object storage is the durable layer, and brokers provide stateless compute. AutoMQ preserves Kafka protocol compatibility, so clients and integrations keep working. Three public signals around AutoMQ stand out in 2026: open-source contributions, production and field adoption, and hiring demand. 𝐒𝐢𝐠𝐧𝐚𝐥 𝟏: 𝐎𝐩𝐞𝐧-𝐬𝐨𝐮𝐫𝐜𝐞 𝐜𝐨𝐧𝐭𝐫𝐢𝐛𝐮𝐭𝐢𝐨𝐧𝐬 (𝐂𝐨𝐦𝐦𝐞𝐧𝐭 𝟏) Engineers from 🇺🇸 Stripe, 🇺🇸 Workday, 🇺🇸 IBM, 🇰🇷 NAVER, 🇺🇸 Vungle, 🇳🇱 Booking.com, 🇹🇷 Getir, and 🇨🇳 SF Express have contributed code, issue reports, performance feedback, and design proposals to AutoMQ. Thank you for helping strengthen the project and the broader Diskless Kafka ecosystem. 𝐒𝐢𝐠𝐧𝐚𝐥 𝟐: 𝐏𝐫𝐨𝐝𝐮𝐜𝐭𝐢𝐨𝐧 𝐚𝐧𝐝 𝐟𝐢𝐞𝐥𝐝 𝐚𝐝𝐨𝐩𝐭𝐢𝐨𝐧 (𝐂𝐨𝐦𝐦𝐞𝐧𝐭 𝟐) 🇺🇸 𝐀𝐝𝐨𝐛𝐞: AutoMQ runs across 40+ services in an observability stack. Across the stack, the author reports cutting quarterly Datadog spend by roughly 70%. 🇰🇷 𝐋𝐆 𝐔+: 2.2 billion log messages per day through AutoMQ on AWS ECS. 🇸🇬 𝐆𝐫𝐚𝐛: Terabytes per hour, 3x throughput per CPU core, 3x cost efficiency, and partition reassignment reduced from up to six hours to under one minute. 🇺🇸 𝐋𝐚𝐫𝐚𝐯𝐞𝐥 𝐂𝐥𝐨𝐮𝐝: AutoMQ serves as the Kafka-compatible ingest layer for Grafana Mimir 3.0; metrics volume grew by roughly 10x. 🇬🇧 𝐅𝐫𝐞𝐬𝐡𝐚: About 150 Kafka Connectors migrated from Amazon MSK in days without downtime, with Kafka cost reduced by about 50%. 🇮🇳 𝐎𝐧𝐞𝐈𝐨𝐓: After one month in production, the author reports 62% lower infrastructure cost, roughly 25-second broker recovery, and scale-out from one to five brokers in under two minutes. 🇧🇪 𝐃𝐏𝐆 𝐌𝐞𝐝𝐢𝐚: A Strimzi, AutoMQ, and ClickHouse stack for media events, reported at about $750 per month before AWS discounts. 🇩🇪 𝐂𝐨𝐥𝐨𝐫𝐬: A three-node AutoMQ field deployment on Vultr and Cloudflare R2, refined through 23 convergence runs. 🇨🇦 𝐏𝐢𝐜𝐨𝐌𝐐: A new Durable Streams product whose Rust S3Stream engine is derived from AutoMQ S3Stream. 𝐒𝐢𝐠𝐧𝐚𝐥 𝟑: 𝐇𝐢𝐫𝐢𝐧𝐠 𝐝𝐞𝐦𝐚𝐧𝐝 (𝐂𝐨𝐦𝐦𝐞𝐧𝐭 𝟑) AutoMQ appears by name in public recruiting materials from 🇺🇸 DoorDash, 🇬🇧 Deliveroo, 🇺🇸 CoreWeave, and 🇬🇧 VTEX. • AutoMQ is open source with 10,000+ GitHub stars: https://lnkd.in/gZ96Ze7J • Start your 30-day AutoMQ Cloud free trial on the official website: https://lnkd.in/d6kwJEKu
- LINKEDIN · IMAGESince 3 Sept 2026
New blog 🎉 Another chapter in our AutoMQ journey at Fresha from Nicoleta Lazar This time: migrating our outbox Kafka cluster from AWS MSK to AutoMQ | Low Latency Diskless Kafka® on S3. The tricky part wasn’t moving Kafka itself, but doing it without losing events or forcing a big-bang consumer cutover. The answer was a mix of dual writes, replay, and Inbox deduplication. No Kafka Linking this time as the target topics were populated independently and wire format was changed as well. This post covers the migration design, rollback safety, and how we moved application events to diskless Kafka on S3. 🌊 ⚙️ 📕 Read: https://lnkd.in/ePVD5dYv 💬 Comments welcome #ApacheKafka #AutoMQ #Fresha #DisklessKafka #AWS #MSK #DataEngineering #OutboxPattern
- LINKEDIN · IMAGESince 19 Aug 2026
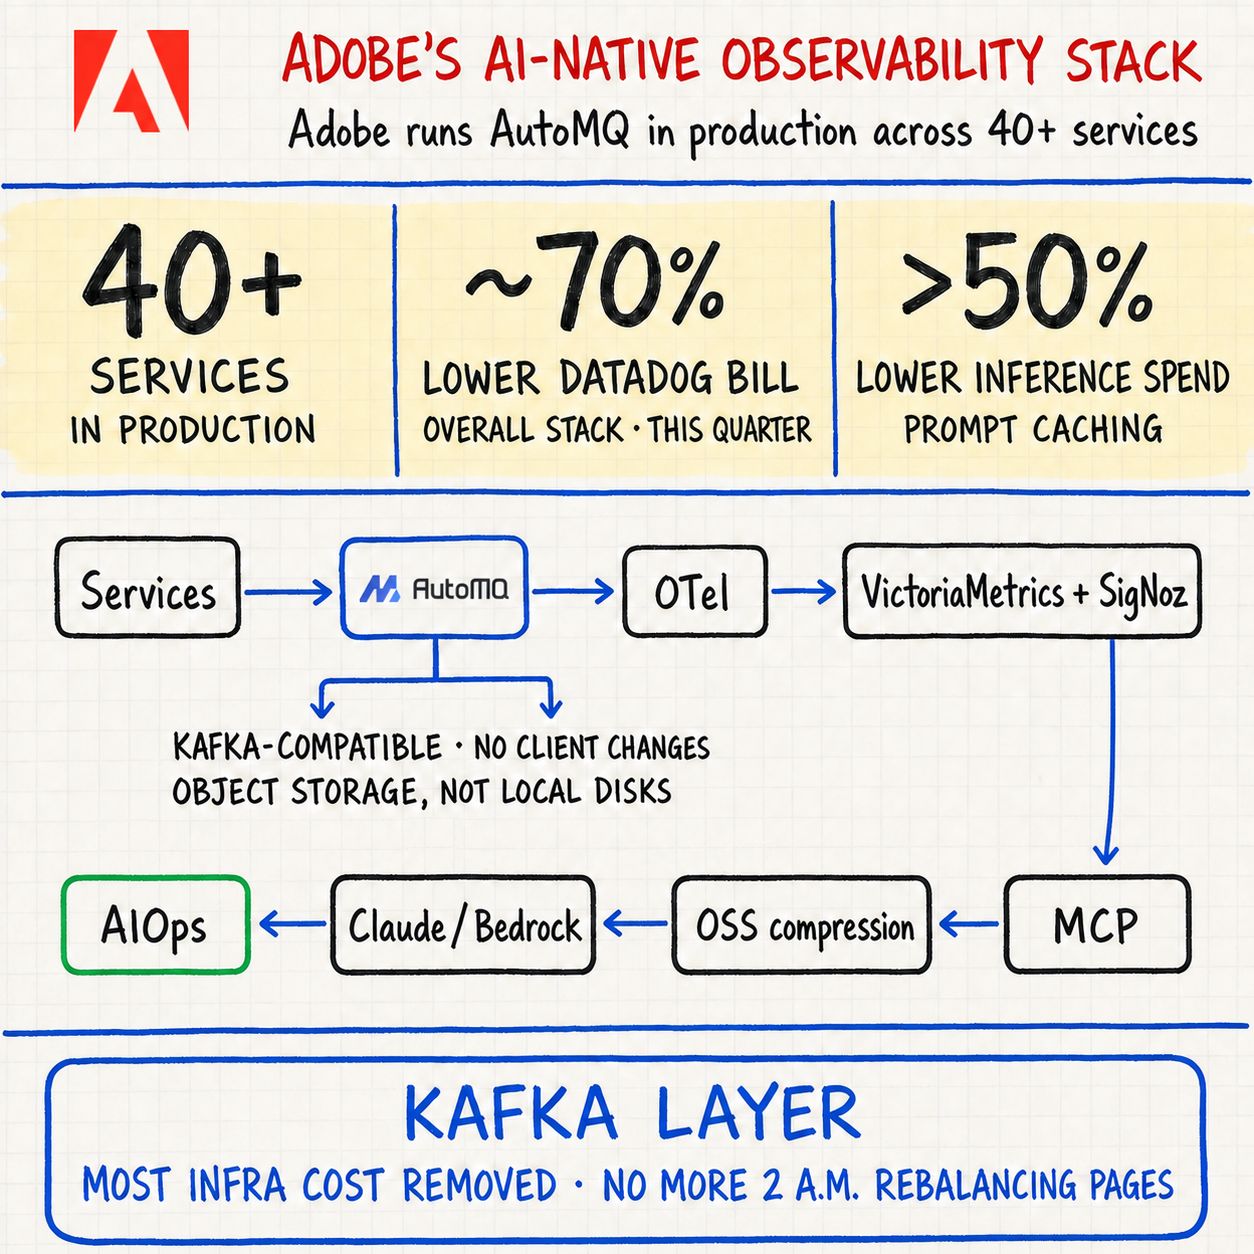
𝗔𝗱𝗼𝗯𝗲 is running AutoMQ in production across 𝟰𝟬+ 𝘀𝗲𝗿𝘃𝗶𝗰𝗲𝘀 in place of vanilla Kafka. Pranshu Jain at Adobe just shared this production data point. What stood out to me is how focused the change was: existing Kafka clients stayed untouched, while Kafka data moved from broker-local disks to object storage. According to Pranshu, that removed most of the infrastructure cost around the Kafka layer, along with the 2 a.m. rebalancing pages. The broader architecture is equally interesting: 𝘈𝘶𝘵𝘰𝘔𝘘 → 𝘖𝘱𝘦𝘯𝘛𝘦𝘭𝘦𝘮𝘦𝘵𝘳𝘺 → 𝘝𝘪𝘤𝘵𝘰𝘳𝘪𝘢𝘔𝘦𝘵𝘳𝘪𝘤𝘴 + 𝘚𝘪𝘨𝘕𝘰𝘻 → 𝘔𝘊𝘗 → 𝘰𝘱𝘦𝘯 𝘴𝘰𝘶𝘳𝘤𝘦 𝘤𝘰𝘮𝘱𝘳𝘦𝘴𝘴𝘪𝘰𝘯 → 𝘊𝘭𝘢𝘶𝘥𝘦 𝘰𝘯 𝘈𝘮𝘢𝘻𝘰𝘯 𝘉𝘦𝘥𝘳𝘰𝘤𝘬 → 𝘈𝘐𝘖𝘱𝘴 Across the overall observability stack, the #Datadog bill was 𝗿𝗲𝗱𝘂𝗰𝗲𝗱 𝗯𝘆 𝗿𝗼𝘂𝗴𝗵𝗹𝘆 𝟳𝟬% this quarter. Prompt caching cut inference spend by more than half. That architecture is a natural fit for observability. The workload is data-intensive and cost-sensitive, and telemetry volumes can change quickly, making elastic scaling a regular requirement rather than an edge case. AutoMQ's S3-backed, stateless Diskless Kafka architecture addresses these pressures: durable data sits in object storage rather than on broker-local disks, while compute can scale without moving large volumes of partition data. We're seeing more companies adopt AutoMQ for observability, and a clear pattern is emerging: Diskless Kafka is becoming a core architectural pattern for modern observability data stacks. It's also exciting to see Adobe use Kafka as the streaming backbone for an observability + AI stack, connecting high-volume telemetry with AIOps. Congratulations to Pranshu and the Adobe team, and thank you for sharing the architecture. 👉 See Pranshu's original post for the full implementation: https://lnkd.in/p/dEGrAAmm 🌐 Go under the hood of AutoMQ's diskless Kafka architecture: Kafka-compatible streaming backed by object storage, designed to reduce data movement and broker-local disk operations: https://lnkd.in/gmXZJaUd How are you using Kafka to build a modern observability platform? I'd be interested to compare approaches across telemetry ingestion, storage, query, and AIOps. #AutoMQ #Kafka #Observability #AIOps #Adobe #Datadog
- LINKEDIN · IMAGESince 10 Jul 2026
We’re excited to share that AWS has officially published AutoMQ’s Partner Success Story featuring FunPlus. AutoMQ is an AWS Differentiated Partner and is available on AWS Marketplace, so AWS customers can subscribe to AutoMQ directly through their existing cloud procurement workflow. The newly published AWS Partner Success Story highlights FunPlus, a global interactive entertainment company behind games such as State of Survival, King of Avalon, Guns of Glory, and DC: Dark Legion. For gaming platforms running high-throughput Kafka workloads on AWS, cost is often hidden in the network path, not only in broker instances. The FunPlus case shows how AutoMQ on AWS helps reduce that pressure: 1️⃣ Reduce cross-AZ traffic fees by changing the Kafka storage and replication model. 2️⃣ Keep Kafka-compatible APIs so existing producers, consumers, and stream processing jobs continue to work. 3️⃣ Run a cloud-native Kafka architecture on AWS while aligning infrastructure spend more closely with workload growth. 🔎 The result: 𝟓𝟎% 𝐥𝐨𝐰𝐞𝐫 𝐊𝐚𝐟𝐤𝐚 𝐜𝐨𝐬𝐭 by reducing cross-AZ traffic fees. 👉 Read the AWS Partner Success Story: https://lnkd.in/gHau9fnp Subscribe on AWS Marketplace: https://lnkd.in/gi_xPM9H For more Kafka and AutoMQ engineering insights, follow AutoMQ on LinkedIn or join the AutoMQ Slack community: https://lnkd.in/gk8txSCU #Kafka #ApacheKafka #AWS #AWSMarketplace #StreamingData #GamingInfrastructure #AutoMQ
- LINKEDIN · IMAGESince 10 Jul 2026
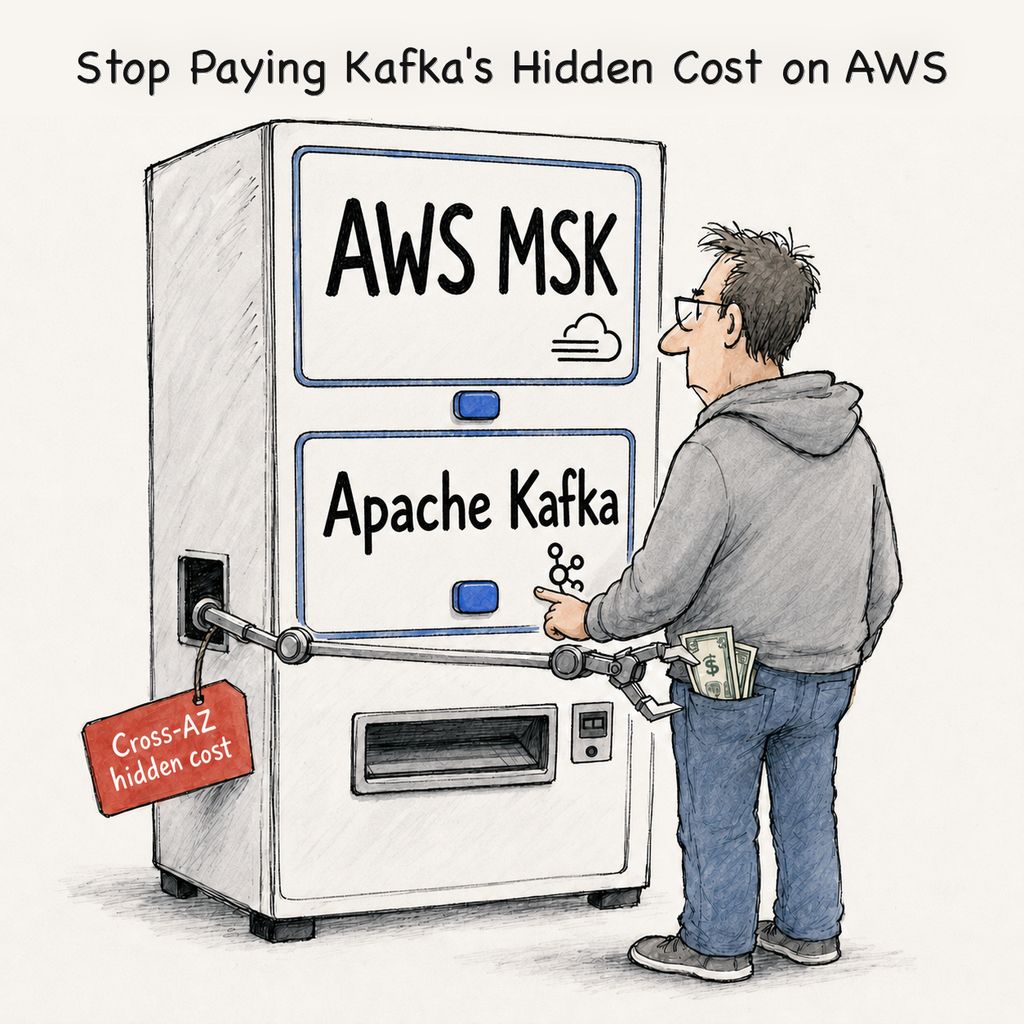
One Kafka cost line I think more teams should check: Data Transfer. If you're running Kafka or MSK across multiple AZs on AWS, some of the most expensive traffic may not show up as a “Kafka” or “MSK” cost at all. It is usually buried under EC2-Other / Data Transfer, mixed with network charges from other services. For a 100 MiB/s Kafka cluster with replication factor 3 and three consumer groups, cross-AZ traffic can add roughly $14K-$24K per month, depending on the read path optimizations in place. Where does it come from? 1️⃣ Producers writing to leaders in another AZ 2️⃣ Inter-broker replication across AZs 3️⃣ Consumers reading from brokers in another AZ Some tuning helps, especially for reads. But the replication traffic is architectural. Traditional Kafka stores replicas on brokers, so multi-AZ durability means broker-to-broker data movement. That is the part AutoMQ removes with Diskless Kafka: data persistence moves to object storage, brokers become stateless compute, and cross-AZ replication traffic is eliminated at the root. Full breakdown: https://lnkd.in/dSwGqUci #Kafka #ApacheKafka #AWS #MSK #CloudCosts #DataEngineering #AutoMQ
- LINKEDIN · IMAGESince 6 Jul 2026
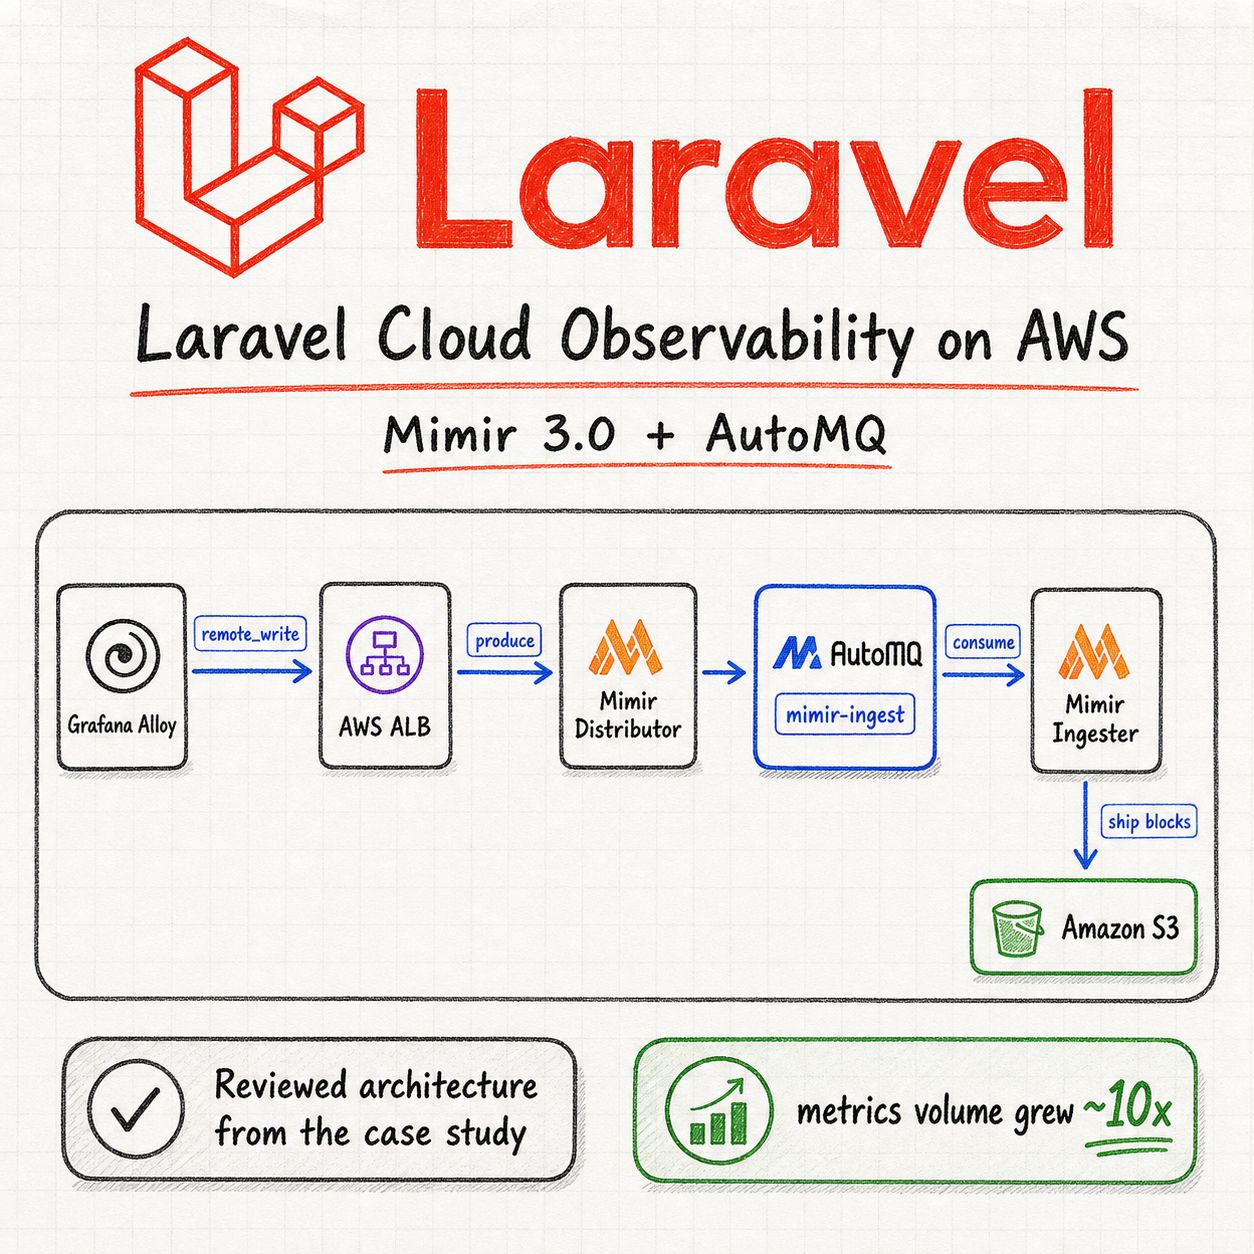
Laravel Cloud now runs AutoMQ with Grafana Labs Mimir 3.0 to power its next-generation observability platform. Here is the story from Florian Beer, Engineering Team Lead, SRE at Laravel. As Laravel Cloud grew, its observability platform had to cover platform services, customer workloads, alerting, and incident response across clusters and nodes worldwide. With hundreds of thousands of metric samples arriving every second, the write path needed to scale without turning Kafka broker disks into the next bottleneck. In the article, Laravel shares how it built that path on AWS with Grafana Mimir 3.0 and AutoMQ: 1️⃣ Mimir ingest storage lets writes land in Kafka before ingesters consume them, so entry writes and backend consumption can scale on separate paths. 2️⃣ A traditional Kafka layer would still bring replicated EBS capacity, broker-to-broker cross-AZ traffic, local log recovery, partition movement, and replica catch-up into the middle of the observability stack. 3️⃣ AutoMQ keeps the Kafka-compatible interface Mimir expects while storing Topic data in S3, so the Kafka buffer follows the same object-storage direction as Mimir long-term blocks. After rollout, Laravel Cloud's metrics volume grew by roughly an order of magnitude, while the entry write path, AutoMQ, and ingester consumption side could still scale independently. 👉 Read the full blog: https://lnkd.in/gJHJhfKT For more Kafka and AutoMQ engineering insights, follow AutoMQ on LinkedIn or join the AutoMQ Slack community: https://lnkd.in/gk8txSCU #GrafanaMimir #LaravelCloud #Kafka #AutoMQ #DisklessKafka #Observability #AWS
6 of 23 adsSign up to see every AutoMQ | Low Latency Diskless Kafka® on S3 ad, filter by format and date, and get alerts on new ones.
See all 23 adsWatch the companies you care about.
Filter every ad by industry, country, format and network, and get alerts when a company you watch starts running new ads.