Not on air · 2 of 3 networks checked
webAI
- webai.com
- Software Development
- US
- 188 employees
webAI’s ads on LinkedIn, Meta and Google, recorded by adsrunning. Browse the latest here for free. Sign up free to see all 383. Watch webAI on any plan to get each new one in your feed.
Watchlist included in every plan
| Network | Status | Live ads | Nov 2025LinkedIn activity · 52 weeksNov 2026 | Checked | Next step |
|---|---|---|---|---|---|
| None recorded | 0 | Checked 3 Nov 2026 | See all 383 ads → | ||
| Meta | Not checked | — | |||
| Recently | 50 | Ads on the Google Ads Transparency Center | Checked 15 Oct 2026 | Collect them with the API → |
webAI has no live LinkedIn ads. We recorded 50 Google ads on 15 Oct 2026.
Latest ads
- LINKEDIN · IMAGESince 30 Oct 2026
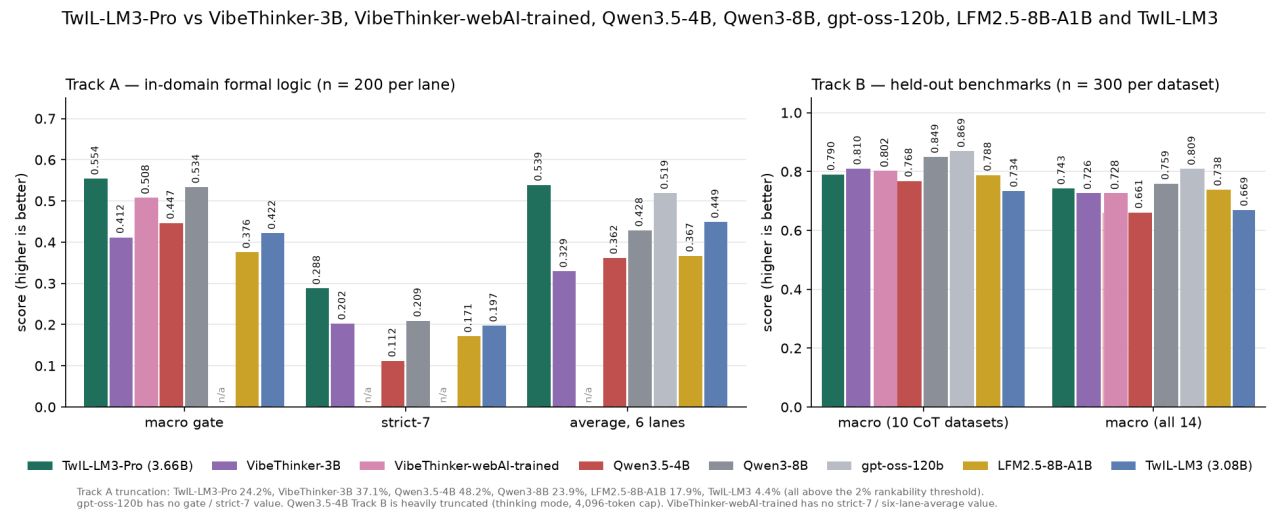
Base-conversion arithmetic breaks most small reasoning models. There’s no base-10 shortcut, so every carry has to be worked through directly in the target base. Most small models skip the carry logic, or convert back to base-10 at the end and hope. TwIL-LM3-Pro doesn’t. It walks each step in the target base and holds state across the derivation. The same pattern shows up across our full formal logic suite. TwIL-LM3-Pro leads every model we tested on in-domain formal logic, including Qwen3-8B at 2x the parameters, gpt-oss-120b at 33x the parameters, and both VibeThinker variants. A 3.66B model built for formal reasoning, beating models 33x its size at it. And even on held-out general reasoning benchmarks we didn’t build for, it stays competitive with those same larger models. Pattern matching gets you fluent answers. Formal reasoning gets you right ones. Open weights, runs locally. Download the model on Hugging Face: https://lnkd.in/g7en57Cq
- LINKEDIN · IMAGESince 26 Oct 2026
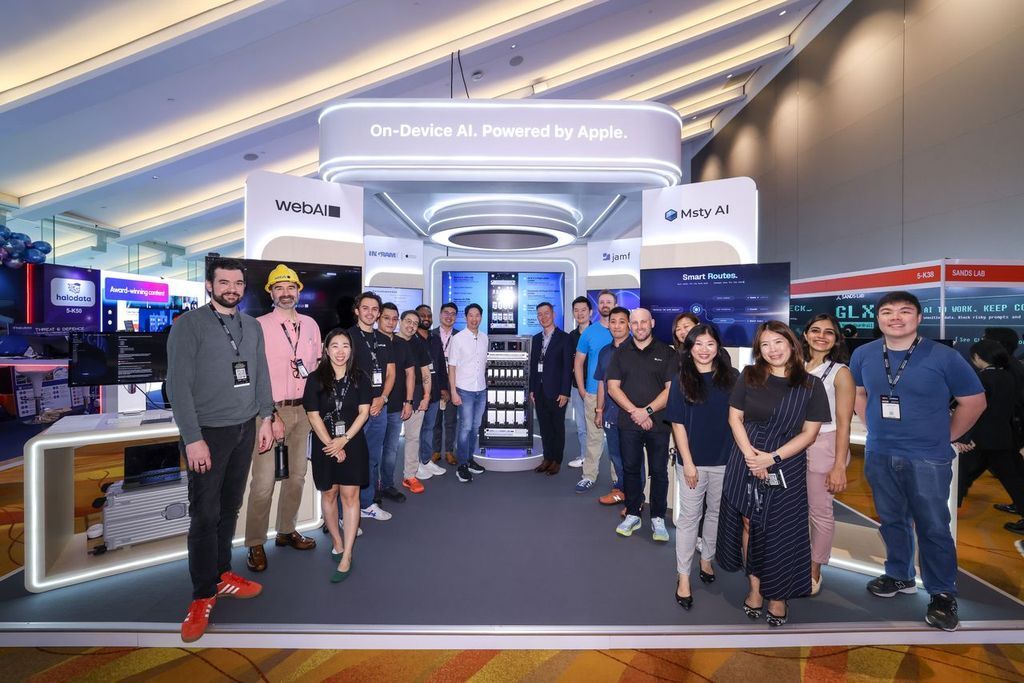
Nothing hits like a live demo. webAI Frontline ran in front of thousands at Singapore Tech Week, inside the “On-Device AI. Powered by Apple.” booth. We shared the floor with Ingram Micro, Msty AI, and Jamf. Workers in aviation, manufacturing, defense, and energy need the right page of the right manual, right now, with no signal. That’s what Frontline does on an iPad, cited and offline, in under 2 seconds. Good company to be in. See you next year, Singapore! 🇸🇬 Team: Josh Arguello, Stephen Westerfield, and Taggard A.
- LINKEDIN · VIDEOSince 22 Oct 2026
Think For Yourself. AI shouldn’t do that for you. It should help. The more we lean on general-purpose AI, the more our work starts to look like everyone else’s. The things that make your work different, the things that make it worth paying attention to, aren’t on the internet. They live in you. That’s what webAI is built on: https://lnkd.in/g-qpFXtK
- LINKEDIN · IMAGESince 21 Oct 2026
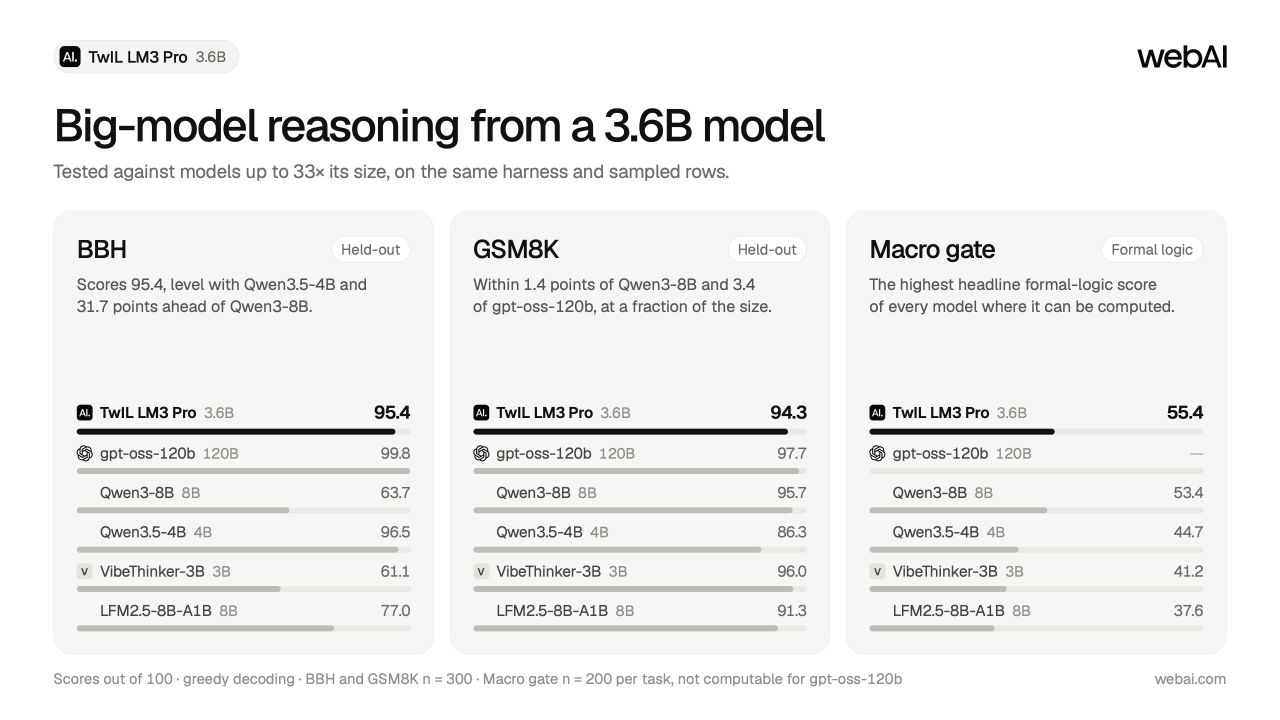
Most of the AI conversation is about scale. Bigger models, more parameters, longer context windows. The assumption being that bigger is smarter. We’ve been building toward the opposite. TwIL-LM3-Pro is a 3.6B reasoning model that handles formal problems models 7 to 10x its size struggle with, and it runs on a laptop. Small isn’t a compromise. For the problems we care about, it’s the point. A model that fits in RAM, answers in seconds, and can be understood end to end gets us closer to what AI should actually be: specialized, local, and yours. Download the model on Hugging Face: https://lnkd.in/gvHMZK5w
- LINKEDIN · VIDEOSince 17 Oct 2026
How does a 3B parameter model compete with frontier models? In our latest video, our Intelligence Lab team walks through how they built the TwIL reasoning models. The thesis behind formal reasoning, the moment that reshaped their data pipeline, and where the lab is headed next. With Paul J. Maykish, Anurag Daram, and Cutter Dalton. Watch the full video: https://lnkd.in/gdnbRSBy
- LINKEDIN · VIDEOSince 12 Oct 2026
Benchmark I ran on TwIL-LM3-Pro, our 3.6B reasoning model from The webAI Intelligence Lab made with Cutter Dalton Paul J. Maykish and David Stout I tested it against Qwen3.5-9B and Qwen3.8-27B on a CPU-only machine (Intel Xeon, 15 GiB RAM, no GPU). TwIL-LM3-Pro generated tokens 98x faster than Qwen3.8-27B. Results: - TwIL-LM3-Pro (2.24 GB weights): 10.47 tokens per second - Qwen3.5-9B (5.67 GB weights): 4.36 tokens per second - Qwen3.8-27B (16.45 GB weights): 0.107 tokens per second Speed on CPU comes down to how fast you can read the weights. TwIL and Qwen 9B both run at the RAM's memory limit of about 24 GB/s. Qwen 9B is 2.4x slower only because its weights are 2.5x larger. Qwen 27B's 16.45 GB of weights don't fit in the 15 GiB of RAM. Parts have to be re-read from disk for every token. Size alone would make it 7.3x slower. The disk reads add another 13x. Total: 98x slower than TwIL. With enough RAM, the gap would shrink to about 7x. But most people don't have unlimited RAM or a top-tier GPU. The model you can actually fit matters more than the one you can't. Download TwIL-LM3-Pro on Hugging Face : https://lnkd.in/gTHZYUSV
6 of 383 adsSign up to see every webAI ad, filter by format and date, and get alerts on new ones.
See all 383 adsWatch the companies you care about.
Filter every ad by industry, country, format and network, and get alerts when a company you watch starts running new ads.