Not on air · 3 of 3 networks checked
Speedata.io
- speedata.io
- IL
- 103 employees
Speedata.io’s ads on LinkedIn, Meta and Google, recorded by adsrunning. Browse the latest here for free. Sign up free to see all 167. Watch Speedata.io with Starter to get each new one in your feed.
Watchlist with Starter · $49/mo
| Network | Status | Live ads | Nov 2025LinkedIn activity · 52 weeksNov 2026 | Checked | Next step |
|---|---|---|---|---|---|
| None recorded | 0 | Checked 29 Oct 2026 | See all 167 ads → | ||
| Meta | None recorded | 0 | No active ads recorded on the Meta Ad Library | Checked 26 Oct 2026 | Collect them with the API → |
| None recorded | 0 | No ads found on the Google Ads Transparency Center | Checked 10 Oct 2026 | Collect them with the API → |
Speedata.io has no live LinkedIn ads. Its Facebook page had no active ads on 26 Oct 2026, and we recorded no Google ads on 10 Oct 2026.
Latest ads
- LINKEDIN · IMAGESince 26 Apr 2026
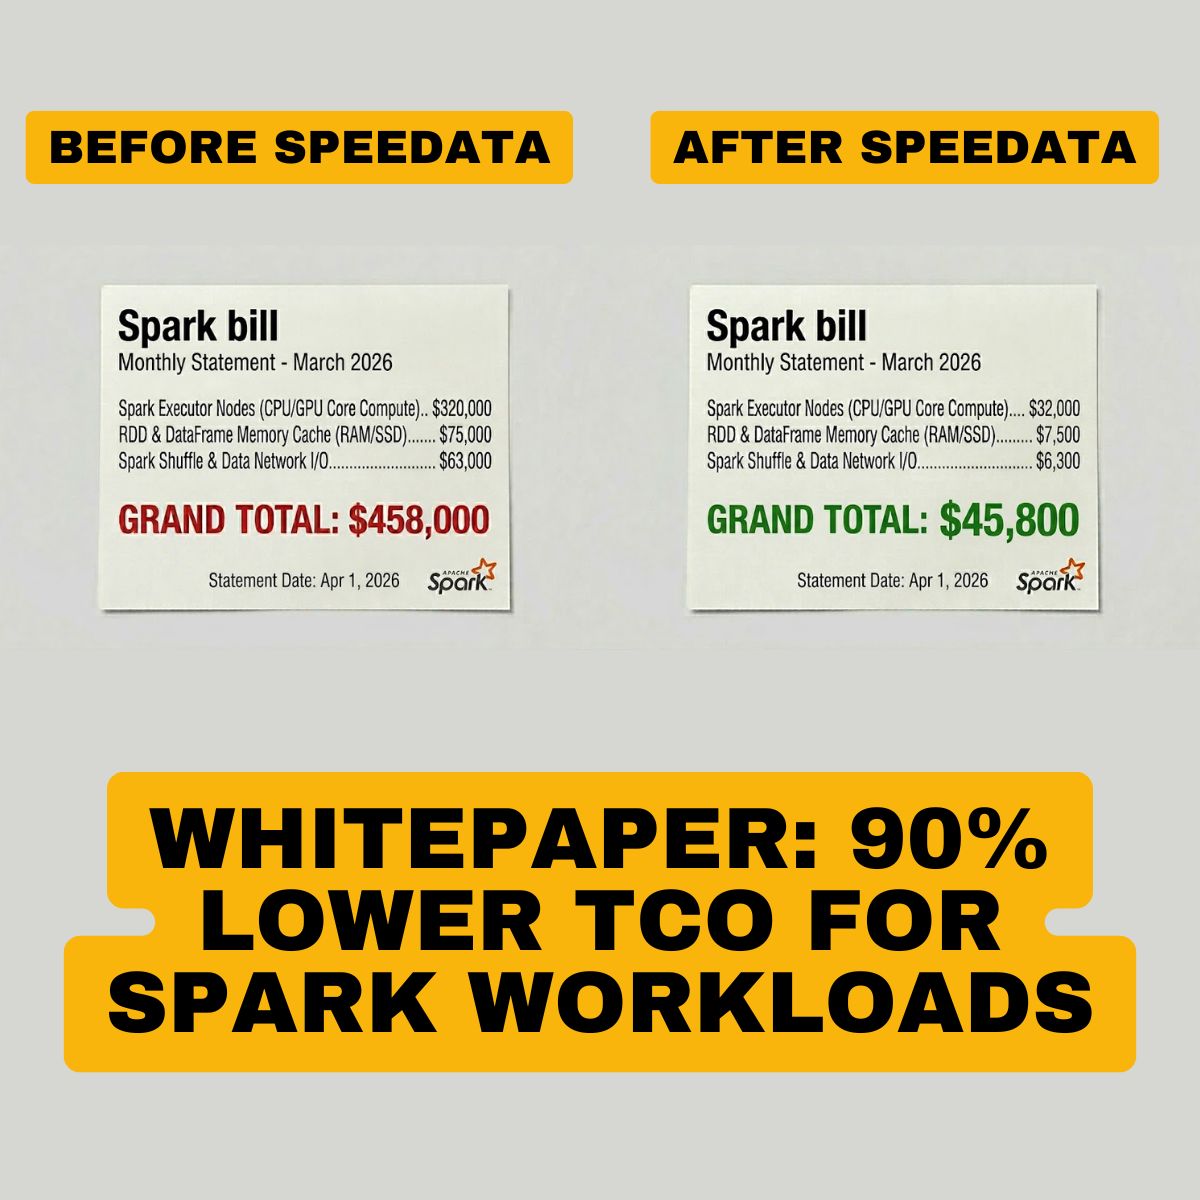
Our white paper reveals how Speedata’s architecture cuts data center costs by 90% while delivering 20x faster analytics - with zero code changes.
- LINKEDIN · IMAGESince 7 Apr 2026
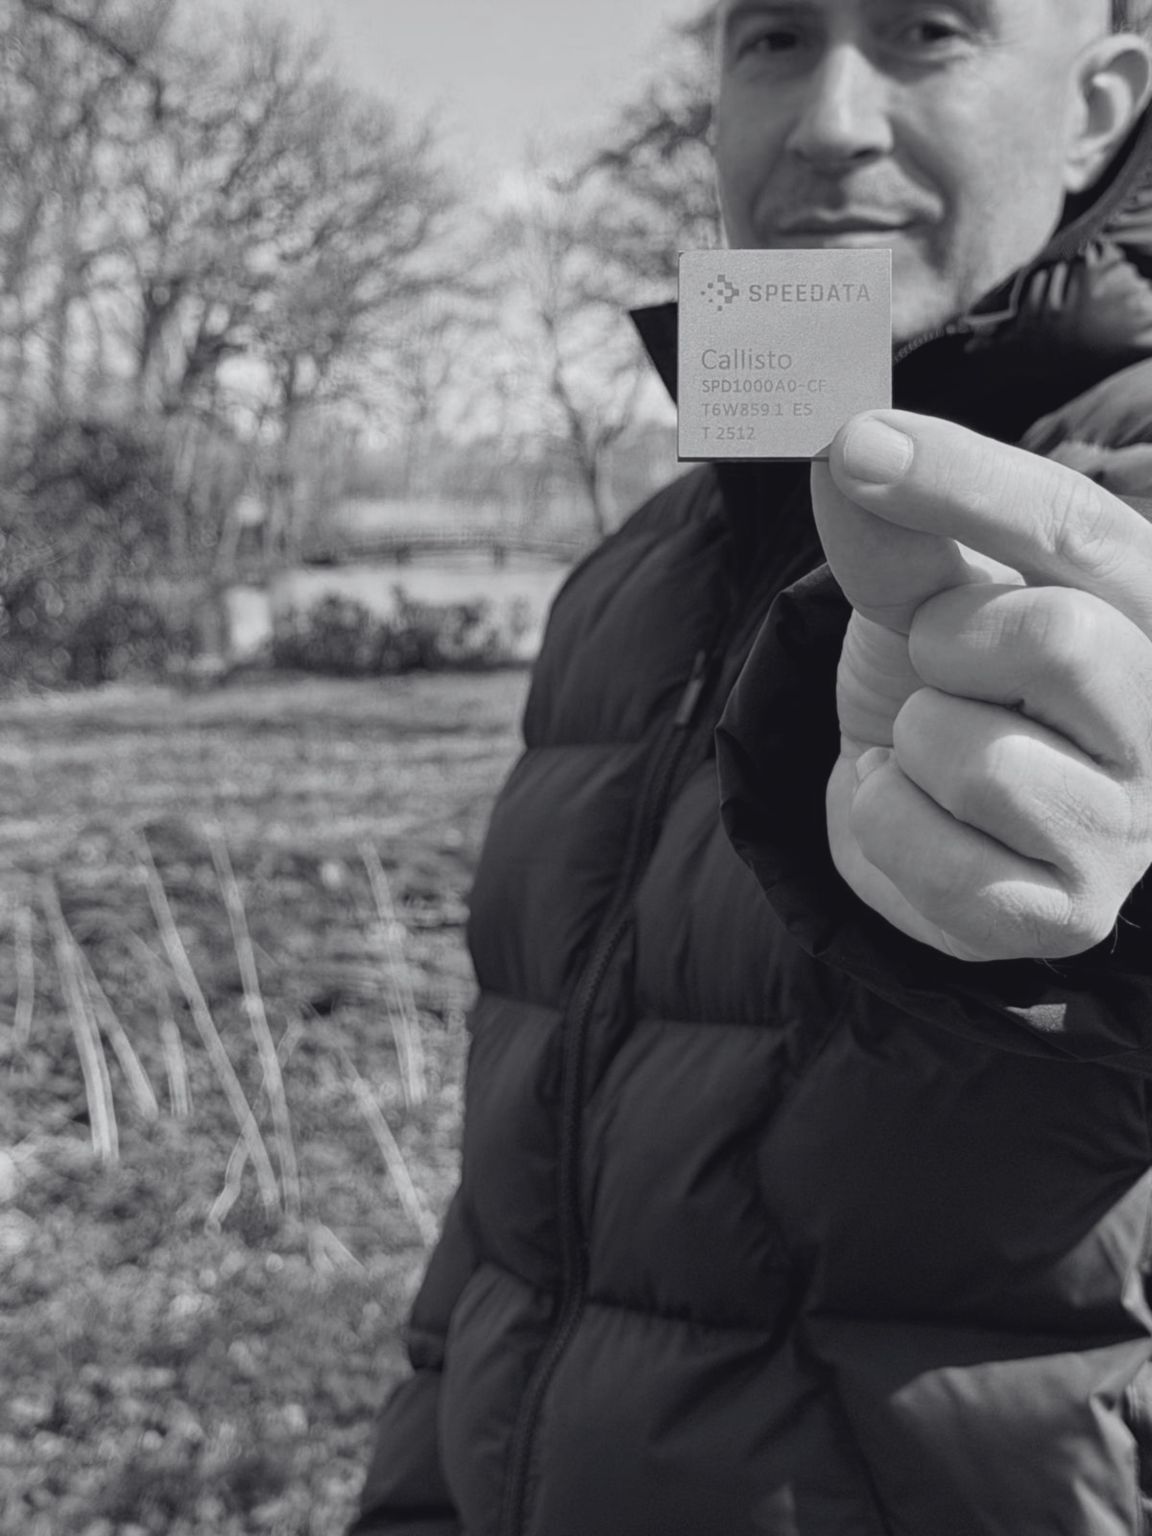
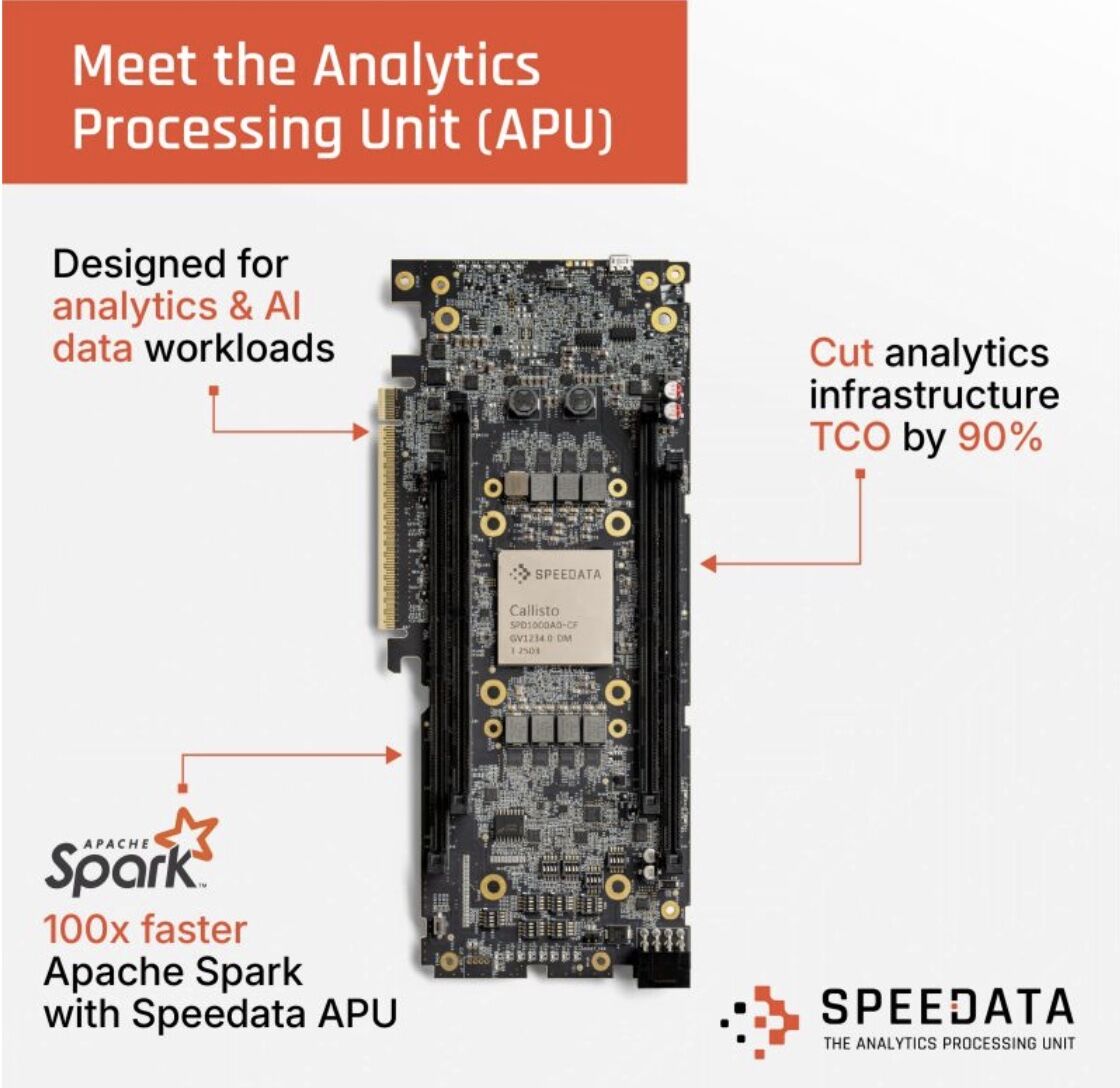
I just showed a data engineering team how to reduce their Apache Spark compute costs by 90% using the piece of silicon I’m holding in my hand. Their current setup: 10 full racks of Spark workers, scaling rapidly, all to prepare data for their AI models. Using our free Spark analysis tool, I demonstrated that by accelerating their Spark with Speedata APUs, they can run the exact same workloads 20× faster on half a rack. 90% less infrastructure. Same data. Same workloads. 20x performance boost @ 10% of their current monthly spend. We can do the same for your Spark environment. DM me or leave your questions/details here: https://lnkd.in/eN-HHw-J Speedata.io
- LINKEDIN · EVENTSince 31 Mar 2026
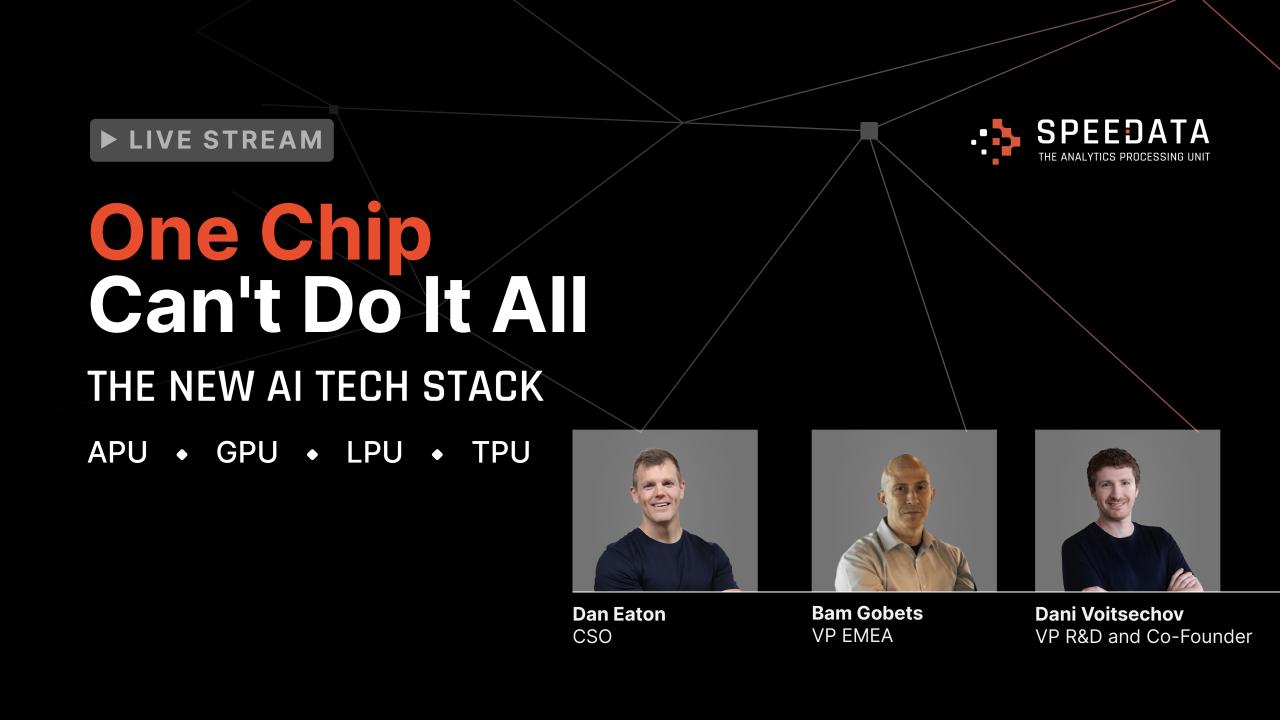
The right chip for the right workload: APUs, GPUs, TPUs, and LPUs each serve a different purpose. Learn where each one fits. Join our Live Stream! 👇
- LINKEDIN · IMAGESince 4 Mar 2026
Our white paper reveals how Speedata’s architecture cuts data center costs by 90% while delivering 20x faster analytics - with zero code changes.
- LINKEDIN · IMAGERecorded 1 Oct 2026
Analytics is about to get its GPU moment. -When AI training hit its scale limit, we didn’t just optimize - we moved to GPUs. -When video streaming exploded, we moved to ASICs. -When general-purpose compute hit its wall, we built Graviton and Maia. Every major workload eventually gets its own hardware. And yet, one of the largest workloads on earth - analytics - still runs on CPUs. Millions of servers spend their days doing the same joins, scans, and aggregations in software that could be done directly in silicon. That’s why we built the Analytics Processing Unit (APU) - purpose-built hardware for Spark and large-scale data processing. No code changes. No re-platforming. Just faster insights at lower cost. In early production deployments: - Workloads complete 50–100× faster - Infrastructure costs drop up to 90% - One telecom cut its cluster from 2,000 servers to 200 The pattern is clear: - Once a workload becomes big and repetitive enough, it moves to specialized hardware. - AI crossed that line years ago. - Analytics just did. If you run large-scale analytics, this shift will change your economics, whether with us or someone else. But if you want to see what that future looks like today, we can show you. 👉 Schedule a call with a product expert: https://lnkd.in/dsc44sj6
- LINKEDIN · IMAGERecorded 1 Oct 2026
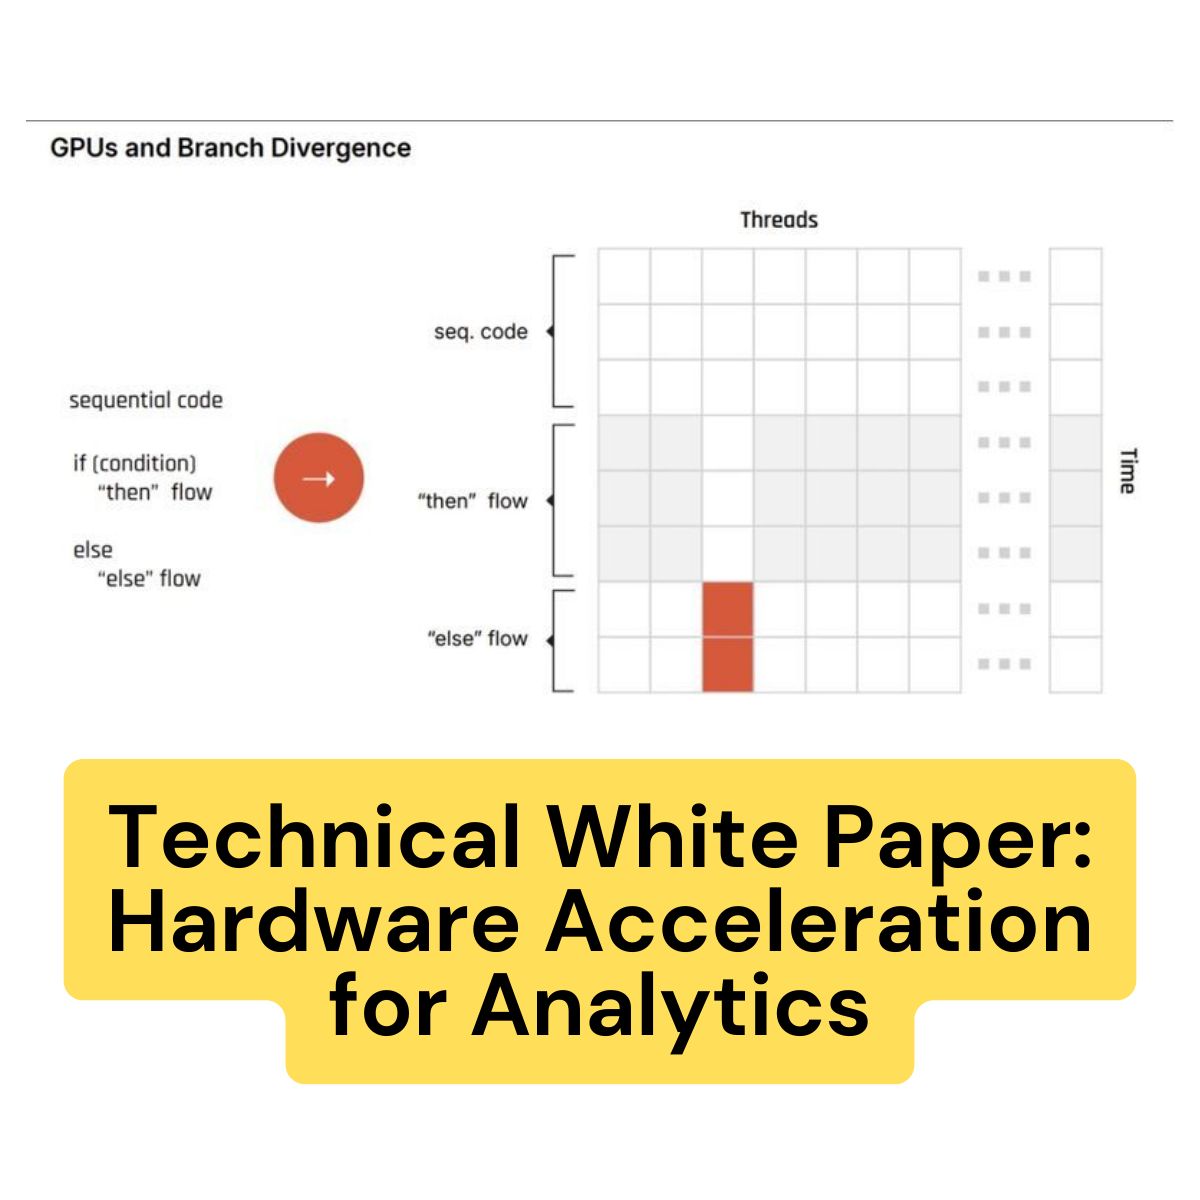
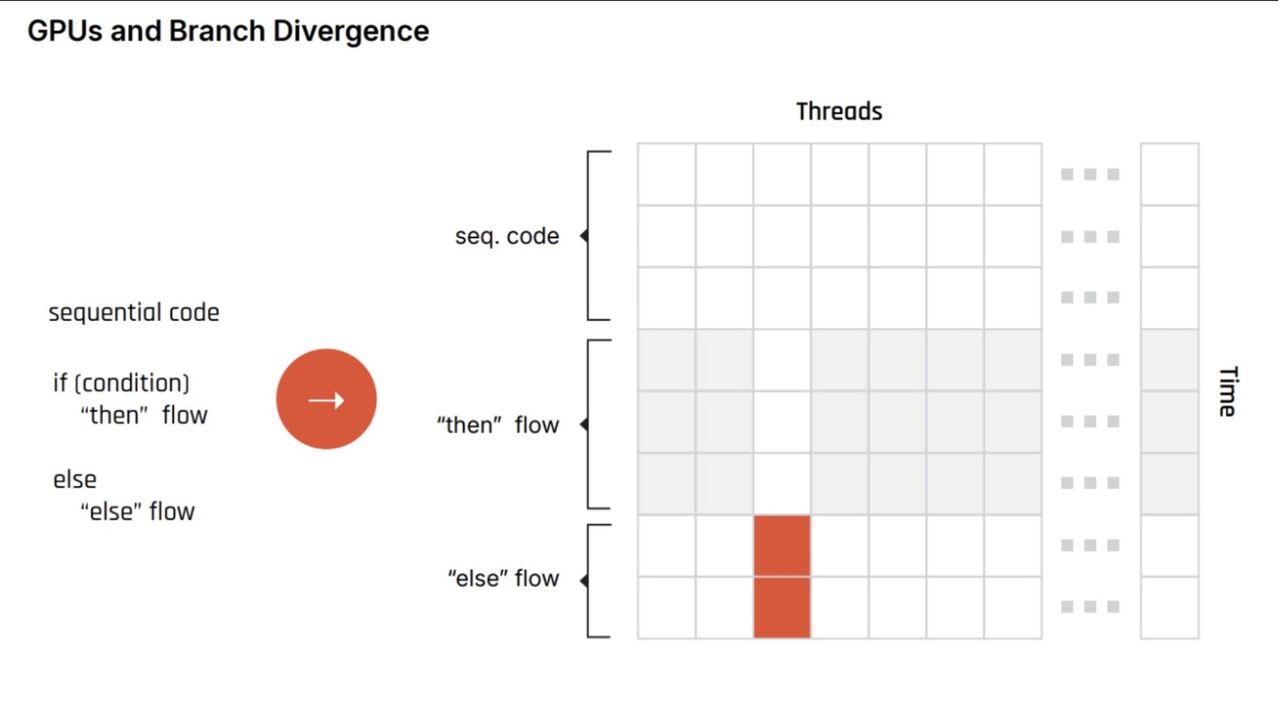
Using a GPU for analytics is like driving a Ferrari in rush hour traffic. The engine is powerful, but you’re constantly slamming on the brakes. It's an engineering mismatch: - GPUs need long, open highways. They are designed for 3D graphics, where every pixel moves in "lockstep" unison. - Analytics is full of intersections. It relies on "if/then/else" logic. Every time your data hits a decision point, the GPU hits a traffic jam. One thread creates a diversion, and the neighboring threads sit idle waiting for it to finish. This phenomenon is called Branch Divergence, and it can waste 80% of your compute cycles. The solution isn't a faster engine - it's a better traffic system. We wrote a technical paper on how Coarse-Grained Reconfigurable Architecture (CGRA) solves this by grouping rows by branch - processing the "ifs" and "elses" on their own dedicated lanes. Read the architectural deep dive here: https://lnkd.in/dwyJY9JP #etl #gpu #analytics #Apachespark
6 of 167 adsSign up to see every Speedata.io ad, filter by format and date, and get alerts on new ones.
See all 167 adsWatch the companies you care about.
Filter every ad by industry, country, format and network, and get alerts when a company you watch starts running new ads.