On air · 2 of 3 networks
DriveNets
- drivenets.com
- IL
- 603 employees
DriveNets’s ads on LinkedIn, Meta and Google, recorded by adsrunning. Browse the latest here for free. Sign up free to see all 713. Watch DriveNets with Starter to get each new one in your feed.
Watchlist with Starter · $49/mo
| Network | Status | Live ads | Nov 2025LinkedIn activity · 52 weeksOct 2026 | Checked | Next step |
|---|---|---|---|---|---|
| Running | 133 | Checked 28 Oct 2026 | See all 713 ads → | ||
| Meta | None recorded | 0 | No active ads recorded on the Meta Ad Library | Checked 19 Oct 2026 | Collect them with the API → |
| Running | 18 | Ads on the Google Ads Transparency Center | Checked 27 Oct 2026 | Collect them with the API → |
DriveNets has 133 live LinkedIn ads. Its Facebook page had no active ads on 19 Oct 2026, and we recorded 18 Google ads on 27 Oct 2026.
Latest ads
- LINKEDIN · IMAGESince 28 Oct 2026
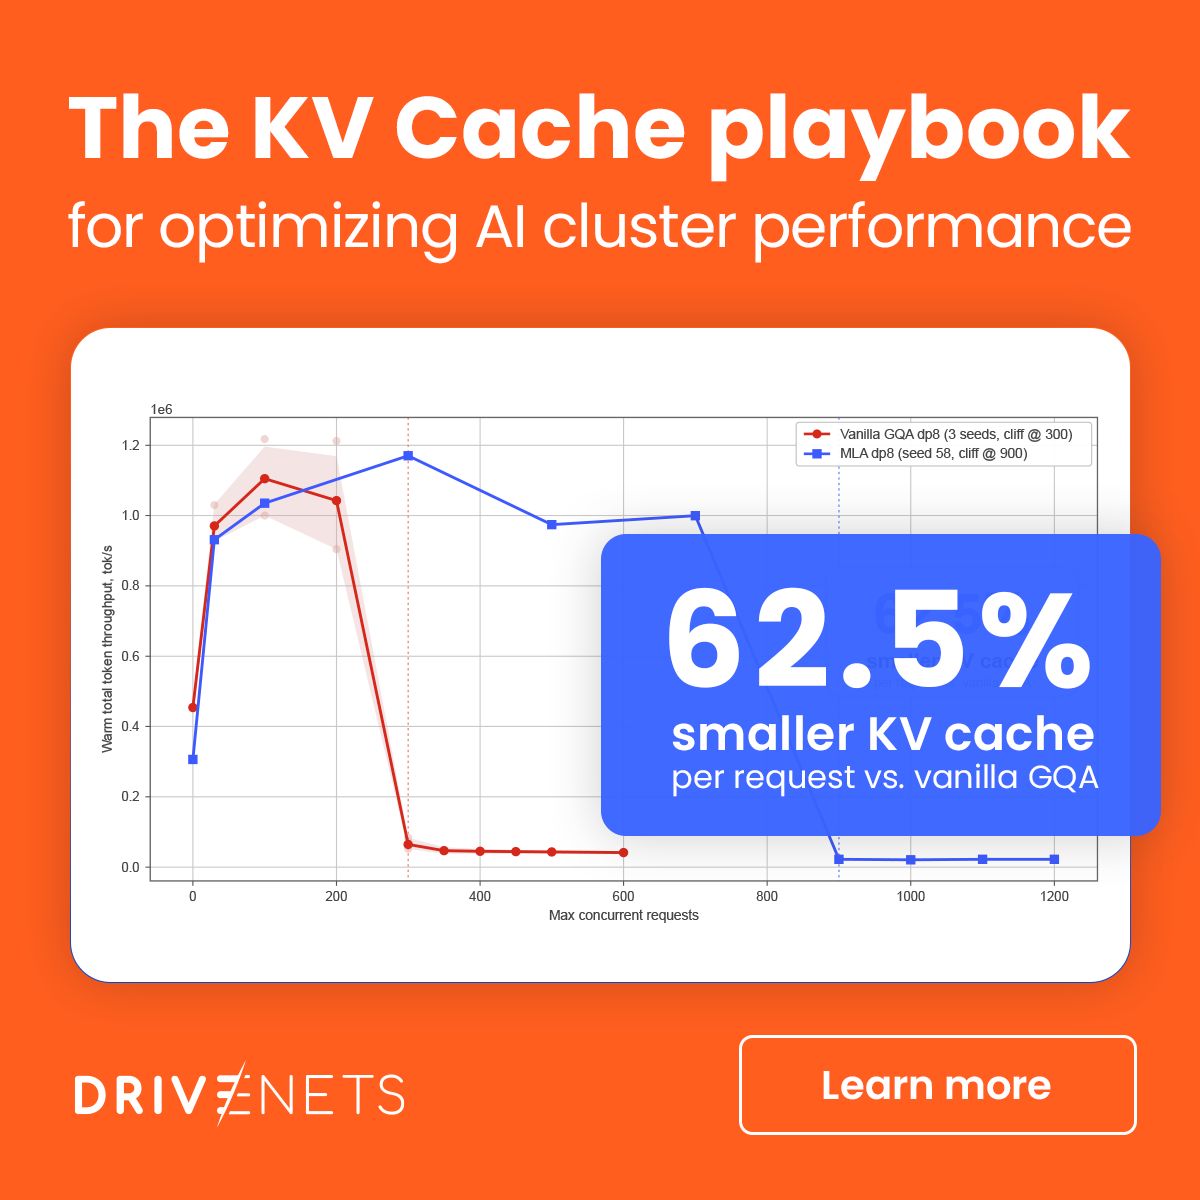
Large language model inference is increasingly becoming a systems problem. Many techniques exist, but three performance drivers matter most: - Shrink it: Reduce the KV-cache footprint - Move it: Transfer KV state efficiently - Reuse it: Avoid unnecessary recomputation One of the most important parts of infrastructure optimization is Key-Value (KV) cache management. This white paper examines how KV-cache size, movement, and reuse affect inference performance. As models grow, context windows expand, and inference architectures become more distributed, delivering better performance is no longer simply a matter of deploying faster GPUs. The infrastructure surrounding those GPUs increasingly determines how efficiently they can serve tokens.
- LINKEDIN · IMAGESince 28 Oct 2026
The next phase of AI will reward those that optimize their entire AI cluster. The most expensive idle asset in AI today is a GPU waiting on data, and no amount of compute budget can fix a cluster bottlenecked by data starvation. This blog explores how cross-vendor full-stack optimization, as demonstrated by the recent DriveNets, AMD and VAST Data collaboration, provides the most complete blueprint for large-scale AI inference infrastructure.
- LINKEDIN · IMAGESince 28 Oct 2026
DriveNets and AMD published a validated Reference Architecture that maximize the performance of AI clusters built with AMD Instinct MI355X GPUs, AMD Pollara NICs, and DriveNets scale-out and frontend solutions. The integrated solution from AMD and DriveNets eliminates networking bottlenecks by performing end-to-end networking optimizations across the entire AI stack, including collective communication libraries, transport protocols, NICs, the network fabric, and system-level orchestration. It maximizes GPU utilization and accelerates TTFT, optimizing AI cluster economics. The joint reference architecture enables: ✔️ 15% faster Time to First Token (TTFT) at the single-node level ✔️ 12–16% faster TTFT at scale ✔️ Up to 5% higher multi-node throughput ✔️ Stronger performance as concurrency increases
- LINKEDIN · IMAGESince 28 Oct 2026
DriveNets will be at SC26 in Chicago! Learn more about how our AI Ethernet fabric supports InfiniBand-level performance, and about our work with AMD. DriveNets' AI networking solutions deliver: Highest E2E performance for AMD based on full-stack optimization DriveNets' Open, lossless Ethernet fabric delivers approximately 5% higher throughput and 10-15% lower TTFT for MI355X GPU clusters, compared to publicly available industry results Fastest deployment time without complex fine-tuning and automated orchestration
- LINKEDIN · IMAGESince 22 Oct 2026
Tata Communications Lanka is carrying live production traffic over a network powered by DriveNets Network Cloud. The deployment in Sri Lanka puts the DriveNets NCPlite white box router into production for Tata Communications Lanka Internet POP network. DriveNets' Technical Delivery Team delivered the solution end to end – from on-site training through design, implementation, HLD/LLD, migration, testing and go-live. The deployment demonstrates how DriveNets can support demanding, loss-sensitive services.
- LINKEDIN · VIDEOSince 8 Oct 2026
DriveNets and AMD published a validated Reference Architecture that maximize the performance of AI clusters built with AMD Instinct MI355X GPUs, AMD Pollara NICs, and DriveNets scale-out and frontend solutions. The integrated solution from AMD and DriveNets eliminates networking bottlenecks by performing end-to-end networking optimizations across the entire AI stack, including collective communication libraries, transport protocols, NICs, the network fabric, and system-level orchestration. The joint reference architecture enables: ✔️ 15% faster Time to First Token (TTFT) at the single-node level ✔️ 12–16% faster TTFT at scale ✔️ Up to 5% higher multi-node throughput ✔️ Stronger performance as concurrency increases
6 of 713 adsSign up to see every DriveNets ad, filter by format and date, and get alerts on new ones.
See all 713 adsWatch the companies you care about.
Filter every ad by industry, country, format and network, and get alerts when a company you watch starts running new ads.