On air · 2 of 3 networks
DataPacket.com
- datapacket.com
- Information Technology & Services
- GB
- 31 employees
DataPacket.com’s ads on LinkedIn, Meta and Google, recorded by adsrunning. Browse the latest here for free. Sign up free to see all 24. Watch DataPacket.com with Starter to get each new one in your feed.
Watchlist with Starter · $49/mo
| Network | Status | Live ads | Nov 2025LinkedIn activity · 52 weeksNov 2026 | Checked | Next step |
|---|---|---|---|---|---|
| None recorded | 0 | Checked 30 Oct 2026 | See all 24 ads → | ||
| Meta | Running | 1 | Active ads on the Meta Ad Library, all countries | Checked 27 Oct 2026 | Collect them with the API → |
| Running | 64 | Ads on the Google Ads Transparency Center | Checked 26 Oct 2026 | Collect them with the API → |
DataPacket.com has no live LinkedIn ads. Its Facebook page had 1 active ad on 27 Oct 2026, and we recorded 64 Google ads on 26 Oct 2026.
Latest ads
- LINKEDIN · IMAGESince 9 Oct 2026
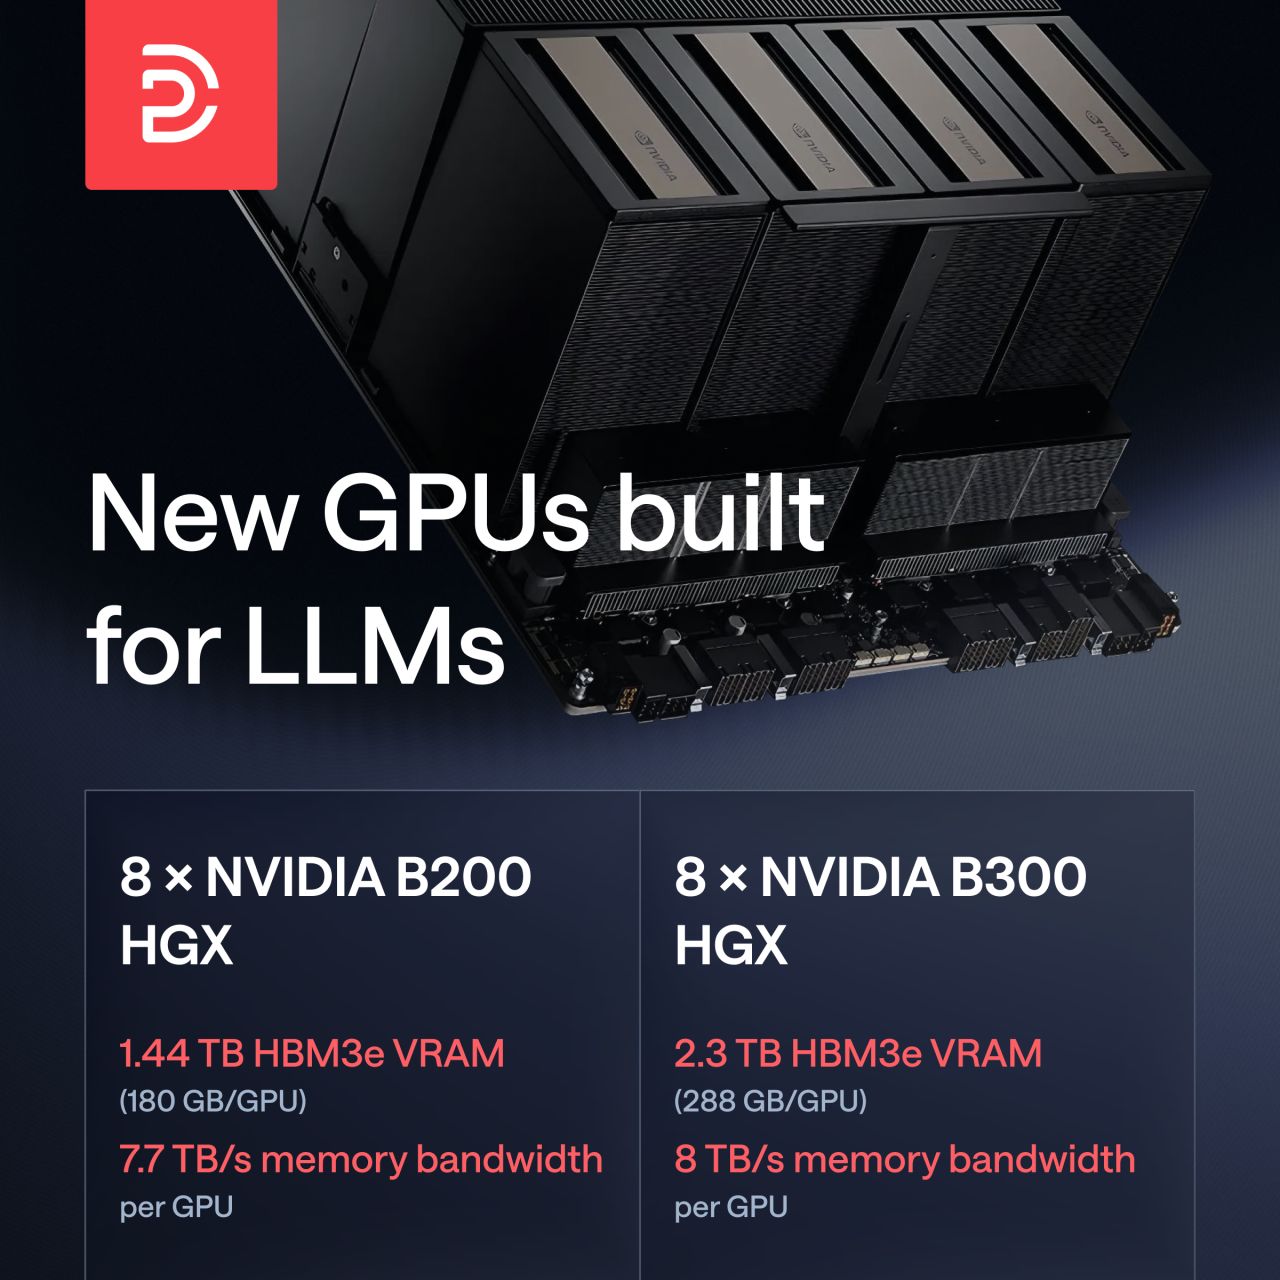
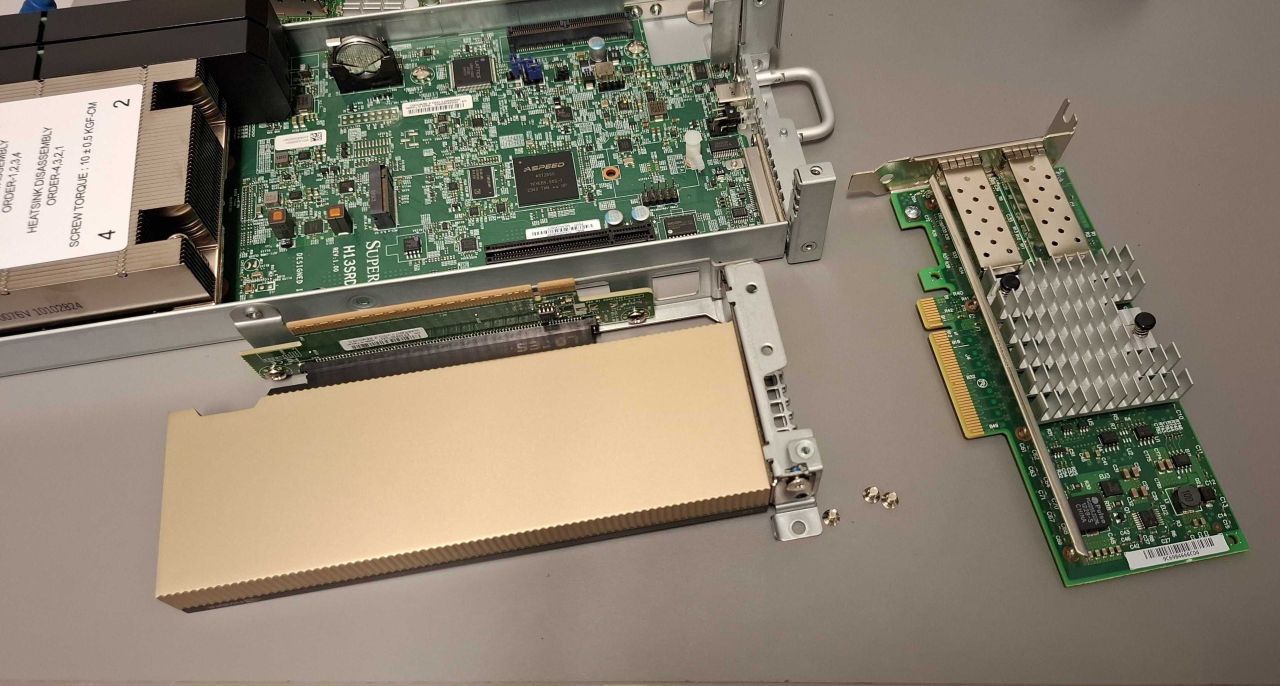
We’ve added NVIDIA B200 HGX and B300 HGX to our server configurator. The new Blackwell architecture GPUs are designed for your most demanding AI and HPC workloads, and they give you the firepower to train, tune, and serve models at scale. 🔗 Find their full specs here: https://lnkd.in/eAR3mP8m
- LINKEDIN · IMAGESince 9 Oct 2026
I’m heading to NVIDIA GTC Berlin, 20–22 October, to meet teams running AI in production. Running AI in production takes both GPU performance and the network to deliver it. Where your compute sits and how traffic reaches it matter as you scale across regions. This is what we do at DataPacket: dedicated GPU and CPU servers on our own network, across 67 locations with 300+ direct interconnects to carriers and ISPs. We fit the service to the workload, whether that’s a few GPUs in a new region, better routes, or more flexible terms. If you’re deciding where inference runs next, let’s talk in Berlin. DM me.
- LINKEDIN · IMAGESince 9 Apr 2026
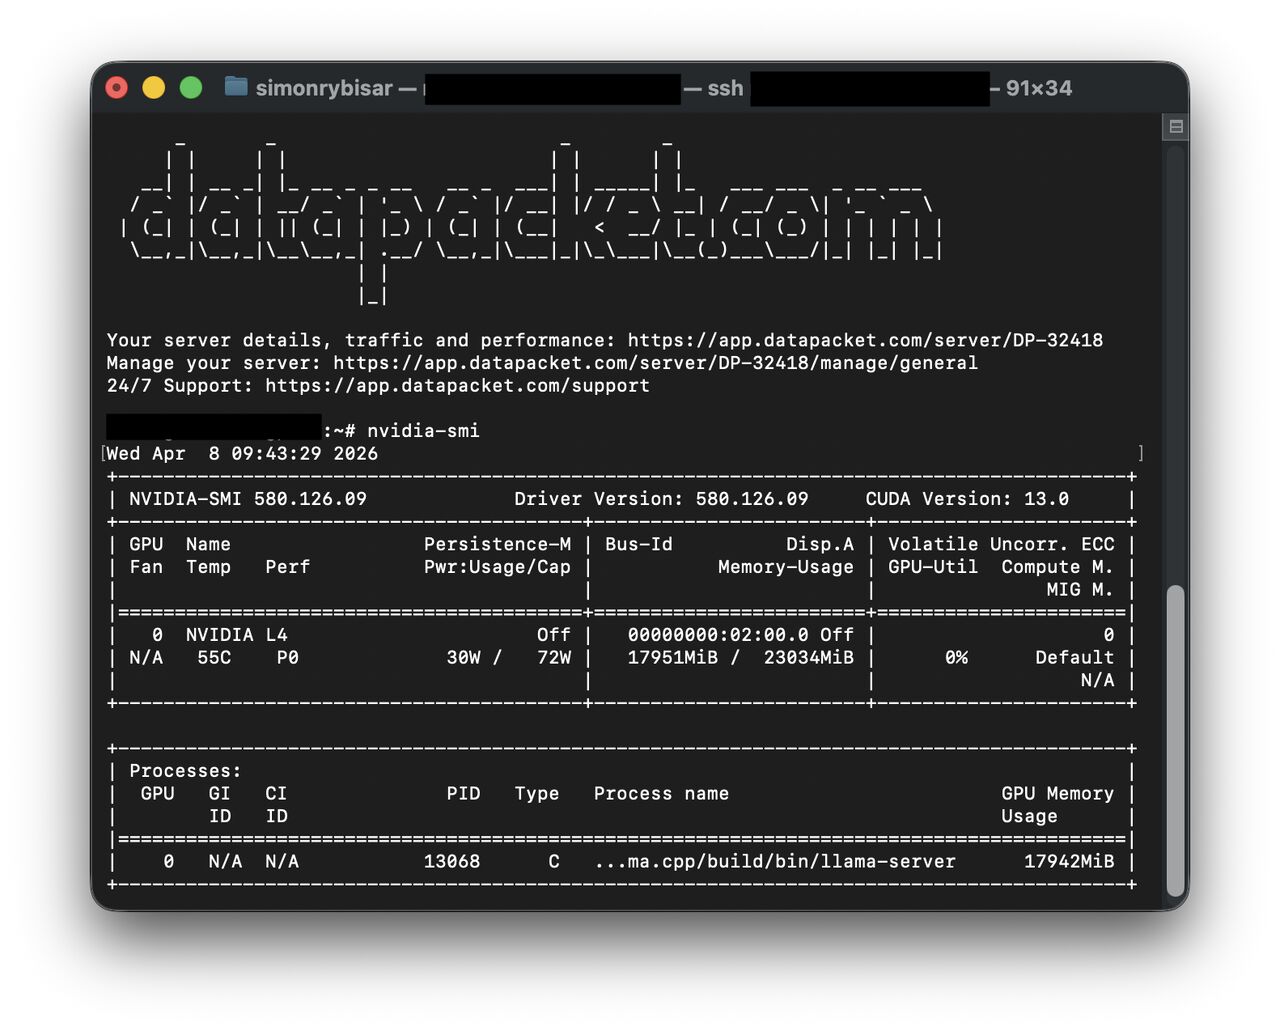
Gemma 4 landed on April 2. The 26B-A4B variant is the one to watch. 26 billion parameters total, ~4 billion active per token. It's a Mixture-of-Experts model. At 4-bit quantisation, the model weights land in the mid-to-high teens for VRAM, which puts it in range of a single NVIDIA L4 (24 GB) with room left depending on your context length and runtime stack. I tested it on one of our L4-equipped servers in Amsterdam & it runs as expected. One thing to know: Gemma 4 is already supported in vLLM, but quantised MoE support is still uneven. Today, GGUF via llama.cpp is the cleaner path for this setup. Unsloth's UD-Q4_K_XL and bartowski's Q4_K_M both fit. Apache 2.0 license. No platform lock-in, no call-home. Your hardware, your data. A current-generation open model on a mid-range GPU. No H100 required. We have L4 bare metal servers in 14 locations today and are actively restocking across nearly all of our 67 sites globally. Many more will become available in the next 2 weeks. Starts at $373/mo (~$0.51/hr).
- LINKEDIN · IMAGESince 6 Apr 2026
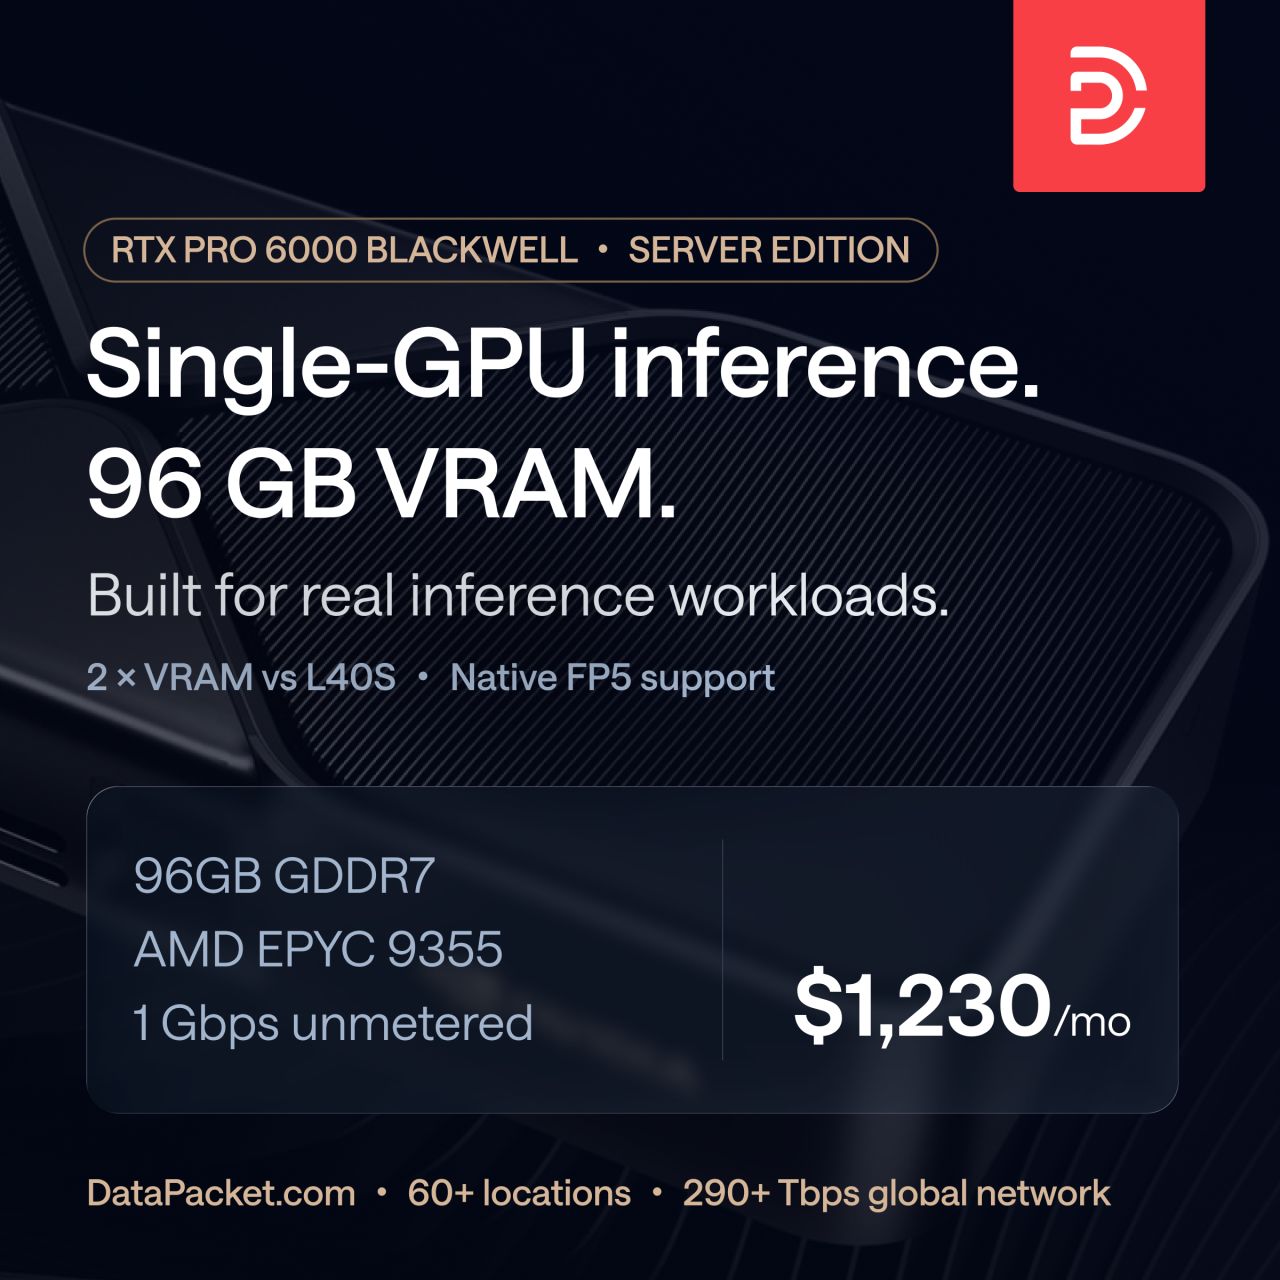
The RTX PRO 6000 Blackwell is quietly becoming one of the most interesting single-GPU inference cards available. We’ve been benchmarking it internally against L40S, and on quantised LLMs and embedding workloads, it consistently delivers higher throughput while offering 2× the VRAM and native FP4. Where it stands out: • LLM inference (quantised models) • high-throughput embedding / RAG pipelines • multimodal inference • diffusion and image generation 96 GB VRAM means larger batch sizes without multi-GPU complexity. The tradeoff: PCIe only, no NVLink. But for single-GPU inference, the performance-per-dollar is hard to ignore. We’re deploying these across multiple locations now, and demand has been strong. A very efficient single-GPU inference setup, without long-term commitments. DM me if you want to run this in your stack.
- LINKEDIN · IMAGESince 25 Feb 2026
Not everything needs an H100. We just freed up 120x NVIDIA L4 GPUs in Prague. We focus on low-latency delivery everywhere. That means distributing GPUs to edge locations across our 67 global sites so customers get lightweight inference wherever they need it. But for now, these L4s are available in Prague for short or long-term rental. Sweet spot for LLM and vision inference, embeddings/RAG, and video transcode when efficiency matters more than peak FLOPS. ~485 TFLOPS FP8 (about 1/4 an H100) 24GB GDDR6 NVENC/NVDEC for efficient encode/decode Paired with EPYC 4464P (12-core Zen 4) Ready to deploy today. DM me if you want specs or availability.
- LINKEDIN · IMAGESince 16 Feb 2026
Proof-of-Stake networks depend on reliable infrastructure to stay secure and stable. Chorus One uses DataPacket.com servers to keep their staking operations running smoothly, with no downtime. 👉 Read the full case study: https://lnkd.in/e-sAD-Ne
6 of 24 adsSign up to see every DataPacket.com ad, filter by format and date, and get alerts on new ones.
See all 24 adsWatch the companies you care about.
Filter every ad by industry, country, format and network, and get alerts when a company you watch starts running new ads.